
ATMANRL: Enforcing Faithful LLM Reasoning via Differentiable Saliency
AtManRL: Towards Faithful Reasoning via Differentiable Attention Saliency
ATMANRL is a reinforcement learning framework that enhances the "faithfulness" of Chain-of-Thought (CoT) reasoning by using a differentiable attention mask. It successfully reduces extraneous reasoning tokens by ~45% while maintaining SOTA performance on GSM8K and MMLU benchmarks.
TL;DR
Reasoning traces (Chain-of-Thought) in LLMs are often more "decoration" than "logic." ATMANRL solves this by turning attention manipulation into a reward signal. By training models to reward tokens that actually change the final answer, researchers reduced reasoning length by 45% while maintaining full accuracy, essentially cutting the "yapping" and keeping the logic.
Background: The Faithfulness Gap
When an LLM says "Let's think step by step," does it actually use those steps, or is it just reciting a script before guessing? Research shows that LLMs often exhibit unfaithful reasoning: the CoT looks correct, but the model reaches the answer via internal shortcuts.
Existing Reinforcement Learning (RL) techniques like GRPO focus on the Outcome (Is the answer correct?). ATMANRL introduces a Saliency Reward (Did this specific word help get the answer?).
Methodology: Making Attention Differentiable
The core of the paper is the transformation of ATMAN—a memory-efficient attention manipulation tool—into a learnable training signal.
1. The Strategy
Instead of just checking the final answer, ATMANRL performs a "stress test" on every reasoning token generated during training:
- Suppress: Every token in the CoT is initially suppressed using a negative mask in the pre-softmax attention scores.
- Optimize: The mask is optimized for 200 steps (via SGD) to find which tokens, when "un-muted," most efficiently restore the probability of the correct answer.
- Reward: Tokens that the mask fought hardest to "un-mute" are deemed salient. The model is then rewarded for producing such tokens.
2. Conceptual Architecture
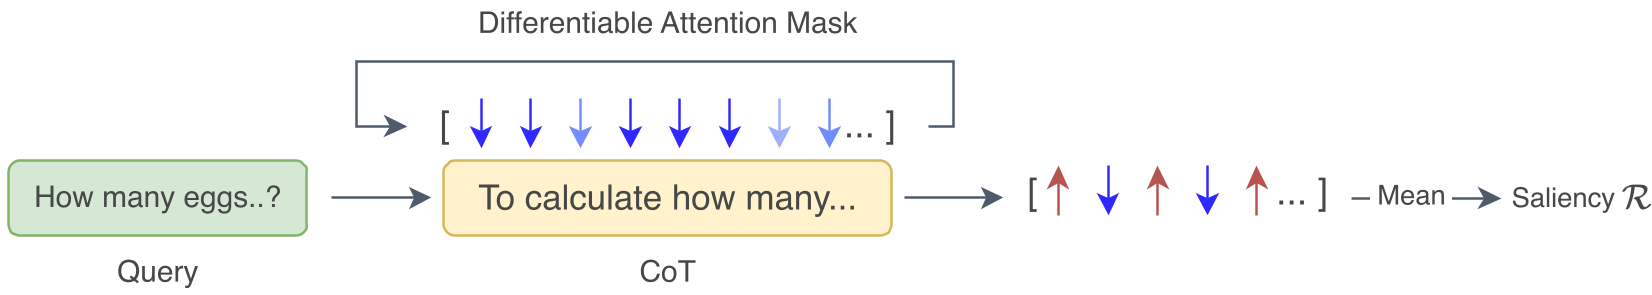 Figure 1: The process of initializing a negative mask and optimizing it to identify influential reasoning tokens.
Experiments: Leaner, Meaner Logic
The researchers tested ATMANRL on GSM8K (math) and MMLU (general knowledge) using Llama-3.2-3B-Instruct.
Key Findings:
- Efficiency: The model learned to be drastically more concise. Average token counts dropped from 186 to 104 on GSM8K (-44%).
- Information Density: On math tasks, the model stopped using "filler" English and increased its usage of numbers (+48%) and symbols (+61%).
- Zero Performance Loss: Despite the massive reduction in "fluff," Pass@4 accuracy remained stable (~90% on GSM8K).
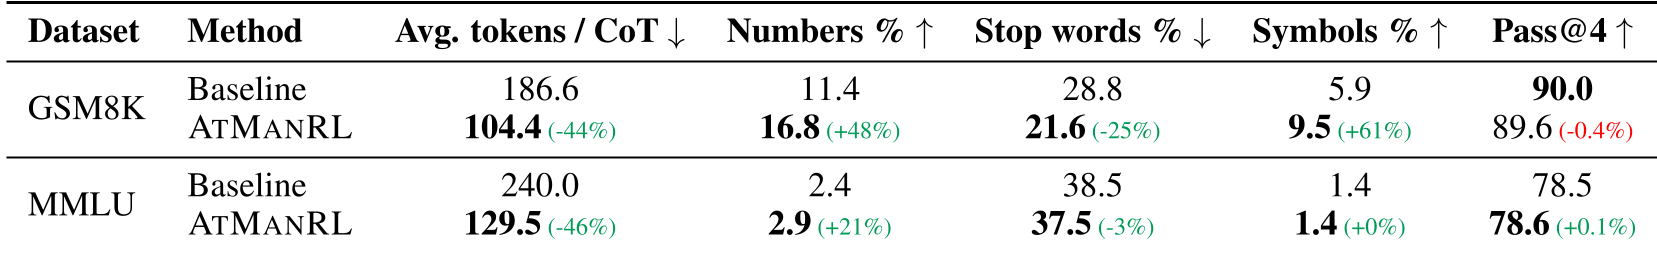 Table 1: Comparison of Baseline vs ATMANRL showing token reduction and linguistic shifts.
Critical Insight: Why This Matters
Most RL for reasoning (like DeepSeek-R1 or o1-style training) encourages "long-form" thinking. ATMANRL provides a necessary counter-balance. It suggests that longer is not always better if the extra tokens don't have causal saliency.
By forcing the model's internal attention to align with its external output, we move closer to "Mechanistic Interpretability-by-design"—where the model's stated reasoning is guaranteed to be a reflection of its internal computation.
Limitations & Future Work
The authors acknowledge a fascinating trade-off: Backtracking. Modern reasoning models are often taught to say "Wait, let me rethink." These self-correction tokens might have low direct saliency to the final logit but high value for the reasoning process. Future versions of ATMANRL will need to distinguish between "useless filler" and "structural self-correction."
Conclusion
ATMANRL represents a bridge between XAI (Explainable AI) and RLHF. It doesn't just ask the model to be right; it asks the model to be honest about how it's right. For developers, this means faster inference and more interpretable traces. For researchers, it’s a new path toward truly faithful AI.