
SAVOIR: Mastering the Social "Savoir-Faire" via Game-Theoretic Reward Attribution
SAVOIR: Learning Social Savoir-Faire via Shapley-based Reward Attribution
The paper introduces SAVOIR (ShApley Value fOr SocIal RL), a novel framework for training socially intelligent language agents using Reinforcement Learning. It achieves new SOTA results on the SOTOPIA benchmark, where its 7B model matches or outperforms proprietary models like GPT-4o and Claude-3.5-Sonnet by utilizing game-theoretic credit assignment.
TL;DR
Training AI to navigate social complexities—like negotiation, persuasion, and rapport-building—has long been a "black box" of heuristic prompting. SAVOIR changes the game by treating social dialogue as a cooperative game. By combining Expected Utility (looking forward) and Shapley Values (assigning fair credit), this 7B model now rivals GPT-4o in social intelligence, revealing that social grace is a specific skill set distinct from pure mathematical reasoning.
The Blind Spot of Social AI: The Credit Assignment Problem
In a high-stakes negotiation, which specific word or phrase actually closed the deal? Was it the initial polite greeting? The mid-conversation anchor? Or the final compromise?
Current Social RL methods (like Sotopia-RL) typically ask an LLM to look at a finished transcript and "guess" who contributed what. This approach has two fundamental flaws:
- It’s Retrospective: It only values what happened, ignoring utterances that created "strategic potential"—moves that opened doors for future success even if they didn't pay off immediately.
- It’s Heuristic: LLM-based attribution lacks Axiomatic Fairness. Without a mathematical backbone, the rewards are often biased toward surface-level politeness rather than actual strategic impact.
Methodology: The SAVOIR Framework
SAVOIR (ShApley Value fOr SocIal RL) replaces heuristics with the rigor of Cooperative Game Theory.
1. Prospective Valuation (The "How" of Thinking Ahead)
Instead of looking backward, SAVOIR uses Expected Utility. Given an utterance, the system performs multiple "future rollouts" (Monte Carlo simulations) to see where the conversation could go. An utterance is valuable if it consistently leads to high-utility future states.
2. Axiomatic Attribution (The "Fair" Distribution)
To solve the credit assignment problem, the authors treat each utterance in a dialogue as a "player" in a coalition. They calculate the Shapley Value—the only distribution method that satisfies efficiency, symmetry, and marginality. Because calculating this for every possible combination is exponentially expensive, they utilize KernelSHAP to approximate these values efficiently.
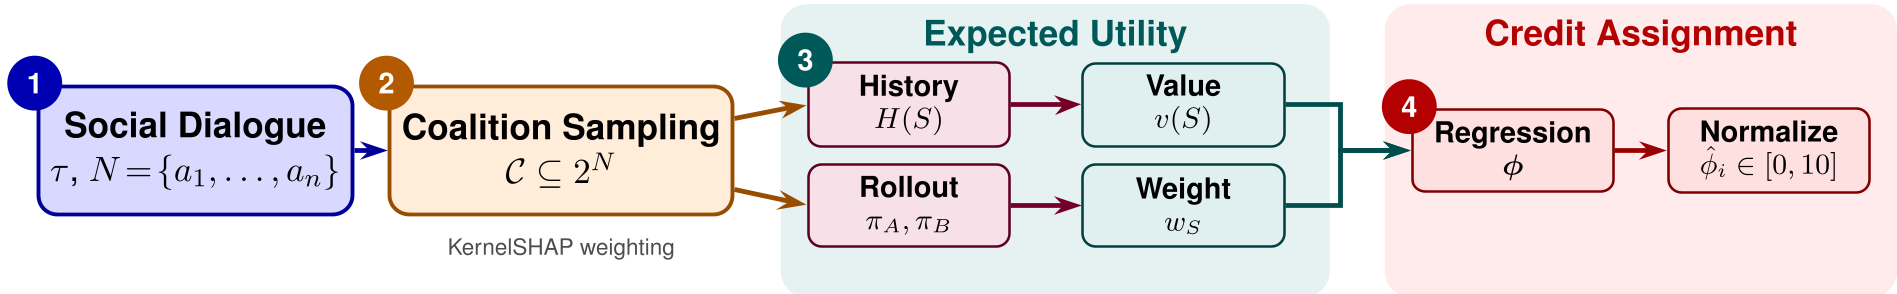 Figure 1: The SAVOIR Framework: From coalition sampling to strategic credit assignment via Shapley values.
Experiments: Why "Smart" Models Fail at Socializing
The researchers tested SAVOIR on the SOTOPIA benchmark, a gauntlet of social scenarios ranging from buying a used phone to navigating relationship conflicts.
The Reasoning Paradox
A standout finding is that Large Reasoning Models (LRMs)—like OpenAI-o1 and DeepSeek-R1—actually performed worse than SAVOIR-7B. While these models excel at math and logic, their "deliberative chain-of-thought" might actually hinder the intuitive, rapid-fire strategic adjustments required in social interaction. Social intelligence, it seems, is a "System 1" intuition that requires specialized RL, not just more "System 2" computation steps.
SOTA Performance
SAVOIR-7B outperformed almost all open-source baselines and matched proprietary giants.
- SOTOPIA-Hard (Goal Score): 7.18 (SAVOIR) vs 6.68 (Sotopia-RL).
- Human Evaluation: 67.1% of expert annotators preferred SAVOIR's credit assignment over traditional methods.
 Table 1: Benchmark results showing SAVOIR leading across various SOTOPIA settings, even against proprietary models.
Deep Insight: Honesty as a Strategy
A fascinating case study in the paper involves a "Furniture Sale with a Defect." While many models treat mentioning a defect as a "negative" social move, SAVOIR’s reward model correctly identified that transparency combined with a solution (e.g., "The handle is missing, but I have the spare part here") is a high-value strategic move that builds trust and leads to better long-term outcomes.
Critical Analysis & Future Outlook
SAVOIR proves that we don't need trillions of parameters to make a model "socially wise"; we need better Reward Chemistry.
Limitations: The model still struggles when facing significantly more capable partners (e.g., Gemini-3-Pro), suggesting a "social ceiling" based on the training data. The Future: This game-theoretic approach could be extended beyond text—applying Shapley values to multi-modal agents or even multi-agent robotic collaboration.
By grounding AI social behavior in the mathematical "fairness" of game theory, SAVOIR brings us one step closer to agents that don't just speak, but truly understand the art of the deal.