
Beyond Probability: A Deterministic Theory of How Models Generalize
Separating Geometry from Probability in the Analysis of Generalization
This paper presents a non-stochastic, deterministic framework for analyzing generalization in machine learning using sensitivity analysis and variational principles. It rederives classical statistical generalization bounds—such as those for SVMs and kernel methods—by treating out-of-sample data as a perturbation of the training set, achieving SOTA matching bounds without relying on unfeasible i.i.d. assumptions.
TL;DR
Generalization is usually explained by the "i.i.d. assumption"—the idea that training and testing data come from the same hidden distribution. This paper flips the script, proposing a completely non-stochastic theory. By viewing machine learning as a problem of sensitivity analysis, the authors prove that we can predict a model's future performance based purely on the geometric relationship between datasets and the stability of the optimization algorithm.
The Problem: The Unverifiable Ghost of i.i.d.
In standard Machine Learning theory, we say a model generalizes if it performs well on a distribution . But there’s a catch: we can never actually see . We only see finite samples. The "distribution" is a mathematical ghost.
When a model fails, we blame "distribution shift." When it succeeds, we credit "interpolation." The authors argue that this reliance on probability theory conflates what we can measure (sample size, loss, norm) with what we cannot (the underlying distribution). They ask a radical question: Can we define generalization without using probability at all?
Methodology: Machine Learning as Parametric Programming
The core insight is to treat the dataset as a parameter in an optimization problem. In this view:
- Training is solving an optimization problem .
- Generalization is understanding how the solution changes when the "parameter" shifts from to .
1. Variational Principles for Interpolation
For models that achieve zero training error (interpolation), the authors define a dissimilarity measure . This measure quantifies how much a function can vary on new data while remaining zero on old data.
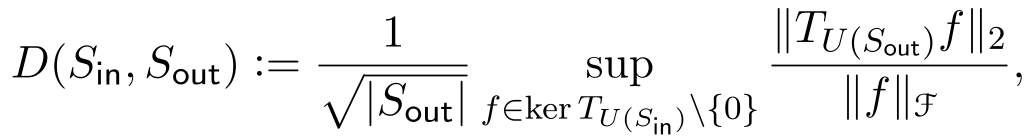 (Formula: Defining the Dissimilarity between samples)
They prove that the out-of-sample error is bounded by this dissimilarity multiplied by the "energy" or norm of the model. This means generalization is a trade-off between Data Geometry and Model Complexity.
2. Duality in Hard-Margin Classifiers (SVMs)
Using Lagrange multipliers and dual optimization, the authors derive a deterministic "leave-one-out" error bound.
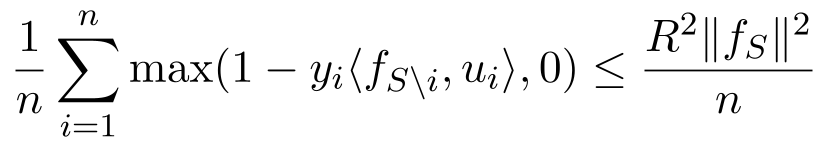 (Formula: Deterministic bound for Support Vector Machines)
Unexpectedly, this deterministic bound results in the same rate found in classical VC-dimension theory, but without needing the data to be random. It implies that if a model is stable (i.e., removing one point doesn't change the solution much), it must generalize.
The Quadratic Growth Assumption
What about non-convex or complex landscapes? The authors introduce the Quadratic Growth Condition. If the loss function grows at least quadratically as you move away from the optimal solution, then the "closeness" of the training solution to the testing solution can be bounded by the Local Lipschitz constant of the generalization error.
Basically, if the optimization surface is "curved" enough at the minimum, the model is naturally resistant to data perturbations.
Experimental & Theoretical Results
The paper demonstrates that their deterministic inequalities are "sharp." In Hilbert spaces, the bound on out-of-sample error actually holds with equality under specific conditions.
The most striking result is Corollary 1, which shows that by taking the expectation of their deterministic bounds after the fact, they perfectly recover the best known probabilistic bounds in the literature.
Critical Insight: Why This Matters
This work shifts the focus from data assumptions (the world is ) to algorithmic properties (the algorithm is stable).
- The Takeaway: You don't need to assume the future looks like the past; you just need to ensure your optimization algorithm isn't overly sensitive to individual data points.
- Limitations: The framework currently relies heavily on Hilbert space structures and specific growth conditions which might be harder to verify in deep neural networks with "flat minima."
- Future Prospects: This opens the door for "Certified Generalization" where a model provides a deterministic guarantee of its error on a specific new dataset based on geometric distance, rather than a vague probabilistic confidence interval.
Conclusion
By separating the Geometry (how data points relate) from the Probability (how data points are generated), Raginsky and Recht have provided a more transparent and mathematically grounded foundation for why machine learning works in the real, non-i.i.d. world.