
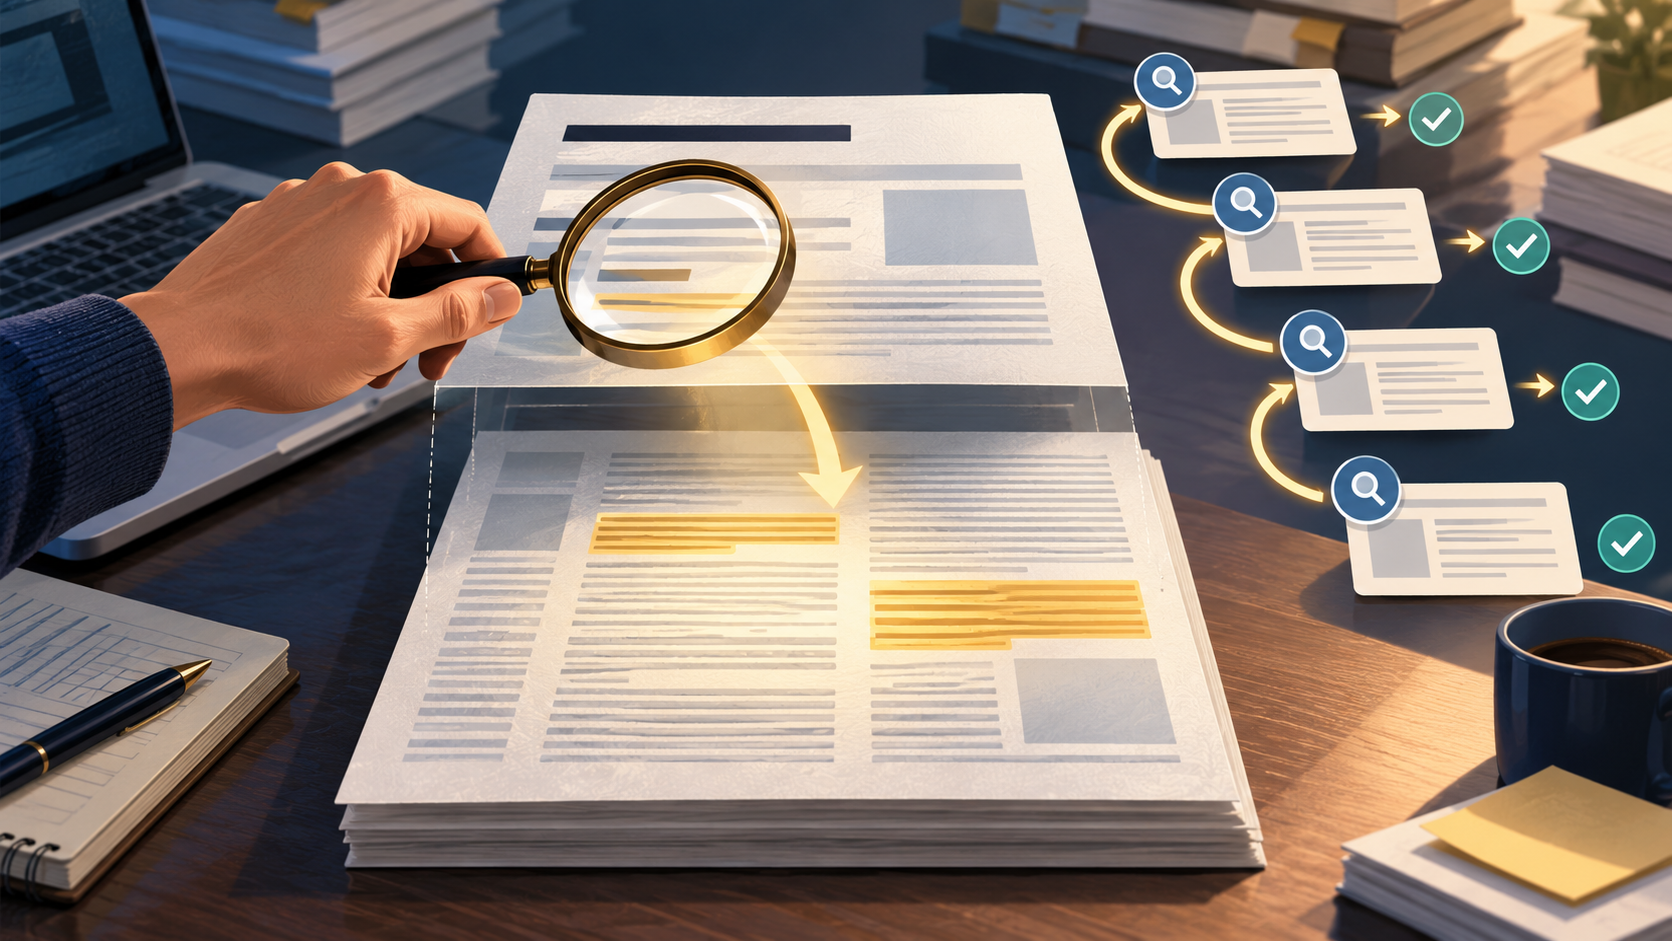
When you are building the evidence base for a manuscript, a review, or a revision, the first real decision is not which database to open but which layer of each record you search. Title-and-abstract search reads the short, structured summary that authors and indexers write to represent a study. Full-text search reads the body of the paper. They fail in different ways, and the practical answer is usually to use them in sequence rather than to pick one.
This article compares the two approaches on the same task and the same criteria: discoverability, noise, terminology, hidden methods details, and auditability. It then gives a staged retrieval strategy, a decision table, and a combined workflow you can adapt to a manuscript or peer-review setting.
The same task, two retrieval layers
Take a concrete case. You are preparing the methods section of a systematic review and need every study that used a particular measurement instrument in a particular population. You also need to know, for each included study, how the instrument was administered, because that detail determines whether two studies are comparable.
Title-and-abstract search is the natural first move. The abstract usually names the population, the design, and the main outcome, and it is short enough that a keyword match is meaningful. Full-text search is the natural second move, because administration details, subgroup definitions, and protocol deviations often live in the methods section and never appear in the abstract.
Cochrane's guidance frames this the same way: plan searches from your eligibility criteria, use multiple sources, combine free-text terms with subject headings, document the process, deduplicate records, screen in stages, link multiple reports of one study, and rerun searches before publication. That is a layered process, not a single query.
Discoverability: where each layer finds records
Title-and-abstract search has high precision per match because the indexed text is short and deliberately topical. If a paper's abstract says "randomized controlled trial" and names your population, a match is likely to be relevant. The cost is recall: a study that reports your outcome as a secondary finding may never mention it in the abstract.
Full-text search inverts this. It reaches methods, supplementary descriptions, and secondary outcomes, so it surfaces studies that title-and-abstract search misses. The cost is that a full-text match can be triggered by a single passing mention in a discussion section or a reference list.
Database documentation reflects the difference in control. PubMed supports field tags, phrase searching, filters, Advanced Search, saved searches, Similar Articles, citation lookup, and links to full text when available, and its search details reveal how terms were translated and combined. That transparency lets you target the title and abstract fields specifically when you want precision, and broaden when you want recall. Google Scholar documents searching by author and title, date sorting and date limits, Cited by and Related articles, citation export, library access links, email alerts, and ways to locate alternative versions of a work — useful for citation chasing, less useful for field-level control.
Noise: what each layer drags in
The noise profile of title-and-abstract search is mostly false negatives. You get clean results and miss studies. That is dangerous in a review because the omission is invisible: nothing in your result list tells you what did not match.
The noise profile of full-text search is mostly false positives. A term that appears once in a limitations paragraph will match. In a large full-text result set, you will spend screening time on papers that mention your concept without studying it.
Cochrane's staged screening guidance is the practical response: deduplicate records, then screen in stages rather than treating the first result list as final. Staging lets you absorb full-text noise without letting it dominate your reading time.
Terminology: free text, subject headings, and translation
Terminology is where the two layers diverge most sharply. In title-and-abstract search, you are matching against author-chosen words plus indexer-assigned subject headings. Cochrane recommends combining free-text terms with subject headings precisely because authors and indexers use different vocabularies for the same concept.
In full-text search, you are matching against everything the authors wrote, including their own terminology for methods and instruments. That is an advantage when a method has several names, and a disadvantage when a common word appears in ordinary prose.
PubMed's search details are valuable here because they show how your terms were translated and combined. When a query returns unexpectedly few results, the translation view tells you whether a phrase was split or a term was mapped. That check belongs in your method trail, not just your troubleshooting.
Hidden methods details: the case for reading deeper
For a manuscript's methods section, the abstract is often insufficient. Administration details, blinding procedures, and analysis decisions frequently appear only in the full text. This is the strongest argument for a full-text layer in any review that compares interventions or instruments across studies.
The trade-off is that full-text retrieval gives you candidate papers, not extracted details. You still have to read the methods section and record what you find. A reproducible approach records both the query that surfaced the paper and the location in the paper where the detail was found.
Auditability: preserving a method trail
A retrieval strategy is only as good as its record. Cochrane's guidance to document the search process and rerun searches before publication sets the standard: your method section should let a reader reconstruct what you did.
A workable trail includes the sources searched, the exact queries, the field restrictions applied, the date of each search, the number of records before and after deduplication, and the screening decisions at each stage. When you use a search interface that exposes query translation, capture that view alongside the query. When you use citation chasing, record the seed paper and the direction of the chase.
A staged retrieval strategy
A staged strategy moves from precision to recall and records each step.
- Define eligibility first. Write the criteria before you search, following Cochrane's planning guidance. This determines which terms matter and which fields to target.
- Run a title-and-abstract pass. Use field tags and subject headings together. Capture the query translation. This pass gives you a clean core set.
- Run a full-text pass for methods-sensitive questions. Target the concepts that abstracts omit. Expect more noise and plan to screen in stages.
- Chase citations from the core set. Use Cited by and Related articles to find work that terminology missed.
- Deduplicate and screen in stages. Link multiple reports of the same study so one study does not count twice.
- Rerun before submission. Repeat the searches close to publication and record the update.
For the search step itself, WisPaper's scholarly search interface is where you run paper-finding queries, and the Scholar Search entry page explains the paper-finding entry point for readers new to the tool.
Where each approach fails
Title-and-abstract search fails when the concept you need is a methods detail, a secondary outcome, or a term the authors used only in the body. It also fails silently: you cannot see the studies you missed.
Full-text search fails when a term is common in ordinary prose, when the full text is unavailable, and when a match reflects a passing mention rather than a studied variable. It also produces result sets large enough that screening discipline becomes the binding constraint.
Citation chasing fails when the seed paper is atypical or when the field is too new for a citation network to have formed. Database field search fails when the record's indexing is incomplete or when the query translation does something you did not intend.
None of these failures is solved by switching tools. They are solved by layering retrieval and recording what each layer contributed.
Decision table
| Criterion | Title-and-abstract search | Full-text search |
|---|---|---|
| Best for | Building a precise core set; topical screening | Finding methods details, secondary outcomes, alternate terminology |
| Discoverability | High precision, lower recall | Higher recall, lower precision |
| Noise | Mostly missed studies | Mostly passing mentions |
| Terminology control | Free text plus subject headings; field tags | Everything the authors wrote |
| Hidden methods details | Often absent | Often present |
| Auditability | Strong when query translation is captured | Strong when screening stages are recorded |
| Typical failure | Silent omission | Screening overload |
A combined workflow for a manuscript or review
Start with eligibility criteria and a title-and-abstract pass to build a core set. Record the queries, the field restrictions, and the query translation. Then run a full-text pass aimed only at the concepts your core set cannot answer — usually methods and instrument details. Deduplicate, screen in stages, and link multiple reports of the same study.
As the set stabilizes, move the papers you intend to cite into an organized library so the retrieval trail and the reading trail stay connected. My Library is where you save or upload papers and organize them. When you need to interrogate the collected papers rather than search the open literature, Library QA lets you ask questions based on papers uploaded to My Library or added from search results.
For a larger synthesis — drafting the literature review around the retrieved set — Scholar Agent supports longer research tasks in its literature review, inspiration, and reproduction use cases. If the manuscript is a team effort with a shared evidence base, Research Projects is where you create and work within a project area.
Before submission, rerun the searches and record the update date. If your reference list was assembled from multiple passes, screen the BibTeX against real academic databases with TrueCite to flag hallucinated references.
FAQs
Keep Reading
Google Scholar Alerts vs. PubMed Saved Searches for Staying Current
Staying current on a clinical or biomedical question is a recurring maintenance task, not a one-time search. Two familiar options sit at opposite ends of the control spectrum: Google Scholar alerts, which watch a broad s
Google Scholar vs. Crossref for Checking a Suspicious Citation
A suspicious citation usually arrives in one of two forms: a reference in a manuscript you are reviewing that does not quite look right, or a line in your own draft that you cannot fully place. The fastest way to settle
Google Scholar vs. PubMed: Which Search Should You Run First?
For most focused biomedical evidence questions, run PubMed first. Its controlled vocabulary, field tags, filters, and transparent search translation give you a reproducible, auditable strategy that Google Scholar cannot