
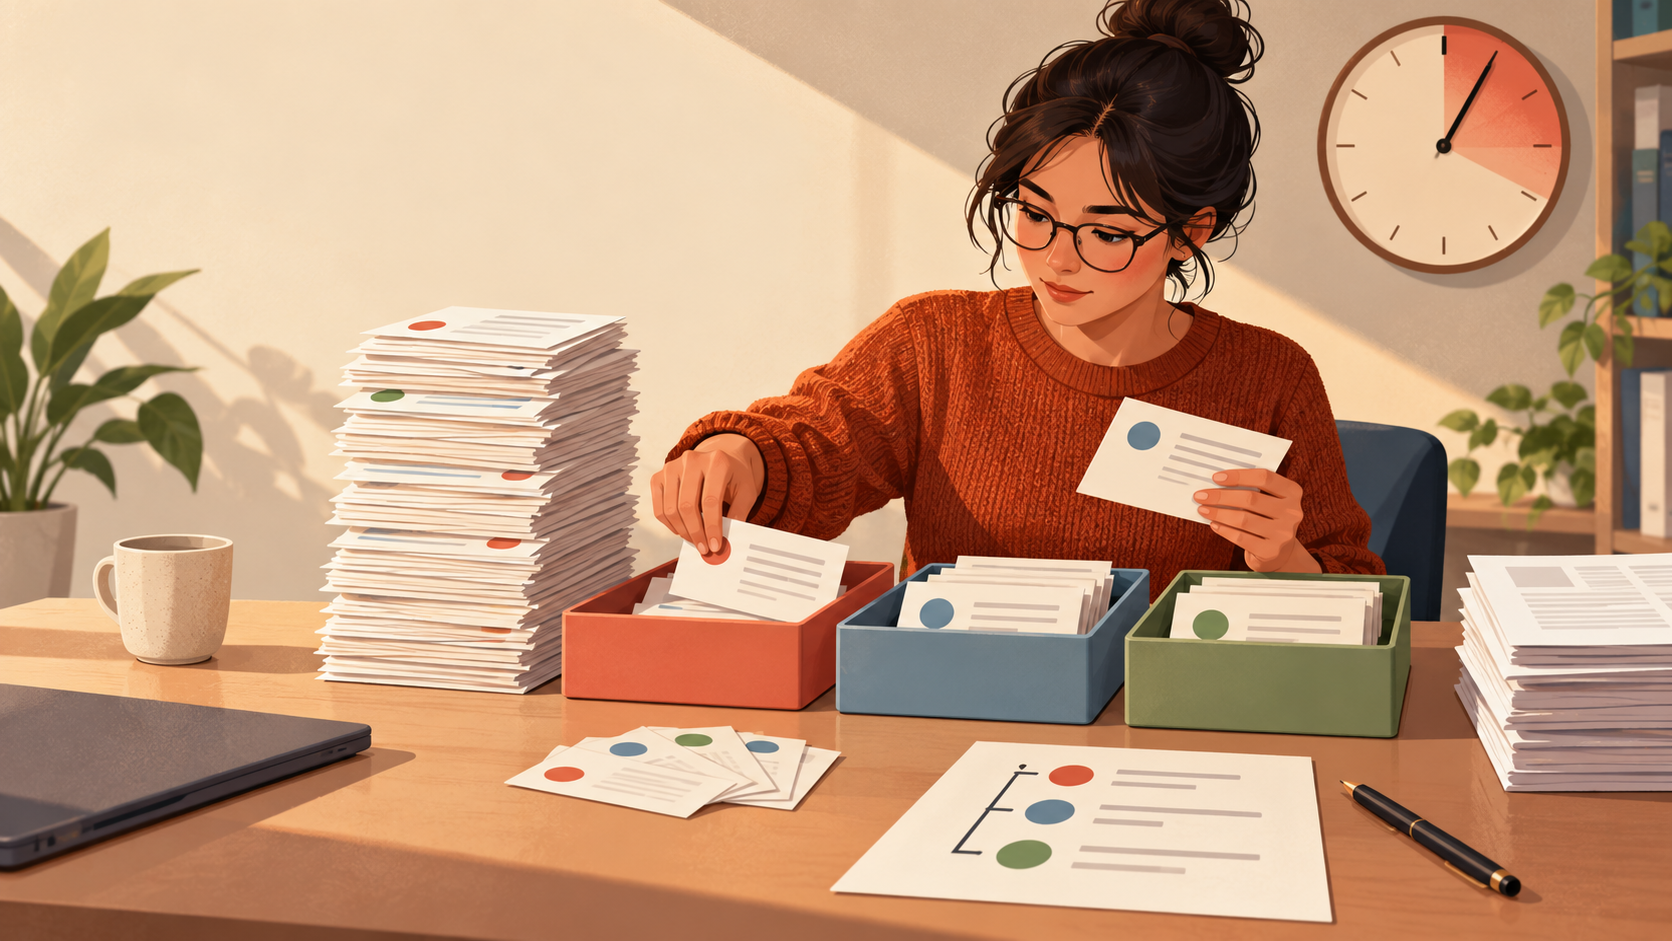
A hundred abstracts and a fixed deadline is a screening problem, not a reading problem. The fastest reliable way through it is to write your inclusion rules first, test them on a small calibration sample, then sort every remaining record into include, maybe, or exclude while recording a reason for each decision. Full text is reserved for the uncertain records. This sequence keeps your selection defensible and your time bounded, which matters whether the output is a course paper, a thesis chapter, or a first manuscript.
Cochrane's guidance on searching and selecting studies frames the work in the same order: plan searches from eligibility criteria, screen in stages, and document the process. PRISMA 2020 supplies reporting templates for search, selection, and synthesis. Both point to the same practical rule: decide what counts before you start deciding which papers count.
Step 1: Turn your question into written inclusion rules
Before opening a single record, write the rules that a paper must satisfy to enter your review. Base them on your research question, not on the papers you happen to have found. A workable rule set has four parts:
- Population or object of study. What must the paper actually study?
- Intervention, exposure, or method. What treatment, technique, or approach must be present?
- Outcome or contribution. What must the paper report or deliver?
- Boundaries. Date range, language, publication type, and study design, each stated explicitly.
Write each rule as a test you can apply to an abstract alone. "Uses a longitudinal design" is testable from an abstract; "is methodologically strong" is not. If a rule cannot be applied without the full text, mark it as a full-text criterion and keep it out of the abstract pass.
This step also protects you later. NIH guidance on scientific rigor treats careful assessment of prior knowledge, strengths, weaknesses, and knowledge gaps as core research practice. Written rules are how you show that assessment was systematic rather than opportunistic.
Step 2: Run a calibration sample before touching the full set
Take a small sample, roughly ten to fifteen records, and apply your rules to them. The purpose is to find rules that fail in practice, not to make progress on the hundred.
During calibration, watch for three failure modes:
- Rules that split records you would treat the same way. If two similar papers land on opposite sides, the rule is too sharp or too vague.
- Rules that almost nothing passes. A rule that excludes nearly everything usually describes your ideal paper rather than your eligible paper.
- Rules that require information abstracts never contain. Move these to the full-text stage.
Revise the rules once, then re-apply them to the same calibration sample. When your decisions on that sample are stable, you are ready for the full pass. Record the final rule set with a date so you can describe it in your methods section.
Step 3: Use three decisions, not two
A binary include/exclude choice forces you to guess on borderline records, and guesses are what make screening hard to defend. Use three categories:
- Include. The abstract clearly satisfies every abstract-level rule.
- Maybe. The abstract is ambiguous on at least one rule, or the rule can only be settled with the full text.
- Exclude. The abstract clearly fails at least one rule.
Every record gets exactly one decision. The maybe pile is not a failure of the method; it is the mechanism that keeps uncertain records out of both premature inclusion and premature exclusion. It also tells you precisely which records deserve your limited full-text access.
Step 4: Capture a reason for every decision
A decision without a reason cannot be audited, revised, or reported. For each record, note the rule that drove the decision in a few words: wrong population, no relevant outcome, outside date range, method unclear from abstract.
Keep the reason tied to a rule from Step 1. This makes your screening log convertible into the selection narrative that PRISMA 2020 expects, and it makes supervisor feedback actionable. When someone asks why a paper was dropped, you can point to the rule rather than reconstruct your thinking from memory.
A simple screening log with one row per record is enough:
| Field | What to record |
|---|---|
| Record ID | A stable identifier for the paper |
| Decision | Include, Maybe, or Exclude |
| Rule triggered | Which inclusion rule drove the decision |
| Reason | A short phrase, not a sentence |
| Full text needed | Yes or No |
| Notes | Anything a reviewer would need to re-check |
Step 5: Work the hundred in one pass
With rules fixed and the log ready, move through the remaining records in a single pass. Read each abstract against the rules and assign a decision immediately. Do not re-read, do not open full texts, and do not start drafting your literature review mid-pass.
If your records came from several searches, deduplicate before screening. Cochrane's guidance treats deduplication as a distinct step before staged screening, and duplicates inflate your counts and waste decisions.
If you still need to build the pool, a scholarly search interface lets you run structured queries and collect candidate records in one place. WisPaper's academic paper search is built for finding papers through a scholarly search interface, which is the step this pass depends on. Readers who want a public entry point for finding academic papers can start from WisPaper Scholar Search.
Step 6: Reserve full text for the maybe pile
Your full-text budget should go to uncertain records, not to confirming decisions you have already made. Work the maybe pile in order of how much each record could change your conclusions: records that would fill a gap in your evidence first, records that would duplicate existing coverage last.
For each maybe record, check only the specific rule that was ambiguous. If the full text resolves it, move the record to include or exclude and update the reason. If it does not, keep it as maybe and note what remains unresolved.
As you save papers you intend to keep, organize them so the include pile stays separate from the maybe pile. WisPaper's My Library is where you save or upload papers and organize them, which keeps your included set distinct from records still under review.
Worked example: a course paper due in nine days
Suppose you have a course paper due in nine days, a rubric that rewards a clearly justified selection of sources, and limited full-text access through your library.
Day 1. Write four inclusion rules from your research question: the paper must study your population, use your method family, report your outcome of interest, and fall within your stated date range. Mark "reports effect sizes" as a full-text criterion.
Day 2. Calibrate on twelve records. You find that your method rule excludes papers that use a closely related approach your rubric would accept. You broaden the rule once and re-apply it to the same twelve records. Decisions stabilize.
Days 3–5. Screen the remaining records in one pass. Of the hundred, sixty clearly fail a rule, twenty-five clearly pass, and fifteen land in maybe. Each row in the log carries a rule and a short reason.
Days 6–7. Spend your full-text access on the fifteen maybe records. Ten resolve to include or exclude. Five remain uncertain because the abstract and available full text do not settle the method question; you record what is unresolved.
Day 8. Write the selection paragraph from the log: how many records you screened, how many you included, and which rules drove the exclusions. PRISMA 2020's flow-diagram templates give you a structure for reporting these counts transparently.
Day 9. Submit with the screening log attached as an appendix, or summarized in a table if the rubric asks for it.
Diagnostic checkpoints during the pass
Check your process at three points rather than waiting until the end.
- After calibration. Are your decisions on the sample stable? If not, revise the rules before continuing.
- At the halfway mark. Is the maybe pile growing faster than you can resolve it? If so, one of your rules is probably too vague for abstract-level screening. Tighten it and note the change.
- Before the full-text stage. Is every maybe record tied to a specific unresolved rule? If a record is in maybe without a named rule, decide it now.
Stop and escalation rules
Set these before you start so a deadline does not force an improvised decision.
- Stop revising rules once calibration decisions are stable. Further revision after the full pass begins undermines consistency.
- Escalate a rule, not a paper, when you cannot apply it consistently. Take the rule to your supervisor or rubric and get a written interpretation.
- Escalate when the maybe pile exceeds your full-text capacity. Ask which uncertain records matter most for the argument, and document the priority order.
- Stop screening and fix the pool if duplicates or obviously irrelevant records dominate the set. The problem is upstream in the search, not in your decisions.
- Do not convert unresolved maybes into includes to hit a count. Report them as unresolved.
Reusable checklist
- Inclusion rules written and dated before screening
- Each rule testable from an abstract, or marked as full-text only
- Calibration sample of ten to fifteen records completed
- Rules revised once and re-applied to the calibration sample
- Records deduplicated before the full pass
- Every record assigned include, maybe, or exclude
- Every decision tied to a rule and a short reason
- Full text reserved for maybe records only
- Unresolved maybes recorded with the specific open question
- Selection counts ready for the methods section
When the task is larger than one pass
Some projects outgrow a single screening session: a thesis chapter with a broad question, or a first manuscript that needs a literature review alongside the selection work. At that point the triage sequence becomes one stage in a longer workflow. WisPaper's Scholar Agent area is built for longer research tasks that fit literature review, inspiration, or reproduction use cases, which is where a screening pass feeds into drafting. If you need to ask questions grounded in the papers you have already saved, Library QA supports asking questions based on papers uploaded to My Library or added from search results.
Cochrane also recommends rerunning searches before publication. If your deadline allows it, a final search before submission catches records published during your writing period and lets you report the update.
Making the submission decision
At the end of the sequence, you have three artifacts: a dated rule set, a screening log with a reason per record, and a count of includes, excludes, and unresolved maybes. The submission decision follows from those artifacts rather than from how much you have read.
Submit when the rules are documented, every record has a decision and a reason, and the unresolved maybes are reported as unresolved. If the rubric requires a flow diagram, build it from your counts using the PRISMA 2020 templates. If the rubric rewards justification, attach the log. If unresolved maybes would change your main claim, raise that with your supervisor before the deadline rather than after.
FAQs
Keep Reading
How to Turn a PICO Question into a Search Strategy
A PICO question is a clinical question broken into Population, Intervention, Comparison, and Outcome. A search strategy is the translation of those four elements into terms a database can actually match. The work between
How to Turn a Pile of Papers into an Argument Map
A pile of papers becomes an argument map when each paper is assigned a job: which claim it supports, which claim it complicates, which objection it raises, and which gap it leaves open. The map is not a summary of everyt
How to Turn Reviewer Comments into a Targeted Evidence Search
A reviewer's comment is rarely a request for more words. It is usually a request for a specific piece of evidence that the current draft does not yet carry. The fastest way to satisfy it is to convert the comment into a