
Active Learning with Context: Revolutionizing Aerial Image Annotation
Active Learning to Assist Annotation of Aerial Images in Environmental Surveys
The paper introduces a novel Active Learning (AL) framework specifically designed for object detection in aerial environmental surveys. By utilizing a "query-by-group" strategy and a harmonic mean scoring function, the method assists human annotators in labeling full images rather than individual patches, achieving an average reduction of 14.3% in manual interaction costs.
TL;DR
Manually counting objects in vast aerial datasets is a nightmare for environmental scientists. This paper proposes an Active Learning framework that doesn't just ask "is this patch a human?", but instead identifies the most valuable entire image for a human to review. By incorporating "Extra-Knowledge" from human corrections, the system reduces manual labor by over 14% and significantly stabilizes the human-AI interaction loop.
The Context Gap in Modern Labelling
Most Active Learning (AL) research treats data as a collection of independent points. In Remote Sensing, this is a mistake. When an expert looks at a tiny cluster of pixels that might be a shellfish gatherer on a beach, they don't just look at the pixels—they look at the tide, the surrounding equipment, and the landscape.
The authors argue that querying single patches (the "What") is cognitively harder for annotators than reviewing a full image (the "Where" and "Context"). The problem is that images are huge and objects are sparse, creating a massive class imbalance that breaks standard AL algorithms.
Methodology: Query-by-Group and the Harmonic Score
The core innovation is the move from instance-level queries to group-level queries.
1. The Scoring Function
The system ranks images () using a harmonic mean () that balances two crucial factors:
- Certain Positives (): Exploiting what the model already knows.
- Uncertain Instances (): Exploring the "decision boundary" where the model is confused.
2. The Feedback Loop (Extra-Knowledge)
The paper introduces the UC+C+EK (Uncertain + Certain + Extra-Knowledge) strategy. Unlike standard methods that only retrain on what the AI thinks is important, this strategy listens to the human. When a human fixes a False Positive or adds a False Negative, those specific "hard cases" are force-fed back into the SVM classifier.
 Figure 1: The iterative workflow showing the interaction between the image selection block, the human oracle, and the retraining step.
Experiments: Human-Centric Metrics
The researchers tested their approach on real-world datasets of shellfish gatherers. Notably, they didn't just measure F-score; they measured Interaction Gain—the actual number of mouse clicks saved.
Key Findings:
- Robustness to Initialization: While simple strategies (UC) were highly dependent on having a good "seed" image, the UC+C+EK strategy was incredibly stable.
- Speed to Trust: In the "UC+C+EK" setup, the user only had to perform a total "reset" (ignoring AI suggestions because they were too poor) in the first 4 iterations. In other strategies, the AI stayed "useless" for up to 16 iterations.
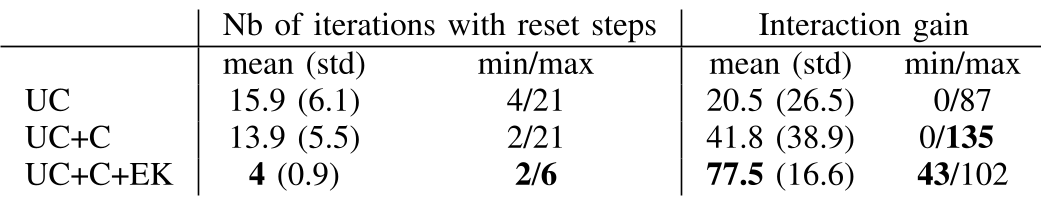 Table: Comparison of strategies. UC+C+EK provides the most consistent interaction gain (mean 77.5) and requires the fewest manual resets.
Critical Insight: Why F-Score Isn't Everything
Interestingly, the strategy that saved the most human time (UC+C+EK) actually had a lower F-score on the test set than the UC+C strategy.
Why? Because the EK strategy is aggressive at suppressing False Positives (improving Precision) at the cost of Recall. In an annotation tool, a human would much rather see fewer, highly accurate suggestions than be bombarded with dozens of "maybe" boxes that need to be deleted.
Conclusion & Future Outlook
This work demonstrates that for AI to be a true "assistant," it must optimize for the human experience, not just mathematical loss functions. By respecting the context of aerial imagery and valuing human corrections, the framework bridges the gap between raw data and usable environmental insights.
Limitations: The study uses HOG features and SVMs, which are classic but less powerful than Deep Learning. Future work should investigate how "Interaction Gain" scales when using self-supervised backbone models (like DINO or MAE) which are more common in modern remote sensing.