
Norms2Onto: Bridging the Gap in Financial Knowledge Modeling via Machine Learning
A New Automatic Ontology Construction Method Based on Machine Learning Techniques: Application on financial corpus
This paper introduces Norms2Onto, a semi-automatic ontology learning framework designed to model complex financial domains using IFRS and IAS standards. By combining NLP preprocessing with supervised machine learning, it achieves a high-fidelity representation of financial knowledge, significantly outperforming manual expert classification in scale and concept coverage.
TL;DR
The complexity of International Financial Reporting Standards (IFRS) often creates a "knowledge silo" difficult for even experts to navigate. This paper presents Norms2Onto, a pipeline that automates the transition from messy financial text to structured, interactive ontologies. Using Random Forest and NLP, it extracts 2,000 relevant concepts where human experts previously managed only 50, boasting a 0.93 precision rate.
Problem & Motivation: The Complexity of Global Finance
Since 2005, IFRS has been the global language of business. However, the sheer volume of these standards makes manual modeling—creating "ontologies" to shared meaning—a bottleneck.
The authors identify three critical challenges:
- Extraction: How to filter relevant financial terms from dense text?
- Enrichment: How to automatically assign precise definitions to these terms?
- Linkage: How to visualize the intricate web of relationships between diverse standards like IFRS 7 and IAS 32?
Previous works were either entirely manual or lacked a systematic approach to term extraction and relationship identification.
Methodology: The Norms2Onto Pipeline
The architecture is divided into three functional modules:
1. Preprocessing (The Cleaner)
Text is tokenized and tagged using Part-of-Speech (POS) and NP Chunking. This is vital because financial terms are often compound nouns (e.g., "Financial Instrument" vs "Financial").
2. Learning (The Brain)
The system identifies candidate concepts using TF-IDF. It then employs four supervised algorithms to predict the category and subcategory of each term:
- Linear SVC
- Logistic Regression
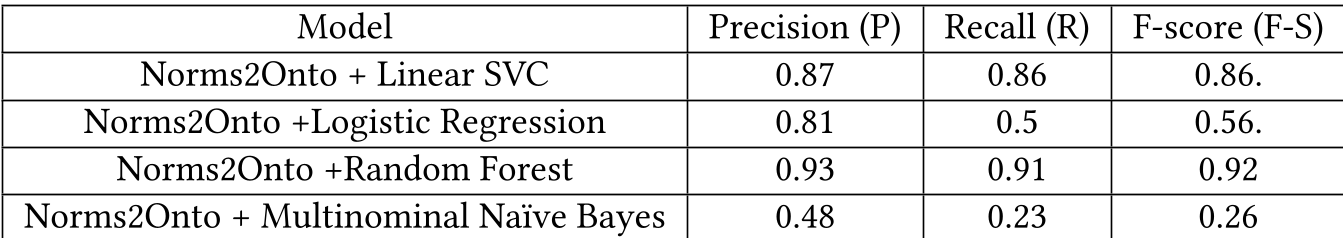
- Random Forest (The best performer)
- Multinomial Naive Bayes
3. Visualization (The Interface)
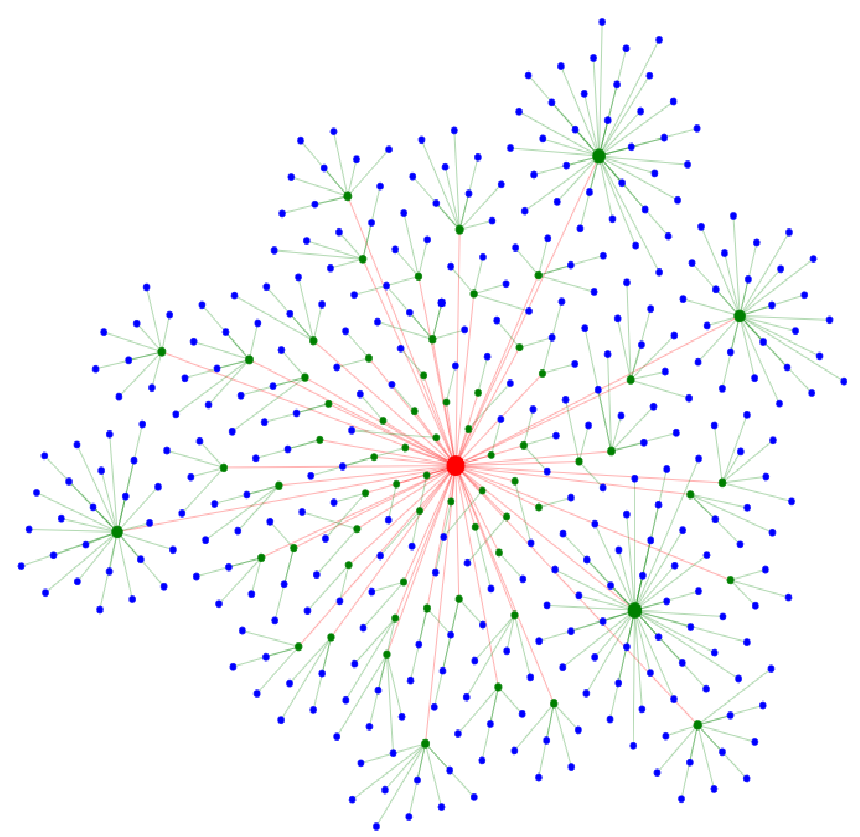
The output isn't just a list; it’s an interactive graph where concepts (blue), standards (red), and subcategories (green) are interconnected.
Experiments & Performance
The researchers tested the models on five core standards (IFRS 7, 13, IAS 1, 7, 32).
SOTA Comparison: ML vs. Human
The results were striking. When compared to a manual classification by an accounting expert, Norms2Onto demonstrated a massive leap in scale:
- Manual: 50 concepts.
- Norms2Onto: 2,000 concepts (with 1,900 validated as relevant by the IFRS Glossary).
Algorithmic Efficiency
The Random Forest algorithm proved to be the most robust for this domain-specific task, outperforming simpler models like Naive Bayes by a significant margin.
Critical Insight & Conclusion
The true value of Norms2Onto lies in its hybrid resource approach. By utilizing both the unstructured text of the norms and structured knowledge from external financial dictionaries (Investopedia and IFRS Glossary), the system mimics an expert's external lookup process.
Takeaway: While semi-automatic, this method proves that machine learning can drastically reduce the "knowledge engineering" tax in fintech.
Future Work: The authors suggest expanding the corpus to the entire IFRS/IAS catalog. However, a limitation to note is the current reliance on expert validation for the final "relevant concept" transition—future iterations might look toward LLMs (Large Language Models) to further automate this validation step.