
TERC: Revolutionizing Search Evaluation through the Power of the Crowd
Crowdsourcing for relevance evaluation
This paper introduces TERC (Technique for Evaluating Relevance by Crowdsourcing), a methodology for information retrieval (IR) evaluation using Amazon Mechanical Turk. It demonstrates how complex, expensive editorial assessments can be decomposed into micro-tasks performed by distributed online workers to achieve SOTA-level evaluation scalability.
TL;DR
Information Retrieval (IR) evaluation has long been trapped in a "cost-vs-scale" dilemma. This seminal work introduces TERC (Technique for Evaluating Relevance by Crowdsourcing), leveraging platforms like Amazon Mechanical Turk to perform massive-scale editorial assessments at a fraction of the cost and time of traditional methods.
The Bottleneck: Why Evaluation is the Hardest Part of Search
In the early days of IR, graduate students meticulously read every document in a corpus—a process that limited test collections to tiny datasets like Cranfield. Even with the advent of TREC and "pooling" methods, the industry remained reliant on professional analysts and high budgets.
The authors identify a critical gap:
- The Cost Barrier: Hiring professional editors for niche domains (e.g., local business search) is too expensive.
- The Signal Gap: User click behavior (implicit feedback) is scalable but often misleading—a lack of a click can mean a "perfect snippet" just as easily as a "useless result."
TERC: "Artificial Artificial Intelligence"
The core insight of TERC is to treat human judgment as a distributed micro-service. By breaking down a large evaluation set into thousands of independent Human Intelligence Tasks (HITs), researchers can tap into a global workforce of over 200,000 workers.
The Workflow
The TERC framework follows a structured pipeline:
- Task Decomposition: A complex relevance scale (0-3) is mapped to a simple UI.
- XML Specification: Defining the question structure to be digestible for non-experts.
- Execution: Distributing 2,500 pairs across the Turk network.
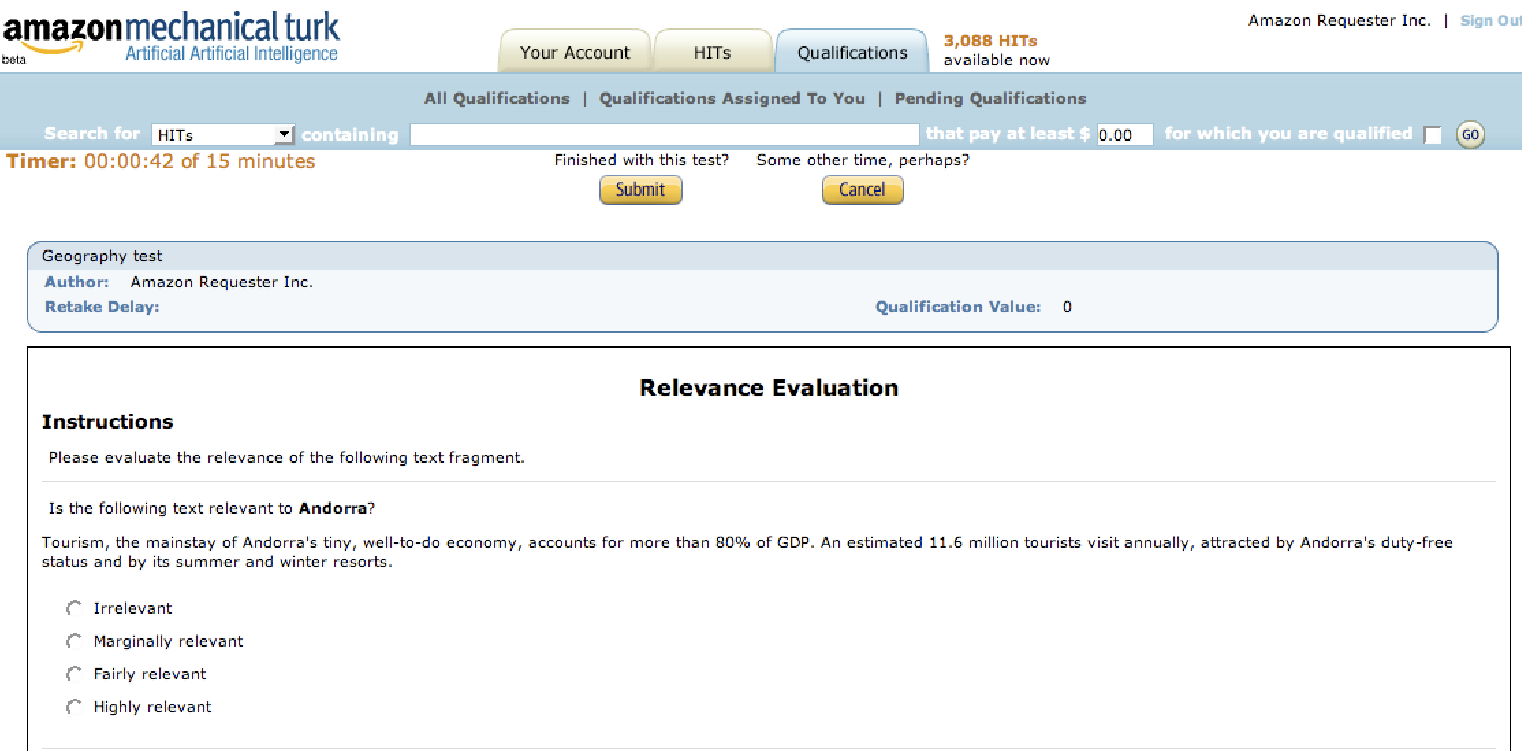 Figure 1: A sample HIT where a worker evaluates the relevance of text regarding Andorra.
Solving the "Trust" Problem: Quality Control
The most frequent critique of crowdsourcing is: How can we trust random strangers on the internet? The paper outlines a robust defense-in-depth strategy:
- Qualification Tests: Before workers can touch a task, they must pass a domain-specific test (e.g., geography questions for a world factbook search).
- Redundancy & Consensus: Instead of one expert, TERC uses multiple workers per pair. By using voting schemes or weighted sums, "noise" from lazy workers is filtered out.
- The "Pay-on-Accept" Loop: Because requesters only pay for approved HITs, there is a built-in economic incentive for workers to provide high-quality data.
Performance & Scalability
The results are staggering when compared to the weeks or months required for traditional TREC-style setups:
| Metric | Traditional (Editorial) | TERC (Crowdsourcing) |
|---|---|---|
| Throughput | Weeks/Months | 2-3 Days |
| Cost | High (Professional Salary) | ~$0.01 per judgment |
| Scalability | Linear to staff size | Elastic (up to millions of tasks) |
Note: In the original paper, the authors emphasize that for a mere $125, they obtained 2,500 high-quality judgments from 5 separate workers per query.
Critical Analysis: Is the Crowd Enough?
While TERC is a breakthrough in efficiency, the authors remain intellectually honest about its limits:
- Intent Gap: A worker paid $0.01 doesn't have the same "information need" as a real user. They are simulating a user, which may introduce a different type of bias.
- Cultural Context: Evaluating local search in Italy requires Italian cultural knowledge, which a global pool might struggle to replicate without extremely strict qualification filtering.
Summary & Future Outlook
The TERC approach moved IR evaluation from a "boutique" manual process to an "industrial" automated one. It proves that human intuition is a resource that can be scaled programmatically. For today’s AI researchers, this work laid the foundation for modern RLHF (Reinforcement Learning from Human Feedback) workflows and large-scale dataset labeling that powers LLMs today.