
Deciphering Economic Distress: Social Network Analysis of Czech Insolvency Data
Czech Insolvency Proceedings Data: Social Network Analysis
This paper presents a comprehensive study of the Czech Insolvency Register using Social Network Analysis (SNA) and data mining. By integrating OCR-extracted data with structured records, the authors construct a dynamic bipartite network to identify influential creditors, administrators, and judicial senates, while predicting future links through association rule mining.
TL;DR
Researchers from Charles University in Prague have pioneered a method to map the complex web of Czech insolvency proceedings. By extracting "trapped" data from scanned documents using machine learning and applying Social Network Analysis (SNA), they identified the most influential creditors and judicial actors, uncovering hidden patterns of debt co-occurrence that predict how financial failure spreads through an economy.
Background & Motivation: The Dark Data Problem
In the wake of the 2008 Global Financial Crisis, the Czech Republic saw a massive spike in insolvency cases—reaching over 160,000 filings. However, the official "Insolvency Register" had a significant flaw: prior to October 2011, the names of creditors were buried inside scanned PDFs rather than recorded in a searchable database.
To the authors, this wasn't just a technical hurdle; it was a Complex Adaptive Systems problem. They hypothesized that debtors, creditors, administrators, and senates form a dynamic social network where the "prestige" or "influence" of certain actors can signal systemic economic shifts.
Methodology: From Unstructured Text to Graph Topology
1. Document Recovery (The NLP Pipeline)
The authors used Tesseract OCR to digitize approximately 270,000 scanned applications of receivables. They treated this as a text classification task:
- Features: TF-IDF scores of n-grams (1 to 3).
- Models: Compared Naïve Bayes, SVM, Extreme Learning Machines (ELM), and Logistic Regression.
- Optimization: Logistic Regression proved superior, reaching 96.5% accuracy in identifying specific creditors.
2. The HITS Algorithm: Authorities and Hubs
To model the network, the authors treated the system as a directed graph where:
- Creditors = Authorities (nodes with many incoming edges representing debt).
- Administrators/Senates = Hubs (nodes with many outgoing links managing the proceedings).
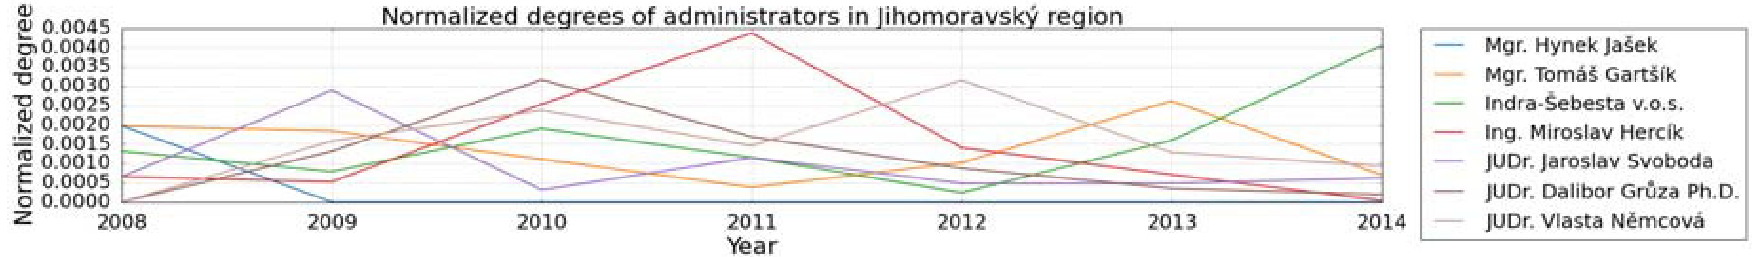 Fig 1. Evolution of prominence: Authority/Hub scores reveal how different actors' influence fluctuates over a 7-year period.
Experiments & Results: Mapping Influence
The study analyzed 98 network snapshots across 14 regions.
- Creditor Dynamics: The analysis showed a "changing of the guard." Traditional powers like General Health Insurance (VZP) saw their relative authority decline, while non-banking lenders like Provident Financial experienced a rapid rise in prominence after 2011.
- Link Prediction: Using FP-Growth, the authors discovered high-confidence association rules. For instance, legal entities in the Jihomoravsky region owing money to health insurance (VZP) were almost guaranteed to owe money to the Social Security Administration as well (Lift > 40).
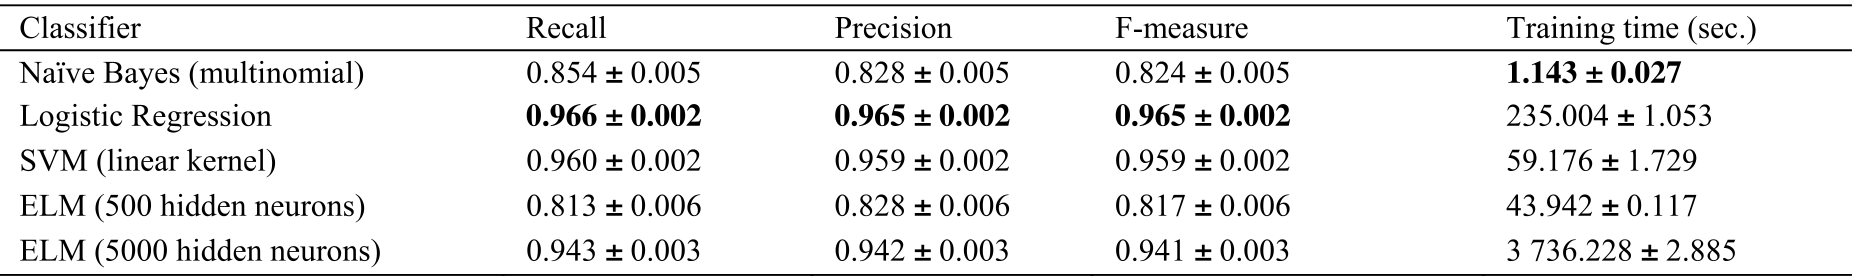 Table 1. Performance comparison of different classifiers in recovering creditor data.
Critical Insight: The "Hub" Dilution Effect
One fascinating observation in the paper is the evolution of hub scores. In the early years (2008-2010), a small number of judicial senates and administrators handled nearly all cases. As the total volume of insolvencies exploded, however, the Hub Scores became more evenly distributed. This "dilution" suggests a system under stress, forced to decentralize to prevent a complete bottleneck in the legal process.
Conclusion & Future Outlook
This research moves beyond simple statistics to show that insolvency is a structural phenomenon. By viewing financial failure through the lens of Social Network Analysis, we can identify "key players" in economic contagion.
Limitations: The study relies on a bag-of-words approach for OCR data, which may struggle with very low-quality scans. Future work might leverage Deep Learning (e.g., Graph Convolutional Networks) to predict company bankruptcy before it enters the register based on its proximity to high-risk hubs.