
CSP-cNN: Breaking the Accuracy Barrier in Constraint Satisfaction via Deep Learning
Towards Effective Deep Learning for Constraint Satisfaction Problems
The paper introduces CSP-cNN, a deep learning framework designed to predict the satisfiability of Constraint Satisfaction Problems (CSPs). By representing binary CSPs as matrices and employing a Convolutional Neural Network (CNN), the authors achieve a remarkable >99.99% prediction accuracy on random Boolean binary CSPs.
TL;DR
Predicting whether a Constraint Satisfaction Problem (CSP) has a solution is typically a hard combinatorial task. This paper presents CSP-cNN, the first deep learning approach to achieve over 99.99% accuracy in predicting CSP satisfiability. By converting CSPs into image-like matrices and solving the "data hunger" problem with a novel synthetic generation model (GMAM), the authors prove that neural networks can "see" the underlying structure of NP-hard problems.
Problem & Motivation: The Feature Bottleneck
For decades, applying ML to CSPs meant manual labor. Researchers had to hand-pick features (like constraint density or tightness) to train Support Vector Machines or Decision Trees. These methods were limited:
- Inaccuracy: They rarely crossed the 99% accuracy threshold.
- Lack of Generality: Features optimized for one type of problem failed on others.
- Data Scarcity: Because solving CSPs is NP-hard, getting "ground truth" labels for thousands of examples to train a Deep Neural Network was considered too expensive.
The authors' insight was simple yet bold: Treat the CSP as an image. If a CNN can find a cat in a mess of pixels, it should be able to find the patterns of incompatibility in a CSP matrix.
Methodology - The Core
1. The CSP Matrix Representation
The authors map a binary CSP to a 2D matrix. Each row and column represents a variable-value pair .
- An entry is 0 if the pair is disallowed (incompatible).
- An entry is 1 if the pair is allowed.
This turns the logical constraints into "visual" patterns that a CNN can process using local filters.
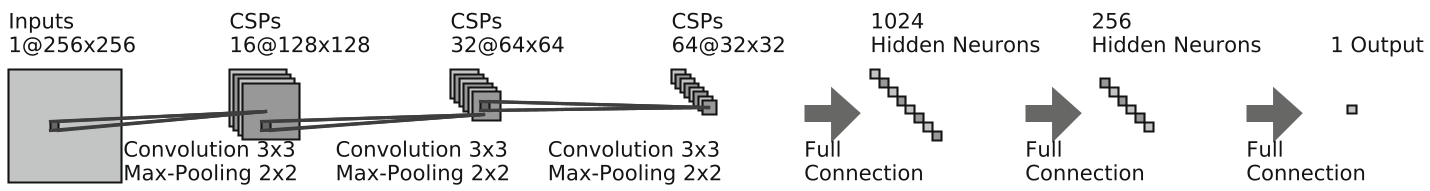 Figure 1: The CSP-cNN Architecture featuring 4 convolutional layers followed by MaxPool and fully connected layers.
2. Overcoming Data Scarcity: GMAM
To train a deep network, you need millions of labels. The authors used the Generalized Model A-based method (GMAM). Based on the asymptotic behavior of random CSPs, they can generate instances that are guaranteed to be unsatisifiable as the number of variables grows, or forced to be satisfiable by injecting a solution. This allows the creation of massive datasets without actually running a slow CSP solver.
Experiments & Results
The researchers tested CSP-cNN against several baselines, including plain fully connected networks (NN-1, NN-2) and previous attempts to convert CSP text files to images.
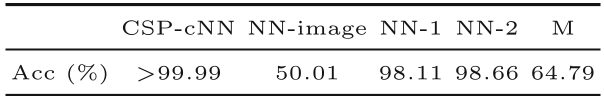 Table 1: CSP-cNN significantly outperforms previous image-based methods and standard shallow NNs.
Key Findings:
- Superiority of Matrix View: Using the CSP matrix yielded >99.99% accuracy, while the "image-from-ASCII" approach (NN-image) was no better than a coin flip (50%).
- Domain Adaptation Works: Even when the model was tested on a completely different distribution (Modified Model E), using a mix of synthetic GMAM data and local data reached 100.00% accuracy.
Critical Analysis & Conclusion
Takeaway
The success of CSP-cNN suggests that high-dimensional patterns in constraints are not as "random" as they seem. Deep learning can extract an inductive bias from synthetic CSP models that generalizes to unknown distributions.
Limitations & Future Work
- Scale: The experiments were limited to 128 variables due to matrix size constraints (Memory grows at ).
- Scope: While a "proof of concept" on Boolean CSPs (which can be in P), the real test lies in applying this to Non-Boolean, Non-Binary, and Global Constraints.
- Next Steps: Future research will likely move toward Graph Neural Networks (GNNs) to handle variable arity and larger instances more efficiently than a fixed-size matrix.
This work paves the way for "Neural-Guided Solvers," where a CNN predicts the likelihood of success for different variable assignments, drastically reducing the search space in backtracking algorithms.