
Beyond Binary Sentiments: Decoding Emotion Intensity via Fuzzy-Rough Sets
Fuzzy-Rough Set Based Multi-labeled Emotion Intensity Analysis for Sentence, Paragraph and Document
This paper introduces a novel fuzzy-rough set-based approach for multi-labeled emotion intensity analysis in social media text. Unlike traditional methods, it simultaneously detects multiple coexisting emotions and quantifies their specific intensities across sentence, paragraph, and document levels.
TL;DR
In social media, a single sentence rarely carries just one emotion. A post can be 80% "Joy" but also 40% "Expectation." This paper moves beyond traditional single-label classification by proposing an improved Fuzzy-Rough Set algorithm. It doesn't just identify which emotions are present; it calculates how strong they are across sentences, paragraphs, and entire documents, outperforming traditional Naïve Bayes and Fuzzy Union baselines.
Background: The Complexity of Human Feeling
Most sentiment analysis tools are "colorblind"—they see text as purely positive, negative, or neutral. Even fine-grained models usually force a choice between "Joy" or "Anger." However, real-world text is multi-labeled. The authors argue that detecting these coexisting emotions and their varying intensities is critical for truly understanding social media discourse.
The Core Challenge: Why is Intensity Hard?
Prior works struggle because:
- Binary Bias: Most multi-label learning treats labels as a 0 or 1 presence/absence check.
- Non-Additivity: Human emotion isn't simple math. Three weak "joyful" words don't necessarily equal one "ecstatic" word.
- Ambiguity: Sentiment words often overlap across different emotional categories depending on context.
Methodology: Applying Fuzzy-Rough Logic
The authors utilize Fuzzy-Rough Set theory because it is built to handle uncertainty.
1. Modeling with Approximations
The method defines a fuzzy approximation space where is the set of 8 basic emotions and is the set of sentiment words. The core of the algorithm lies in calculating the Upper and Lower Approximations:
- Upper Approximation: Captures the maximum possible intensity an emotion could have given the words.
- Lower Approximation: Provides a more conservative, "certain" estimate of the intensity.
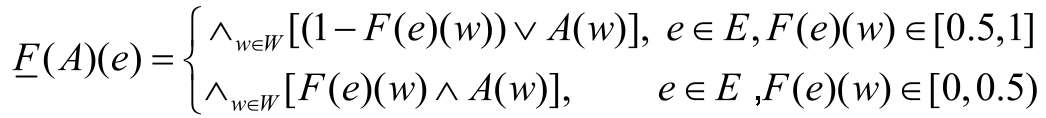
2. The Decision Logic
The authors propose that the emotion of a sentence is governed by "key words" that dominate the sentiment. Unlike a Naïve Bayes approach (which assumes independence) or a Fuzzy Union (which only looks at the maximum), this method calculates a choice value by summing the upper and lower approximations and then using Linear Regression to map the result back to a human-readable 0-to-1 scale.
Experimental Evidence: SOTA Performance
The authors tested their approach on a well-known Chinese blog corpus.
| Metric | Document Level | Paragraph Level | Sentence Level |
|---|---|---|---|
| Subset Accuracy | 99.76% | 98.61% | 96.38% |
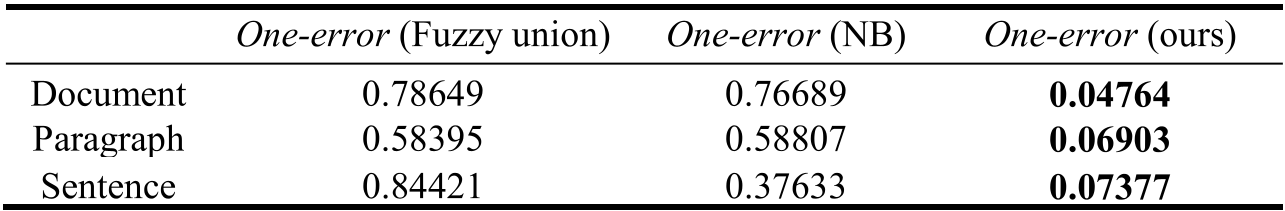
When compared to Fuzzy Union and Naïve Bayes (NB), the Fuzzy-Rough approach showed a dramatic reduction in One-error (the frequency with which the top-predicted emotion is wrong):
Case Study: Key-Word Dominance
Consider the sentence: "I visited Shenyang, the bustle of the middle street, the tranquility of the Expo, and the wonder of the strange slope made me fall in love with this city."
- Words like "bustle" and "tranquility" hint at Joy (0.3 - 0.5).
- The word "Love" hits Love (0.9). Traditional sums might incorrectly prioritize Joy due to word count, but the Fuzzy-Rough model correctly identifies Love as the dominant emotion, matching human logic.
Critical Analysis & Conclusion
Takeaway
The synergy between Fuzzy sets (handling intensity) and Rough sets (handling uncertainty/granularity) provides a robust framework for multi-label emotion analysis. It effectively captures the "linguistic dominance" of certain words without ignoring the surrounding context.
Limitations
- Linguistic Scope: The current model heavily relies on a predefined sentiment lexicon. It may struggle with irony, sarcasm, or evolving internet slang.
- Contextual Adverbs: As noted by the authors, the model does not yet explicitly account for intensifiers (e.g., "very," "extremely") or negations ("not happy").
Future Work
The next frontier for this research involves integrating this fuzzy logic into Deep Learning architectures. Imagine a Transformer model where the attention mechanism is weighted by fuzzy-rough uncertainty values—this could lead to even more nuanced AI emotional intelligence.