
IVM: Accelerating Targeted Viral Marketing via Importance Sampling
Importance Sample-based Approximation Algorithm for Cost-aware Targeted Viral Marketing.
This paper introduces Importance Sample-based Viral Marketing (IVM), a novel approximation algorithm for the Cost-aware Targeted Viral Marketing (CTVM) problem. By leveraging "Importance Benefit Samples" (IBS), it achieves a approximation ratio while significantly reducing sample complexity and execution time compared to previous state-of-the-art methods like BCT.
TL;DR
Viral marketing aims to find the most influential "seed" users to maximize a brand's reach. However, real-world marketing involves costs for seeds and specific benefits for different targets. The Importance Sample-based Viral Marketing (IVM) algorithm revolutionizes this by focusing only on "importance samples," achieving up to 153x speed-up and 112x sample reduction over the previous state-of-the-art (BCT), all while maintaining rigorous theoretical guarantees.
Problem & Motivation: The Heavy Cost of Accuracy
The classic Influence Maximization (IM) problem is often too simplistic. In reality, influencers charge different fees (Costs), and reaching a CEO is more valuable than reaching a casual observer (Benefits). This is the Cost-aware Targeted Viral Marketing (CTVM) problem.
Existing solutions like BCT rely on a technique called Reverse Influence Sketching (RIS). RIS works by sampling the nodes that could potentially influence a target. However, many of these samples are "singular"—they only contain the target node itself—providing little information about the network's propagation structure. This inefficiency forces algorithms to generate millions of samples, leading to massive memory bottlenecks and slow runtimes on large-scale graphs.
Methodology: Work Smarter, Not Harder
The core insight of the authors is twofold: Filtering Inefficiency and Statistical Early Exit.
1. Importance Benefit Sampling (IBS)
Instead of traditional benefit sampling, the authors introduce Importance Benefit Sampling (IBS). They mathematically prove that singular benefit samples (which contain only one node) contribute insignificantly to the estimation. By redesigning the sampling probability space to focus on samples containing at least two nodes, the algorithm captures the "meat" of the influence spread much faster.
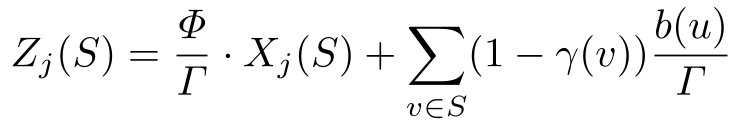 The algorithm uses these importance samples to estimate the benefit function with much lower variance.
2. Martingale-based Stopping Criteria
IVM doesn't just guess when to stop. It uses Martingale Analysis to calculate dynamic lower () and upper () bounds. If the current candidate solution satisfies the gap between these bounds, the algorithm terminates early. This ensures that the algorithm uses the absolute minimum number of samples required for a guarantee.
Experiments: Breaking the Speed Limit
The performance gains are most visible in the Amazon network (262k nodes, 1.2M edges).
Key Metrics:
- Efficiency: IVM is 153x faster than BCT on the Amazon dataset.
- Sample Economy: It requires only 1.25 million samples compared to BCT's 270 million samples for the same task.
- Memory: It reduces memory usage significantly, making it feasible to run on commodity hardware for billion-scale networks.
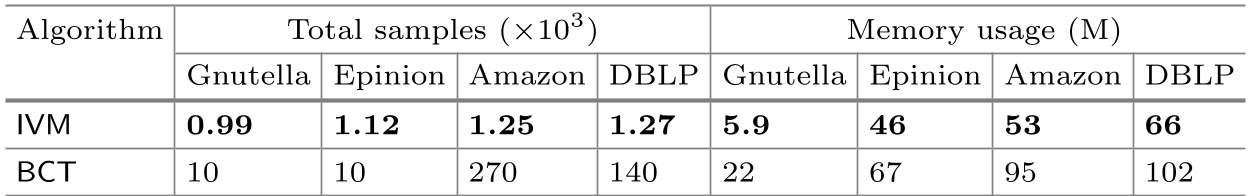 Table 4: IVM vs BCT - A clear victory in sample count and memory efficiency.
Critical Analysis & Conclusion
IVM proves that in the world of big data and social graphs, quality of samples matters more than quantity. By identifying that "singular" samples are essentially noise in the estimation of spread, the authors optimized the sampling process at its theoretical root.
Limitations & Future Work
While IVM is a massive leap for approximation algorithms, the authors acknowledge that exact approaches (like TIPTOP) exist. The next frontier is integrating the "Importance" concept into exact solvers to see if the "word-of-mouth" effect can be calculated perfectly in seconds rather than hours.
Takeaway: If you are dealing with information diffusion on large graphs, stop over-sampling. Focus on the importance of the paths, and let Martingales handle the confidence.