
Incentivizing Truth: Beyond Simple Agreement in Crowdsourcing
Incentives for truthful reporting in crowdsourcing
This paper introduces the Consensus Prediction Rule, a novel incentive mechanism for crowdsourcing that ensures strict Bayesian-Nash incentive compatibility for truthful reporting. The method improves upon traditional Peer Prediction by rewarding workers based on how well their reports predict the system's final consensus outcome rather than a single peer's report.
TL;DR
Crowdsourcing often struggles with a fundamental paradox: how do you pay people to be honest when you don't know the "right" answer yourself? This paper by Kamar and Horvitz from Microsoft Research introduces the Consensus Prediction Rule. Unlike traditional methods that pay you for agreeing with a random neighbor, this method pays you based on how well your report predicts the aggregate wisdom of the entire crowd, making it fairer and harder to game.
The Fragility of Peer Prediction
In digital labor markets like Amazon Mechanical Turk, the standard way to ensure quality is to hire "experts" to check work or use "gold standard" questions. However, these are expensive and often impossible for niche tasks.
The academic alternative has been Peer Prediction. The intuition is simple: if everyone is honest, their reports should be stochastically correlated. However, Peer Prediction has a "Fairness" problem. If you are a brilliant worker paired with a lazy or incompetent peer, you lose money despite being right. This creates a weak and noisy incentive signal.
Methodology: The Shift to Consensus
The authors propose a shift from peer-to-peer matching to System-to-User prediction.
1. Robust Answer and Report Models
The system maintains two probabilistic models:
- Answer Model (): The probability of the "True" answer given task features.
- Report Model (): The probability of a worker providing a specific report given the true answer.
2. The Consensus Prediction Rule
Instead of matching worker with worker , the system calculates:
Where:
- is the worker's forecast of what the rest of the group will conclude.
- is the actual consensus reached by all other workers.
By using the "Consensus" as the ground truth, the system filters out the noise of individual bad actors. The consensus of many is a much more stable signal than the report of one.
Mathematical Intuition
The payment calculation is a sophisticated two-step simulation. The system asks:
- "Given what Worker A just told us, what is the most likely consensus the rest of the crowd will reach?"
- "Now, let's look at what the rest of the crowd actually said."
If Worker A’s report correctly adjusted the system’s expectation of the final outcome, they receive a high score via a Proper Scoring Rule. This ensures that the only way to maximize your expected reward is to report your observation truthfully (Strict Bayesian-Nash Equilibrium).
Experiments and Insights
The paper emphasizes that this rule is particularly effective for "Consensus Tasks"—tasks where a single correct answer exists but is hidden. By coupling payment with the system’s internal planning policy (), the mechanism discourages strategic manipulation by both workers (who might try to guess the majority) and task owners (who might try to avoid payment).
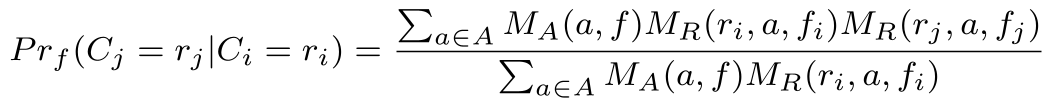 The image above illustrates the Bayesian update used to calculate the probability of a peer report—the foundation that Consensus Prediction improves upon.
Critical Analysis & Conclusion
Takeaway
The Consensus Prediction Rule provides a mathematically rigorous way to elicit truth in decentralized environments. It moves the needle from "Agreement" to "Informed Prediction."
Limitations
The primary hurdle for this method is the Common Knowledge assumption. The system assumes that the models (, ) are accurate and that workers understand these probabilities. In the real world, human workers rarely think in precise Bayesian terms, which might lead to sub-optimal behavior even if the math is sound.
Future Outlook
As we move toward AI-assisted labeling and "Human-in-the-loop" systems, these incentive structures will be vital. They provide a blueprint for how AI agents can audit human contributions (and vice versa) without needing a pre-defined answer key.