
CrossLexica: Scaling Linguistic Knowledge through Semantic Inference
Yet another application of inference in computational linguistics
The paper introduces a heuristic-based inference framework for expanding Collocation Databases (CDB) by leveraging semantic relations from WordNet-like thesauri. It proposes a formal logic-style rule to predict new word combinations, achieving up to 93-100% accuracy in specific linguistic categories within the CrossLexica system.
TL;DR
This classic work by Bolshakov and Gelbukh addresses the "data sparsity" problem in computational linguistics. Instead of relying solely on massive text corpora, the authors propose a logic-based system to infer new word collocations (like pay attention) using existing semantic relations (synonyms, hyperonyms). By treating language as a structured graph of meanings, they can "predict" valid phrases for rare words with high precision.
The "Completeness" Wall in Lexicography
Building a Collocation Database (CDB) is a Herculean task. To reach even 70% coverage of a natural language, a human editor would need to sift through gigabytes of text. Even then, rare words (the "infrequent clients" of language) often lack enough data points to establish their typical partners.
The authors' core Insight is simple but powerful: If we know that Coca-Cola is a refreshing drink, and we know that people pour, drink, and bottle refreshing drinks, we can safely infer that people also pour, drink, and bottle Coca-Cola—even if those specific pairs never appeared in our training corpus.
Methodology: The Logic of Language
The authors formalize this as a heuristic production rule:
Where:
- S is a Semantic similarity (e.g., Synonymy).
- D is a Dependency/Collocational link (e.g., Object-of).
1. The Inference Bridges
- Synonymy-based: If "coating" is a synonym of "layer," and we "cover with a layer," we can "cover with a coating."
- Hyperonymy-based: Properties of a "drink" (the parent) flow down to "Coca-Cola" (the child).
- Morphology-based: Collocations registered for the singular form "difficulty" can often be transferred to the plural "difficulties."
2. Safeguarding the Logic (Prohibitive Filters)
Not all logic is sound in language. To prevent "hallucinations" (e.g., inferring "hot poodle" from "hot dog"), the authors introduce negative constraints:
- Classifying Modifiers: You can't transfer "European" from "country" to "Argentina" just because they are both countries.
- Quantifiers: Adjectives like "numerous" only apply to plural forms; the system must block them when inferring singular collocations.
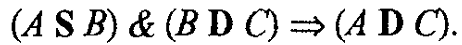 The core heuristic formula used to drive the CrossLexica expansion.
Experimental Performance
Testing the theory on the CrossLexica system (a database of 1.4 million links), the results were revealing:
| Collocation Type | Initial Accuracy | Post-Filter Accuracy |
|---|---|---|
| Verbal Complements | 100% | 100% |
| Noun Predicates | 93% | 93% |
| Modificatory (Adj+N) | 10% | 83% |
The massive jump in "Modificatory" accuracy highlights that language is not just about logic; it's about contextual constraints. Without filtering out "plural-only" or "idiomatic" words, the system fails. With them, it becomes a robust tool for database replenishment.
Note: The CrossLexica database balance shows that while modificatory collocations are the most numerous (615k), technical verb-object relations are the most predictable.
Critical Insight & Takeaway
This paper serves as a precursor to modern "Zero-shot" learning. It argues that we don't need to see every word combination in a corpus to know it is valid; we can move through the latent semantic space (the thesaurus) to fill in the gaps.
Future Outlook: While today's LLMs (like GPT-4) "know" these collocations implicitly through sheer scale, this structured approach remains vital for building verifiable, interpretable, and lightweight symbolic AI systems where data is scarce or high precision is required.
Conclusion
Bolshakov and Gelbukh prove that linguistic inference is a viable shortcut for the "bottleneck" of manual lexicography. By bridging WordNet-style hierarchies with collocation data, we can create richer, more flexible language models that understand the "sensible" nature of word combinations.