
Decoding the Ripple Effect: A Deep Dive into Influence Maximization in Social Networks
Influence Maximization Problem in Social Networks: An Overview
This paper provides a comprehensive survey of the Influence Maximization (IM) problem in social networks, categorizing diffusion models like Independent Cascade (IC) and Linear Threshold (LT) and systematically classifying IM algorithms into four main families: Greedy, Centrality-based, PageRank-based, and Community-based. It identifies key SOTA achievements in handling dynamic and distributed networks while addressing the NP-hard nature of finding a minimal seed set for maximal influence spread.
TL;DR
Influence Maximization (IM) is the strategic task of finding a small "seed set" of users who can trigger the largest possible cascade of information across a social network. This survey explores the evolution from basic epidemic models to sophisticated algorithms that handle millions of nodes in real-time. It moves beyond "who has the most followers" to "who can actually drive adoption."
The Core Challenge: Why is IM so Hard?
At its heart, IM is a discrete optimization problem. Given a graph and a budget , we want to find a set where that maximizes the expected spread .
The difficulty arises because:
- NP-Hardness: Calculating the exact optimal set is computationally impossible for large networks.
- Stochastic Nature: Information diffusion is probabilistic. We don't just need to know the topography; we need to simulate the "how" and "when" of user interaction.
Methodology: How Information Spreads
The paper categorizes the engine of IM—the Diffusion Models—into three primary archetypes:
1. Independent Cascade Model (ICM)
In this sender-centric model, an active node has one chance to activate its neighbor with a fixed probability . It’s binary and memoryless.
2. Linear Threshold Model (LTM)
This is receiver-centric and models social pressure. A node only becomes active if the sum of weights from its active neighbors exceeds a specific threshold . This explains "tipping points" in social movements.
3. SIR/Epidemiological Models
Borrowing from biology, nodes transition between Susceptible, Infected, and Recovered states. This is increasingly used to model the spread of "viral" content or rumors.
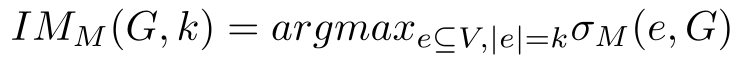
Algorithm Evolution: From Greedy to Scalable
The survey breaks down the "How" into four distinct generations of algorithms.
The Greedy Era (The Gold Standard)
The original Greedy algorithm provides a approximation guarantee. However, it is painfully slow.
- Innovation: CELF++ and SMG avoid unnecessary marginal gain calculations, significantly speeding up the process without sacrificing the approximation ratio.
The Structural Era (Centrality & PageRank)
Instead of simulating cascades, why not look at the graph's geometry?
- Closeness, Betweenness, and Degree Centrality identify "bottleneck" nodes.
- PageRank-based methods (like PPRank) allow for "random jumps," simulating a user discovering content outside their immediate circle.
The Community Era (Scale-First)
Large networks like Twitter or Facebook are too big for global search. Algorithms like INCIM and DIN partition the graph into communities.
- Insight: Influence within a community is dense; between communities, it is sparse. Finding "bridge nodes" that connect communities is the secret to global virality.
(Note: This diagram illustrates the trade-off between search space reduction and influence accuracy across different algorithm families.)
Recent Extensions: The Future of IM
The paper identifies three frontier shifts:
- Distributed IM: Using MapReduce and reservoirs to process graphs that don't fit in a single machine's memory.
- Dynamic IM: Tracking influential nodes as edges appear and disappear (e.g., trending topics on Twitter).
- Signed Networks: Accounting for "enemies" or negative sentiment. Influence isn't always positive; sometimes, a node's activation can deter others from joining.
Critical Insight & Conclusion
The "Influence Maximization Problem" is no longer just about marketing; it is a fundamental tool for public health (stopping epidemics) and political science. While Greedy algorithms offer the best theoretical guarantees, Community-based Heuristics are the only viable path for modern, multi-million node social graphs.
The next frontier? Semantic-aware IM, where the content of the message determines the probability of spread, not just the connection itself.
Takeaway: To maximize influence, don't just look for the highest degree; look for nodes that reside at the intersection of diverse communities.