
Personalized Academic Early Warning: A Gaussian Process Approach
Intelligent Educational Data Analysis with Gaussian Processes
This paper introduces a Gaussian Process (GP)-based framework for Academic Early Warning (AEW), utilizing Mixtures of Gaussian Processes (MGPR) for personalized key course selection and standard GP Regression (GPR) for course score prediction. By leveraging Automatic Relevance Determination (ARD) kernels, the system can identify specific courses that most significantly impact a student's academic standing across different clusters of learners.
Executive Summary
TL;DR: Researchers from East China Normal University have developed an intelligent Academic Early Warning (AEW) system using Gaussian Processes (GP). By combining Mixtures of GP (MGPR) for personalized course selection and standard GP Regression (GPR) for score prediction, the system provides students with specific, actionable advice rather than just a "failing" notification.
Context: This work moves beyond simple credit-counting statistics to a probabilistic Bayesian framework. It positions itself as a sophisticated solution for Educational Data Mining, addressing the "one-size-fits-all" limitation of previous machine learning models in student performance analysis.
The Problem: Why Current Warning Systems Fail
Most colleges use a binary "Academic Early Warning" system: if you fail credits, you get a letter. This approach has two fundamental flaws:
- Reactive, Not Proactive: It only triggers after the damage is done.
- Lack of Personalization: It treats every student the same. However, a student struggling with "Advanced Mathematics" needs different advice than one failing "C Programming."
Prior machine learning attempts often used global models that assumed every student’s academic path follows the same distribution. This ignores the multimodal nature of educational data—where students naturally cluster into groups based on their majors, background knowledge, and learning habits.
Methodology: Deciphering the Bayesian Engine
The authors propose a two-stage intelligent analysis pipeline.
1. Personalized Key Course Selection (MGPR)
To handle different groups of students, the paper uses Mixtures of Gaussian Process Regression (MGPR). Central to this is the Automatic Relevance Determination (ARD) kernel:
The Intuition: The "length-scale" parameter tells us how much a specific course influences the prediction. If is very large, the course is irrelevant. If it's small, that course is a "Key Course." Because the model is a mixture, it learns different values for different student clusters.
2. Intelligent Score Prediction (GPR)
Once key courses are identified, they are used to build a compact feature set. Instead of using a high-dimensional (and noisy) vector of every grade a student ever received, the authors use:
- Historical scores of the top 6 key courses.
- Correlation coefficients between historical key courses and the target predictive course.
 Figure 1: The conceptual flow of identifying hidden information in educational data.
Experiments & Critical Results
Training was conducted on real-world data from Grade 2010 and 2011 students at a university's CS department.
Diverse Insights
The MGPR successfully identified different "pain points" for different groups. For pedagogical classes, "C Programming" and "Education" were universal key courses. However, for specific sub-groups, "English" or "Advanced Mathematics" emerged as higher priorities, allowing for highly targeted tutoring.
Prediction Accuracy
The authors compared their "Key Course" feature selection against using "All Courses."
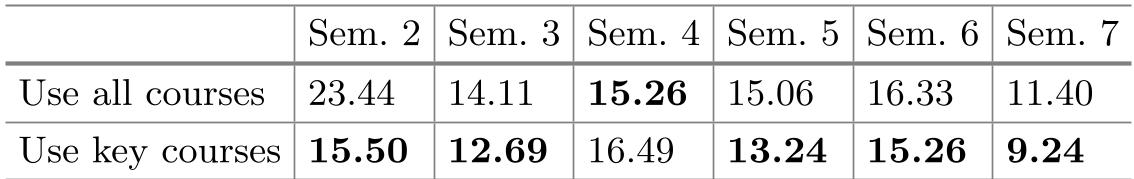 Table 2: Comparison of Average Prediction Errors (RMSE). "Use key courses" consistently yields lower error rates.
Key Findings:
- Dimensionality Reduction works: Using only key courses reduced noise and improved prediction accuracy (RMSE decreased significantly in 6 out of 7 semesters).
- Rank Consistency: As shown in Table 4 of the paper, the predicted rankings of students closely matched their true rankings, providing a reliable "danger list" for educators.
Critical Analysis & Conclusion
Takeaways
This paper demonstrates that Gaussian Processes are not just theoretical curiosities; their ability to provide uncertainty estimates and interpretable feature importance (via ARD) makes them superior to "black-box" neural networks for sensitive tasks like educational intervention.
Limitations & Future Work
- Cold Start: The model relies on historical grade data. It might struggle in the very first semester of a new curriculum where no correlations exist.
- Scalability: Standard GPs have complexity. While MGPR helps by splitting data, truly massive educational datasets (like MOOCs) would require Sparse GP approximations.
- Beyond Grades: Future work should integrate non-academic features (e.g., library log-ins, VLE activity) to augment the current "grade-only" approach.
In conclusion, by moving from "warning" to "advising," this GP-based framework provides a blueprint for the next generation of intelligent, empathetic educational management systems.