
Beyond the Final Whistle: Decoding Soccer Fan Sentiment via Higher-Order Markov Models
Learning the sentiment of soccer fans from data on bets and social nets
This paper proposes a Hidden Markov Model (HMM) framework to predict soccer fans' sentiment by treating emotional shifts as a latent stochastic process. Utilizing data from the "Torcida Virtual" social network, the study demonstrates that a second-order HMM incorporating match results and betting-derived favoritism achieves superior predictive accuracy compared to traditional classifiers.
TL;DR
Can we predict how a soccer fan feels without reading a single word they write? This research moves away from traditional NLP and treats sentiment as a Hidden Markov Process. By combining match results with "favoritism" data from virtual betting, the authors developed a second-order HMM that predicts fan mood with up to 75% accuracy, outperforming standard Machine Learning classifiers by respecting the temporal "momentum" of human emotion.
Background: The Problem with Static Sentiment
Most sentiment analysis tools ask: "What does this tweet say?" This paper asks: "How did the last three matches change the fan's internal state?"
The authors identify a critical "bias of silence": fans interact less with social media after a loss. If we only analyze text, we miss the silent frustration. By using Torcida Virtual, a Brazilian social network where fans explicitly log their mood, the researchers gained a ground-truth dataset that persists even when fans aren't "posting."
Methodology: Modeling the "Hidden" Heart
The core insight is that sentiment is a Latent Variable. We cannot see the "Sadness" directly through a scoreboard, but we can observe the "Outcome."
1. The Observation Space (The "What")
The authors didn't just look at Win/Loss/Tie. They introduced:
- Routs: A loss by 3+ goals has a different emotional weight than a 1-0 loss.
- Favoritism: Using a Power Law distribution of virtual bets, they determined if a team was a "favorite" or a "dark horse." Losing as a heavy favorite creates a different "hidden state" than losing as an underdog.
2. Architecture: Second-Order HMM
While a first-order Markov chain assumes your mood today only depends on yesterday, this paper utilizes a second-order HMM (HMM2).
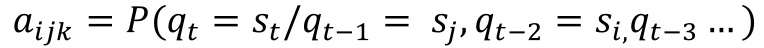
In this model, the probability of moving to a "Terrible" sentiment depends on the current state AND the previous state, capturing the "slippery slope" of a losing streak.
Experiments: HMM vs. The World
The researchers tested their model against standard discriminative classifiers: Support Vector Machines (SVM) and Naive Bayes.

Key Findings:
- Temporal Superiority: HMM2 (51% average accuracy) crushed SVM (37.1%) and the Baseline (34.2%). This proves that sentiment has a "memory."
- Generalizability: Interestingly, training the model on one team's fans and testing it on another did not decrease accuracy. This suggests soccer fans, regardless of their jersey color, share a universal "emotional physics."
- The "Good Times" Bias: The model was significantly more accurate for teams like Corinthians (75%) compared to Botafogo (17%). This is because the dataset was skewed toward positive results—fans are simply more likely to report their sentiment when winning!
Critical Analysis & Conclusion
The Power of Expectation
The most profound takeaway is the role of favoritism. A win is not just a win; it is a win relative to expectations. By using betting data as a proxy for social pressure, the model bridges the gap between raw data and human psychology.
Limitations
The primary weakness is the Positive Bias. Because fans are "fair-weather" reporters, the HMM struggles to model the nuances of a long-term downward spiral (as seen in the Botafogo results).
Future Outlook
This work lays the foundation for "Context-Aware" sentiment trackers. Future iterations could replace the discrete HMM states with Continuous State Spaces (like Kalman Filters) to model the intensity of sentiment, or utilize LSTMs to capture even longer-term historical dependencies.
Final Takeaway: To understand how someone feels today, you must know how they felt yesterday and what they expected from today. Sentiment is a story, not a snapshot.