
Linguistic-based Clustering: Breaking the "Chicken-and-Egg" Model Bias via Fuzzy Reasoning
On linguistic-based clustering
The paper introduces "Linguistic-based Clustering," a novel data mining method that utilizes fuzzy reasoning rules to classify data objects. By treating data points as entities with mass and velocity that move toward each other based on linguistic IF-THEN rules, the method achieves competitive performance compared to Agglomerative Hierarchical Clustering (AHC) without requiring prior knowledge of the data's mathematical structure.
TL;DR
Researchers from the University of Tsukuba have proposed a shift from model-based to linguistic-based clustering. Instead of relying on static mathematical models, this method uses fuzzy reasoning rules (IF-THEN) to guide data points as they move toward and merge with one another. By treating data points as dynamic entities with "mass" and "velocity," the approach achieves higher accuracy (Rand Index) on complex datasets than traditional Agglomerative Hierarchical Clustering (AHC).
Background: The Model Selection Paradox
In data mining, we use clustering to discover the structure of unknown data. However, most popular algorithms (like Hard c-means or Centroid-linkage AHC) require us to assume a model or a distance metric first. If the chosen model doesn't match the data's actual geometry, the result is worthless. This is a "chicken-and-egg" problem: you need to know the structure to choose the method, but you need the method to find the structure.
The authors propose that Fuzzy Reasoning, which has successfully replaced traditional PID controllers in complex engineering systems, can solve this paradox in clustering by providing an intuitive, rule-based classification mechanism.
Methodology: Data as Moving Objects
The core innovation is treating every data object as a physical particle with two attributes:
- Velocity (): Determines how fast an object moves toward its neighbors.
- Mass (): Represents the density of the data at that point.
1. The Rule-Based Engine
The "engine" of this movement is a set of linguistic rules. For example, in Rule Group 4, the movement is determined by both distance and mass:
- IF distance is Big AND mass is Light, THEN velocity is Big.
- IF distance is Big AND mass is Heavy, THEN velocity is Small.
This creates a "gravitational" effect where dense clusters (heavy mass) act as anchors, and individual points (light mass) are pulled toward them.
2. The Algorithmic Flow
The process follows a loop: calculate velocity update position merge points that are within a threshold update mass repeat.
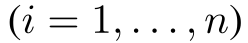 Note: The fuzzy inference follows the Min-max or Product-sum methods, followed by defuzzification (COG, MOM, or FOM) to get a real velocity value.
Experiments and Results
The authors tested the method against two artificial datasets and the UCI Breast Cancer dataset.
Performance on Complex Clusters
On the first artificial dataset, Rule Group 4 achieved a Rand Index of 0.957719, slightly outperforming the Centroid method (0.951105). More importantly, the method was far more robust on the second dataset, where the "Single Linkage" and "Centroid" methods often struggle with unequal cluster sizes.
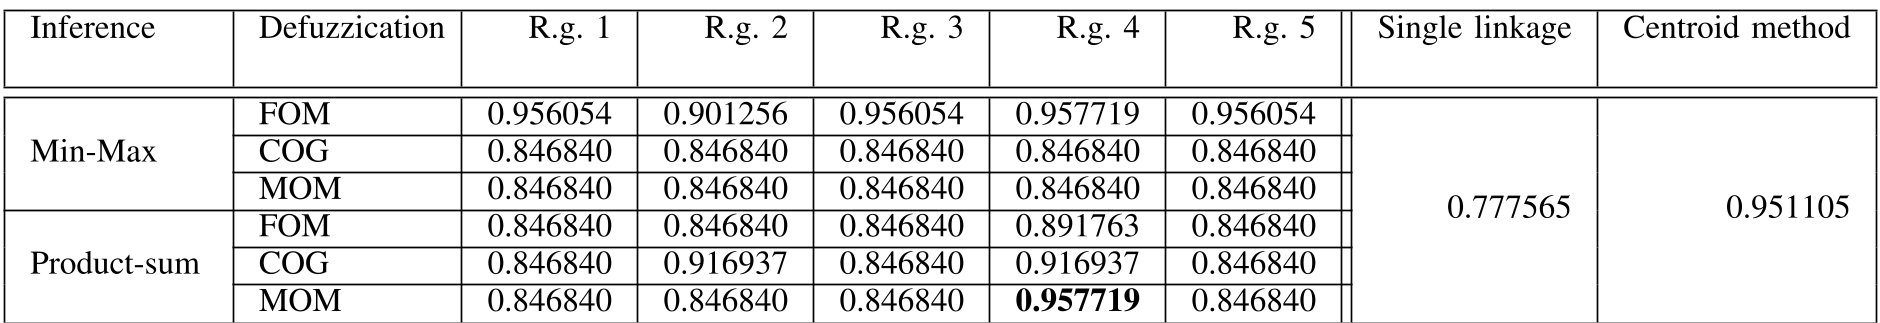 Table II: Rand Index results showing Rule Group 4's superior accuracy.
The Trade-off: Precision vs. Runtime
While linguistic clustering is more accurate and intuitive, it comes at a computational cost. The runtimes for fuzzy reasoning are significantly higher than traditional AHC (seconds vs. milliseconds). This is due to the iterative nature of updating positions and mass for every object in the dataset at every time step .
Critical Insight: Why Mass Matters
The most successful rule groups were those that included Mass. By considering mass, the algorithm implicitly accounts for data density. In datasets like the Breast Cancer set, which may follow a normal distribution, objects with large mass (the centers of clusters) stay relatively still while "collecting" lighter objects. This mimics the way humans naturally perceive clusters—as dense nuclei attracting surrounding points.
Conclusion and Future Outlook
Linguistic-based clustering offers a promising alternative for exploratory data analysis where the data structure is completely unknown. It bridges the gap between human intuition and machine classification.
Key Takeaways:
- Inductive Bias: By using linguistic rules, we replace rigid distance models with flexible logic.
- Dynamic Convergence: The "moving objects" metaphor allows for a more organic cluster formation than static partitioning.
- Future Work: The authors aim to introduce a simplified version of fuzzy reasoning to tackle the runtime bottleneck, making it more feasible for "Big Data" applications.
Disclaimer: This analysis is based on the paper "On Linguistic-based Clustering" by Sugawara et al.