
The Surprising Optimality of High-Degree Nodes: Solving Influence Maximization in the Voter Model
A note on maximizing the spread of influence in social networks
This paper addresses the "spread maximization problem" in social networks using the probabilistic Voter Model. Unlike previous threshold-based models, this work provides exact polynomial-time solutions and FPTAS for identifying the most influential individuals to maximize technological adoption.
TL;DR
While most viral marketing research focuses on complex algorithms to find "hidden" influencers, this paper reveals that for certain types of social dynamics, the simplest strategy is the best. In the Voter Model—where people flip-flop between opinions—the nodes with the highest number of connections are mathematically guaranteed to be the most influential. The authors provide an exact solution for short-term spread and an FPTAS for heterogeneous scenarios where influencers have different "costs."
Beyond Infection: Why the Voter Model?
Traditional influence models, such as the Linear Threshold (LT) model, treat information like a virus: once you are "infected" (adopt a product), you are infected forever. This is monotone.
However, the world isn't always monotone. We switch search engines, change political affiliations, and swap sneaker brands. This is where the Voter Model shines. In this model:
- A node looks at its neighbors.
- It picks one neighbor at random.
- It adopts that neighbor's opinion.
This allows for deactivation and continuous switching, making it a much more realistic proxy for competitive markets.
The Core Insight: Random Walk Duality
The mathematical elegance of this paper stems from a "reverse-view" of the network. The authors prove a crucial proposition:
The probability that node adopts the opinion of node after steps is exactly the probability that a random walk of length starting at ends at .
By mapping "influence" to "transition probabilities" (), the problem of maximizing the expected number of adopters becomes a problem of maximizing the sum of probabilities that random walks from across the graph land in your "seed set" .
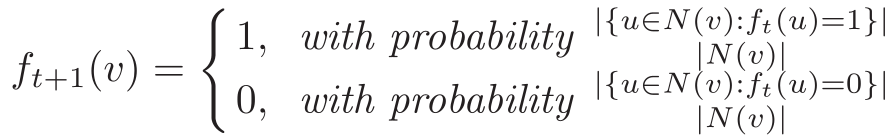
Methodology: From Matrices to Marketing
The authors break down the solution into two tactical timeframes:
1. The Short Term (Product Launch)
For any time that is polynomial in the number of nodes , the spread is maximized by calculating the vector .
- Uniform Costs: Simply sort nodes by their random-walk landing probability and pick the top .
- Varying Costs: The problem maps to a version of the Knapsack Problem. Since Knapsack is NP-hard but admits an FPTAS, the authors provide a Fully Polynomial Time Approximation Scheme for marketing budgets.
2. The Long Term (Brand Dominance)
When is large enough for the graph to reach a steady state (), the transition matrix converges. The probability of being at node becomes proportional to its degree .
The Discovery: If all influencers cost the same to "recruit," the optimal set is simply composed of the nodes with the highest degrees. This validates the common industry practice of targeting "social butterflies" with rigorous mathematical proof.
Impact and Results
The paper effectively shifts the complexity of influence maximization:
- LT/IC Models: NP-Hard to find optimal, requires greedy approximations ().
- Voter Model: Exactly solvable in or even linear time for long-term targets.
| Scenario | Algorithm Complexity | Optimality |
|---|---|---|
| Short term (Uniform Cost) | Exact | |
| Short term (General Cost) | FPTAS | Approx |
| Long term () | Linear (Sort by Degree) | Exact |
Critical Insight & Conclusion
The significance of this work lies in its simplicity. By identifying that the Voter Model possesses different mathematical properties than threshold models, the authors rescued a "natural heuristic" (targeting high-degree nodes) from being viewed as just a shortcut. In non-monotone dynamics, connectivity is the ultimate proxy for influence.
Limitations: The model assumes an undirected graph with self-loops, which might not perfectly capture the power dynamics of directed social media (like Twitter/X). However, as a baseline for opinion dynamics, it provides a powerful, efficient alternative to computationally expensive greedy simulations.