
Bridging the Gap in Affective Computing: A New Framework for Induced Emotional Databases
Methods and challenges for creating an emotional audio-visual database
The paper presents a methodology for creating an induced audio-visual emotional database using non-actors to simulate spontaneous realistic emotions. The authors utilize a framework involving video triggers and self-statements to evoke and capture four categorical emotions: neutral, sad, happy, and anger.
TL;DR
To move beyond the "theatrical" nature of acted emotions and the legal hurdles of spontaneous recordings, researchers at TCS Innovation Labs have developed a framework for creating an induced emotional audio-visual database. By using targeted video triggers and a dual-annotation system, they’ve created a methodology that captures emotions closer to real-life spontaneity while remaining viable for research distribution.
Background & Motivation: The "Acting" Problem
Most current Human-Computer Interaction (HCI) systems suffer from a lack of "emotional intelligence." They can process what you say, but rarely how you feel. Traditionally, researchers have relied on:
- Acted Data: Professional actors "performing" anger or joy. While clear, these are often too exaggerated for real-world AI applications.
- Spontaneous Data: Real-world recordings (e.g., call centers). These are authentic but plagued by privacy laws and "confidential information" issues.
The authors argue that induced emotion—where a subject is subtly nudged into an emotional state—is the "Goldilocks" solution for the next generation of Speech Emotion Recognition (SER).
Methodology: How to Evoke Authentic Feeling
The paper proposes a specific pipeline to trigger and record emotional responses without the subject feeling "on the spot."
The Setup
Subjects were placed in a professional environment and invited to go through an audio-visual presentation. The framework used two primary "triggers":
- Emotional Video Clips: Footage designed to elicit specific reactions (e.g., clips of Mr. Bean for happiness).
- Self-Statements: Subjects recorded their "prior" state (how they felt before the test) and their "post" state.
The Recording Pipeline
The flow was meticulously designed to capture different nuances of expression:
- Pre-presentation: Establish a neutral baseline.
- Trigger Phase: Subject watches the stimulus.
- Expression Phase: Subject reads sentences and provides a self-statement on their internal state.
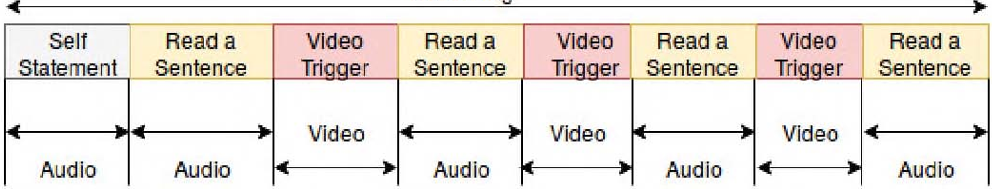 Figure 1: The structured sequence of triggers and reading tasks used to capture induced emotions.
Key Insights and Challenges
The study highlights several high-level "human" factors that often get lost in pure data science papers:
- The "Shadow" of Prior State: If a subject arrived stressed from work, the positive triggers were less effective. Capturing the initial mood is crucial for measuring the "delta" change in emotion.
- Instrument Interference: The researchers noted that excessive hardware (microphones, cameras) made subjects self-conscious. Moving toward non-invasive recording is essential for authenticity.
- Annotation Divergence: There is often a gap between how a person feels (self-annotation) and how they appear to others (external annotation).
Experimental Validation
To ensure the quality of the database, the authors calculated the Kappa Score to measure agreement among 10 annotators across categories like neutral, sad, happy, and anger.
| Metric | Value |
|---|---|
| Total Samples Evaluated | 100 |
| Mean Kappa Score (Audio) | 0.63 (Substantial Agreement) |
 Figure 2: Statistical breakdown of annotator agreement, showcasing the reliability of the induced labels.
Conclusion: A Foundation for Empathetic AI
This research underscores that creating an emotional database is as much about psychological orchestration as it is about technical recording. By focusing on four core emotions (Neutral, Happy, Sad, Anger), the authors have established a blueprint for datasets that are:
- Authentic: Closer to real-life than "acted" data.
- Legal: Avoids the privacy pitfalls of "spontaneous" data.
- Multi-modal: Captures the synergy between facial expressions and prosody.
Future Outlook: The next step for this field lies in scaling these induction methods to capture more complex, "blended" emotions (e.g., frustrated-sarcasm) which dominate human-human interaction.