
Decision Trees: Quantifying Financial Risk in Insurance Venture Rules
Mining Investment Venture Rules from Insurance Data Based on Decision Tree
This paper explores the application of Decision Tree classifiers to analyze insurance guarantee slips and compensation databases. Using the MineSet data mining tool, the authors identify key risk factors—specifically age, salary, and company type—to optimize investment venture rules and insurance premium adjustments.
TL;DR
In the high-stakes world of insurance, balancing competitive premiums with financial risk (venture) is a constant struggle. This paper presents a methodology using Decision Tree Classifiers to transform raw hospitalization data into actionable investment rules. By identifying critical thresholds—such as age and income levels—the authors provide a framework to move beyond "gut feeling" underwriting to quantitative risk management.
Problem & Motivation: The Limits of Human Experience
Historically, insurance analysts relied on subjective experience and basic statistical summaries. However, as databases grow to include thousands of records across diverse demographics, manual analysis becomes a bottleneck. The core challenge is twofold:
- Subjectivity: Different analysts might view the same data and reach different conclusions regarding risk.
- Hidden Patterns: Nonlinear relationships between attributes (e.g., the interplay between "Company Type" and "Salary") are nearly impossible to detect via standard queries.
The authors argue that Data Mining (KDD) provides the necessary "lens" to see these hidden patterns, specifically emphasizing the Decision Tree for its high interpretability and efficiency.
Methodology: Mapping the Decision Path
The research utilizes the MineSet tool by SGI to process hospitalization insurance databases. The workflow follows a rigorous technical pipeline:
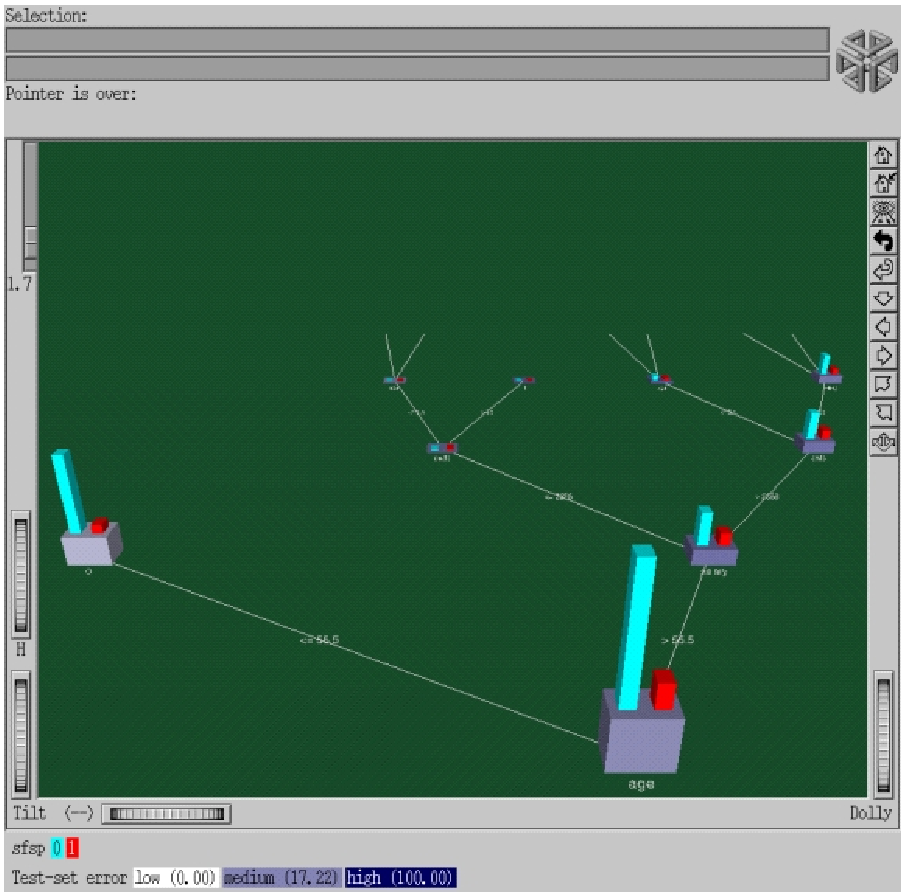
- Attribute Selection: Using "column weightiness," the researchers filtered out noise (like Insurance No. or Names) and identified that Age, Total Salary, and Type of Company were the primary drivers of compensation probability.
- Inducer Training: The system uses a training set (labeled data) to build a binary tree where internal nodes represent logical tests (e.g.,
Age > 56) and leaf nodes represent predicted outcomes ("Claim" vs. "No Claim"). - Visualization: The tree allows for a "fly-over" analysis, providing a spatial representation of risk distribution.
Mathematical Intuition
The "split" logic at each node is designed to maximize information gain. For instance, the system found that splitting the population at the age of 56 provided the cleanest separation between high-risk and low-risk policy-holders.
Experiments & Results: Beyond Simple Averages
The experiments yielded startlingly clear quantitative rules. In a dataset of 6,401 records, the baseline compensation rate was 16.00%. However, the Decision Tree revealed:
- The Age Threshold: Policy-holders under 56 had only a 9.61% claim rate. Those over 56 saw the rate climb to 27.69%.
- The Corporate Effect: Interestingly, workers in public institutions were found more likely to file claims than those in private enterprises. The authors hypothesize an economic incentive: public institution employees often face lower out-of-pocket costs, making them more likely to seek medical care for minor ailments.
| Profile | Predicted Probability | Actionable Insight |
|---|---|---|
| Age 58, Enterprise Employee, High Salary | 9.84% | Potential for Premium Discount |
| Age 59, Public Institution, Low Salary | 37.56% | Need for Premium Increase |
Critical Analysis & Conclusion
While the Decision Tree offers unmatched interpretability (crucial for regulatory compliance in insurance), the paper acknowledges several technical limitations:
- Overfitting: With too many attributes, the inducer might "memorize" noise.
- Dynamic Markets: If the distribution of future records changes (e.g., a sudden health crisis), the model's error rate will spike.
Takeaway
The shift from Option Trees (which offer higher precision but lower speed) to Decision Trees represents a strategic choice between accuracy and comprehensibility. For the insurance industry, the ability to explain why a premium was raised—based on a specific path through a Decision Tree—is as valuable as the prediction itself. This study serves as an early blueprint for the "InsurTech" revolution, proving that data-driven rules are the ultimate tool for risk control.