
MTL-Emotion: Leveraging Multi-task Learning to Decode the Crowd's Emotional Pulse
A Multi-task Learning Framework for Time-continuous Emotion Estimation from Crowd Annotations
2014-11-03
Summary
Problem
Method
Results
Takeaways
Abstract
This paper introduces a Multi-task Learning (MTL) framework for time-continuous emotion estimation (Valence and Arousal) in movie scenes using noisy crowd annotations. By treating different movie clips as related tasks, the authors effectively model the relationship between low-level audio-visual features and dynamic emotional responses.
## TL;DR
Predicting how a movie makes us feel *moment-by-moment* is challenging because everyone reacts differently. This paper proposes a **Multi-task Learning (MTL)** framework that treats individual movie clips as related "tasks." By training on noisy crowdsourced annotations from Amazon Mechanical Turk, the model learns to filter out individual biases and identify the core audio-visual triggers—like color and motion—that consistently drive our emotional highs and lows.
## The Subjectivity Trap: Why Standard Models Fail
Affective video tagging usually focuses on a "global" emotion (e.g., "This is a sad movie"). However, emotions are dynamic. Capturing this continuous flow requires massive amounts of data. Using experts is too expensive, but using the "crowd" introduces noise: workers have different demographics, varying attention spans, and subjective interpretations of "valence" (pleasure) and "arousal" (excitement).
Traditional Single-Task Learning (STL) treats each clip in isolation, struggling to distinguish between a worker's unique bias and the actual emotional content of the video.
## The Insight: Strengths in Numbers (and Tasks)
The authors' core intuition is that while clips differ, the **underlying mechanisms** of how humans perceive emotion from sound and vision are shared. By using Multi-task Learning, the model can:
1. **Identify Temporal Salience**: Discovering which segments of a clip (e.g., the final seconds) most heavily influence the overall emotional impression.
2. **Feature Selection**: Pinpointing which low-level features (like *Lighting Key* or *MFCC* audio components) are universally relevant across different types of content.
## Methodology: The MTL Toolbox
The researchers extracted **56 audio features** and **49 video features** per second. They then applied several MTL variants to map these features to the crowd's "Gold Standard" (median) ratings:
* **Multi-task Lasso**: Assumes all clips share the same subset of important features.
* **$\ell_{2,1}$-norm Regularized MTL**: Encourages feature selection across all tasks simultaneously.
* **Sparse Graph Regularization (SR-MTL)**: Incorporates prior knowledge about which clips are similar (e.g., grouping high-arousal action scenes).
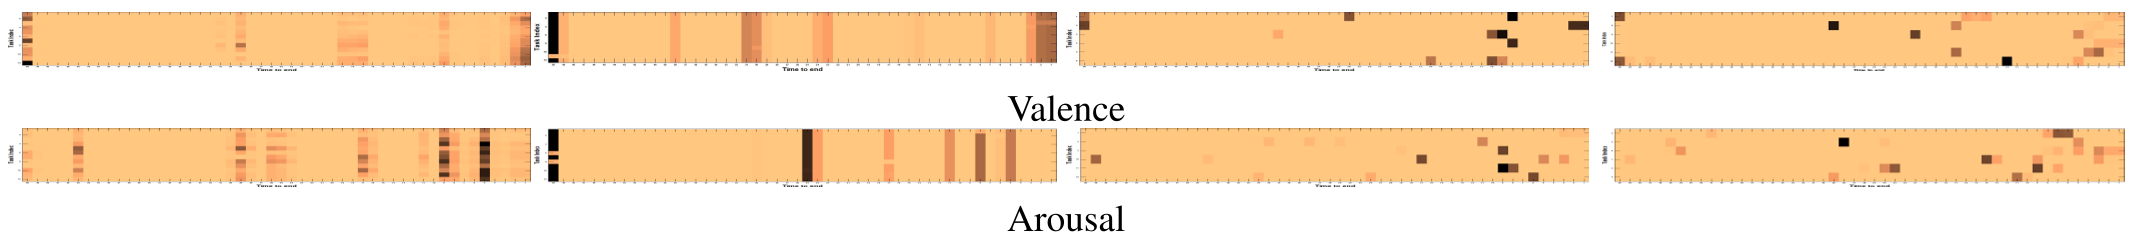
*Figure: Heatmaps showing that weights for dynamic annotations are higher towards the end of clips, confirming that "peaks" and "end-moments" define our overall memory of an experience.*
## Experimental Victory: MTL vs. The World
The results were decisive. In almost every scenario—whether predicting the "front" or "back" of a scene—MTL methods crushed the standard Lasso regressor.
| Task (Valence) | Metric | Lasso (Baseline) | MT-Lasso (Proposed) |
| :--- | :--- | :--- | :--- |
| Video (5s Front) | RMSE | 0.429 | **0.191** |
| Audio (5s Front) | RMSE | 0.475 | **0.241** |
### Key Findings:
* **Arousal is easier to predict than Valence**: Motion cues are very strong indicators of excitement, whereas "pleasure" is more subtle.
* **Audio is a powerful signal**: The first few MFCC components (audio thumbprints) were found to be highly salient for both emotion dimensions.
* **The "Recency Effect"**: Predictions for the end of clips were more difficult (higher error) because that is where the most complex emotional changes often occur.
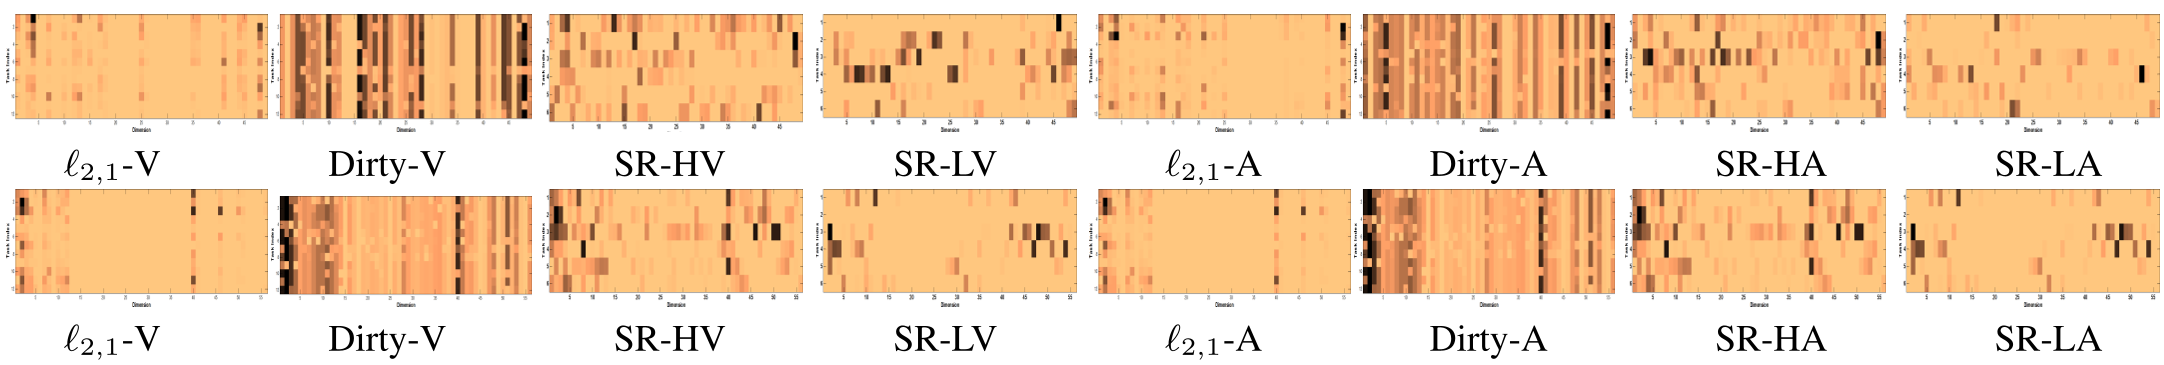
*Figure: Visualization of feature correlations showing how specific audio frequencies and color variances drive the model's decisions.*
## Critical Analysis & Future Horizon
This work proves that **MTL is an effective "noise filter"** for subjective human data. However, the study used a relatively small set of 12 clips. The next frontier involves scaling this to thousands of videos and integrating broader physiological cues (like the facial expressions the authors recorded but haven't yet utilized in this specific model).
For developers in media recommendation or automated video editing, the takeaway is clear: don't just look at what one user says about one video. Look at the shared patterns across your entire library to find the true "emotional DNA" of your content.