
SEFSBRS: Balancing Diversity and Accuracy in Emotion Recognition via Rough Set Theory
A Novel Emotion Recognition Approach Based on Ensemble Learning and Rough Set Theory 1
The paper introduces SEFSBRS (Selective Ensemble Feature Selection based on Rough Set theory), a novel framework for emotion recognition. The methodology integrates Rough Set Theory for attribute reduction with a selective ensemble strategy, achieving high accuracy by balancing base classifier diversity and individual performance.
TL;DR
Recognizing human emotion is a cornerstone of Human-Computer Intelligent Interaction (HCII). In this paper, researchers from Chongqing University of Posts and Telecommunications propose SEFSBRS, a method that uses Rough Set Theory to strip away redundant data and a Selective Ensemble strategy to pick the "best" team of classifiers. The result? A system that is faster, uses fewer resources, and achieves recognition rates exceeding 90% in specific datasets.
The Motivation: Why "More" Isn't Always "Better"
In machine learning, we often assume that having more data or more classifiers will lead to better results. However, in the complex domain of emotion recognition—where features are extracted from facial expressions or audio—irrelevant attributes act as "noise."
Traditional ensemble methods like Bagging or Boosting often produce base classifiers that are too similar (lacking diversity). An ensemble of 100 people who all make the same mistake is no better than one person. The authors realized they needed a way to:
- Identify the most essential features (Attribute Reduction).
- Select a subset of classifiers that are both accurate and different from one another.
Methodology: The Core of SEFSBRS
1. Rough Set and Reducts
The authors use Rough Set (RS) Theory to handle the uncertainty of emotional data. The primary tool here is the Discernibility Matrix.
- Reducts: These are the smallest possible subsets of attributes that can classify the data as well as the original full set. By finding all possible reducts, the authors create a pool of candidate classifiers, each "looking" at the problem through a different, minimal lens.
2. The Diversity Measure (Double Fault)
To ensure the ensemble isn't redundant, they use the Double Fault (DF) measure. This calculates how often two classifiers fail on the same instances. Lower correlation in failure means higher diversity.
3. Selective Ensemble Strategy
Instead of using all generated classifiers, the algorithm:
- Clusters the base classifiers based on their diversity.
- Selects pairs from these clusters that exhibit the highest disagreement.
- Integrates them using simple majority voting.
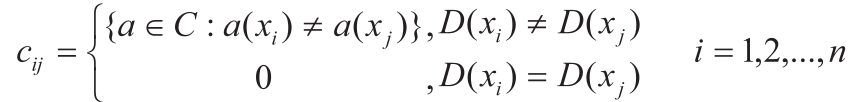 Figure 1: The mathematical definition of the Discernibility Matrix used to extract core features.
Experimental Results
The researchers tested their approach against three distinct databases to account for cultural variations: CKACFE (Western), JAFFE (Eastern female), and CQUPTE (Chinese).
| Method | Avg. Classifiers | Recognition Rate (%) |
|---|---|---|
| SEFSBRS (Proposed) | 6.67 | 81.13 |
| CEBARKNC (Baseline) | 1.00 | 71.69 |
| Ensemble All | 13.33 | 80.29 |
 Figure 2: Sample images from the three emotional databases used in the study.
Observation
The "Ensemble All" strategy used 13.33 classifiers on average to get an 80.29% accuracy. SEFSBRS achieved a higher average accuracy (81.13%) using only half the number of classifiers (6.67). This proves that intelligent selection is more effective than brute-force combination.
Critical Analysis & Conclusion
The true value of this work lies in the efficiency of the Rough Set approach for feature selection. In an era where "Real-Time" interaction is critical for Smart Homes and Virtual Reality, reducing the computational load by 50% while maintaining SOTA performance is a significant win.
Takeaway: Diversity is the "secret sauce" of ensemble learning. By mathematically quantifying disagreement (via DF measure) and filtering features (via Rough Sets), we can build leaner, smarter AI.
Limitations: While effective, the paper relies on classical classifiers. Integrating this Rough Set selection with modern Deep Learning backbones like Transformers or CNNs could be the next frontier for reaching near-perfect recognition rates.