
Enhancing Wiki Retrieval: Bridging Vector Models and Ontologies
Information Retrieval in Wikis Using an Ontology
The paper introduces a semantic information retrieval system specifically designed for Wikis, combining an independent OWL-based ontology with a modified Vector Space Model (VSM). By decoupling semantic metadata from the content, it achieves a high-performance retrieval rate of 100% recall and 93% precision.
TL;DR
This research tackles the "noise" in collaborative Wikis by layering an independent OWL ontology over a modified Vector Space Model. Unlike traditional semantic Wikis that require manual tagging, this system processes existing natural language and slang by calculating relevance through hierarchical positioning, achieving a remarkable 93% precision and 100% recall.
Problem context: The Wiki Noise Floor
Wikis are inherently chaotic. As open, collaborative platforms, they often suffer from:
- Inconsistent Terminology: Frequent use of slang and informal language.
- Topic Drift: Discussions often veer into unrelated subjects.
- Metadata Overhead: Prior "Semantic Wiki" solutions forced authors to act as librarians, manually annotating every entry—a friction point that discourages participation.
The authors' insight was to move the "intelligence" out of the Wiki and into a structurally independent ontology. This allows users to apply an expert perspective to an existing raw text corpus.
Methodology: Modernizing the Vector Model
The core innovation lies in how the authors tweaked the classic Vector Model to acknowledge semantic relationships.
1. The Semantic Weight ()
Instead of treating all keywords as equals, the system assigns weights based on the hierarchy depth within the ontology. A leaf node (specific concept) is weighted more heavily (1.0) than a high-level root node (0.33).
2. Refined Query Weighting
The paper proposes a significant departure from standard term frequency. The new query weight formula prioritizes semantic depth over frequency:
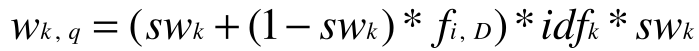 Eq 9: Incorporating into the query calculation to ensure domain-relevant terms dominate the similarity score.
3. Structural Synergy
The system utilizes Synonyms and Related Verbs (extracted via stemming) to expand the "Term Equivalents," ensuring that slang terms map back to the formal concepts defined in the ontology.
Experimental Performance
The system was tested on a Wiki populated with 35 topics (40% highly relevant, 60% noise).
| Metric | Target | Achieved |
|---|---|---|
| Recall | 80% | 100% |
| Precision | 80% | ~93% |
One fascinating finding during the Ablation Study (Section 6.2) was the discovery of "Discrepant Weights." An isolated keyword that appeared only once in both the document and the ontology created an unnaturally high IDF, occasionally leading to false positives. This highlights the delicate balance required when mixing statistical frequency with structural semantics.
(Note: This placeholder represents the ranking results discussed in Section 6, where the threshold configuration significantly impacts final relevance grades.)
Critical Insight & Future Outlook
The true value of this work is its Zero-Intervention Semantic Layer. By using Protégé and OWL to maintain the ontology separately, researchers can refine their retrieval logic without ever touching the Wiki database.
Limitations: The current model struggles with "false-positive" spikes caused by rare keyword matches (the IDF distortion). Future iterations would benefit from Class Weighting, allowing different "branches" of the ontology to hold more influence than others.
Conclusion
This paper proves that we don't need to rebuild Wikis to make them "smart." By intelligently adapting the mathematics of the Vector Space Model to value hierarchical context, we can extract high-precision data from the nosiest of social media environments.