
Designing the Crowd: Why HIT Design is the Backbone of IR Evaluation
Categories and Subject Descriptors: H.3.4 [Information Storage and Retrieval]: Systems and Software-performance evaluation (efficiency and effectiveness)
This paper investigates the effectiveness of crowdsourcing for book search evaluation, specifically the "Prove It" task from INEX 2010. It explores how Human Intelligence Task (HIT) design, pooling strategies, and document ordering influence the quality of relevance labels and the resulting comparative ranking of IR systems.
TL;DR
As digital libraries scale to millions of volumes, traditional expert-led evaluation has hit a wall. Crowdsourcing seems like the logical escape hatch, but "noisy" workers often threaten the validity of the results. This paper dissects how advanced task design—using logic-based questionnaires and "captchas"—can produce high-fidelity relevance labels that mirror expert rankings, while highlighting that standard metrics like MAP might be deceptively resilient to poor data quality.
The Scalability Crisis in Specialized Search
The "Cranfield paradigm" has governed Information Retrieval (IR) evaluation for 50 years, relying on a gold standard of expert judgments. But in the domain of book search (e.g., the INEX Book Track), the numbers don't add up. Judging a single topic can take an assessor 33 days of dedicated work.
Crowdsourcing (via platforms like Mechanical Turk) offers a "mechanical labor" solution, but it introduces a fundamental tension: financial incentives drive speed, while evaluation requires accuracy.
Methodology: Engineering Engagement
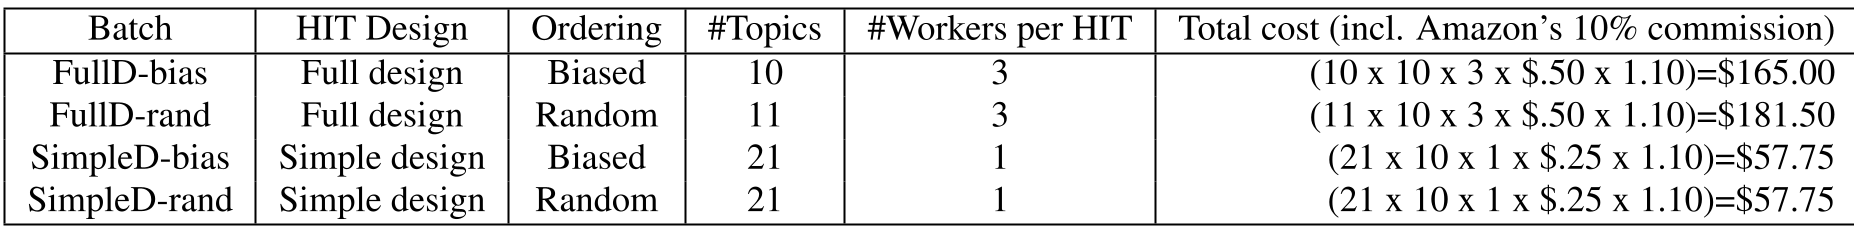
The authors hypothesized that the "Human Intelligence Task" (HIT) design itself acts as a filter for worker quality. They compared a Simple Design (SimpleD) against a Full Design (FullD).
The "FullD" Arsenal:
- Skip-Logic (Flow): Instead of a simple radio button, workers followed a path of dependent questions. If a worker claimed a page "conforms" to a claim but then couldn't answer the logically subsequent question, the system flagged the inconsistency.
- Book Captchas: To prove they actually read the page, workers had to enter a specific word from a confirming/refuting sentence.
- Priming and Professionalism: HIT titles included topic details to attract "interested" workers rather than click-bots.
Key Findings: The "Hidden" Failure of MAP
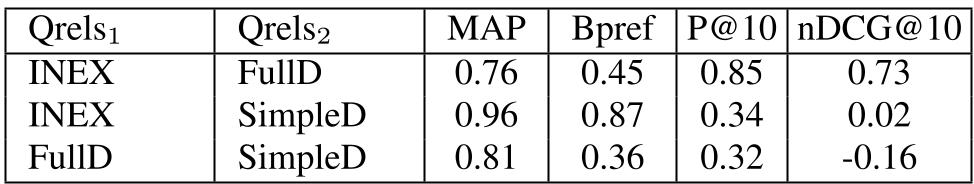
The most striking insight from this study involves how we measure IR system success. The authors found that even with "messy" data from SimpleD HITs, the Mean Average Precision (MAP) and Bpref rankings remained highly correlated with expert rankings.
Why? This is likely due to the "pooling effect"—if the pool of documents is high-quality, even semi-random labeling can sometimes preserve a general ranking.
However, when looking at the top of the rank list (Precision@10 and nDCG@10), the SimpleD rankings fell apart. This proves that for "precision-oriented" tasks, poor HIT design leads to catastrophic evaluation failures.
Critical Insight: Randomness vs. Bias
The study investigated document ordering. Paradoxically, placing a "known relevant" page at the top of a HIT (Biased Order) actually lowered label accuracy compared to a random order.
- The Intuition: Biased ordering creates "pattern-matching" behavior where workers stop thinking and start looking for expected distributions. Randomness forces constant cognitive re-engagement.
Conclusion & Future Outlook
This work moves crowdsourcing from a "naive" collection of labels to an "engineered" process. The takeaway for the industry is clear: Don't trust the crowd; trust the system that controls the crowd.
As we move into an era where "Large Language Models" are used to evaluate other models, the lessons learned here regarding "skip-logic" and "challenge-response" mechanisms will be critical in designing the next generation of automated evaluation pipelines to prevent "model collapse" or halluncinated feedback loops.
Limitations
- Cost vs. Effort: The FullD HITs cost significantly more and took longer to complete, representing a trade-off that might not always be feasible for smaller budgets.
- Task Complexity: This study focused on "Prove It" (fact-checking) tasks. The results might vary for more subjective "Exploratory" search tasks where a "Gold Standard" is harder to define.