
Real-Time Quality Control: Professionalizing Crowdsourced Relevance Evaluation
Real-time quality control for crowdsourcing relevance evaluation
The paper introduces a real-time quality control framework for crowdsourced relevance evaluation, specifically designed for the TREC 2011 Crowdsourcing Track. It utilizes a multi-layered screening approach—including qualification tests, time-spent monitoring, and trap questions (gold standards)—to filter "bad workers" and ensure high-fidelity search engine result labeling.
TL;DR
Crowdsourcing relevance labels for search engines is often a trade-off between cost and quality. This paper from BUPT presents a robust Real-Time Quality Control (RT-QC) strategy used in the TREC 2011 Crowdsourcing Track. By moving beyond simple "Majority Voting," the authors implement a workflow that filters out poor workers during the task using qualification tests, time-spent analysis, and gold standards, ensuring high-fidelity data acquisition at a fraction of the cost of experts.
The Core Conflict: Cost vs. Trust
In the realm of Information Retrieval (IR), the "Gold Standard" has traditionally been the expert judge. However, human-based computing (Crowdsourcing) via platforms like Amazon Mechanical Turk (AMT) has introduced a massive "Idle Human Labor" force.
The problem? Trust. Unlike experts, crowd workers often exhibit:
- Unintentional Slop: Due to misunderstanding the task.
- Intentional Noise: Workers trying to finish tasks as quickly as possible for monetary gain.
Previous SOTA methods focused on Post-Evaluation (e.g., using EM algorithms or Confusion Matrices after labels are collected). This paper argues that this is too late—we need to stop "bad workers" at the gate.
Methodology: The Three Pillars of Real-Time QC
The authors' insight was to create a multi-layered filter that operates synchronously with the task execution.
1. The Qualification Gateway
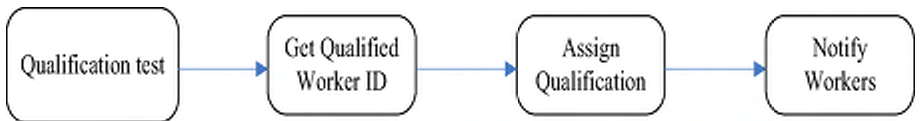
Before a worker can even touch the dataset, they must pass a qualification test. This establishes a baseline of "ability" and understanding of the task's relevance criteria.
2. Time-Spent Monitoring
One of the most effective proxies for conscientiousness is the time spent on a Human Intelligence Task (HIT). The authors tracked completion times, assuming that a response submitted in sub-natural time (e.g., 2 seconds for a complex document) is statistically likely to be noise.
3. Gold Standard & Trap Questions
By embedding "Golden Questions" (tasks with known ground-truth answers), the system can calculate a worker's accuracy in real-time. If a worker fails a certain threshold of these trap questions, they are restricted from further participation.
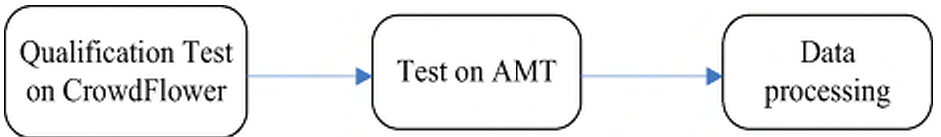 Note: The paper utilizes a structured workflow involving these metrics to ensure that only "good" workers contribute to the final label consensus.
Experiments and Results
The strategy was tested on the TREC 2011 Crowdsourcing Track. The evaluation used standard metrics (Accuracy, Recall, Precision, Specificity) to compare crowd labels against expert judgments.
Key findings included:
- Efficiency: The real-time filtering significantly reduced the need for redundant "Majority Voting" by increasing the reliability of individual labels.
- Filtering Efficacy: The combination of time-spent and gold-question tracking effectively isolated "spammers" who previously skewed statistical models like simple Majority Vote.
 (The authors utilized these comparative statistics to validate that their real-time strategy provides a cleaner signal than unmonitored crowdsourcing.)
Critical Insights & Future Outlook
While the paper focuses on the TREC relevance task, the Real-Time QC philosophy has profound implications for modern AI. Today, as we scale RLHF (Reinforcement Learning from Human Feedback) for Large Language Models, the "Bad Worker" problem is more relevant than ever.
Limitations: The strategy relies heavily on the quality of the "Gold Questions." If the gold questions are too easy, they don't filter mediocre workers; if they are too hard, they frustrate good ones.
The Takeaway: Quality control in crowdsourcing is not a post-processing step; it is an architectural requirement. Future systems should look to integrate Active Learning, where the system identifies which workers are most reliable in real-time and dynamically assigns tasks to them.
Conclusion
This work highlights that "Cheap and Fast" can indeed be "Good," provided that the human-in-the-loop is subjected to rigorous, real-time algorithmic scrutiny.