
Restoring Capitalization in Tweets: Bringing Order to the Chaos of #SocialMedia
ResToRinG CaPitaLiZaTion in #TweeTs
The paper introduces a statistical truecaser designed specifically for Twitter, utilizing an SVM-based capitalization classifier and a 3-gram language model. By integrating news data with 200,000 informatively capitalized tweets, the method achieves significant improvements in Named Entity Recognition (NER) and Part-of-Speech (PoS) tagging for noisy social media text.
TL;DR
Twitter is a goldmine for NLP, but its "noise"—especially erratic capitalization—often breaks standard tools. This paper presents a specialized statistical truecaser using a 3-gram language model and a Support Vector Machine (SVM) classifier. By training on a blend of newswire and filtered "well-behaved" tweets, the authors significantly boost the performance of Named Entity Recognition (NER) and Part-of-Speech (PoS) tagging on microblog content.
Background: The Case of the Missing (or Extra) Capitals
In formal writing, capitalization is a strong signal for proper nouns and sentence boundaries. In tweets, however, users often use all-caps for shouting, all-lowercase for speed, or "tYpInG lIkE tHiS" for emphasis.
The authors identify a critical gap: standard truecasers (like Stanford's) are trained on formal text and struggle with the slang and brevity of Twitter. If an NER system expects "New York" but receives "new york," it might miss the entity entirely.
Methodology: The Truecasing Pipeline
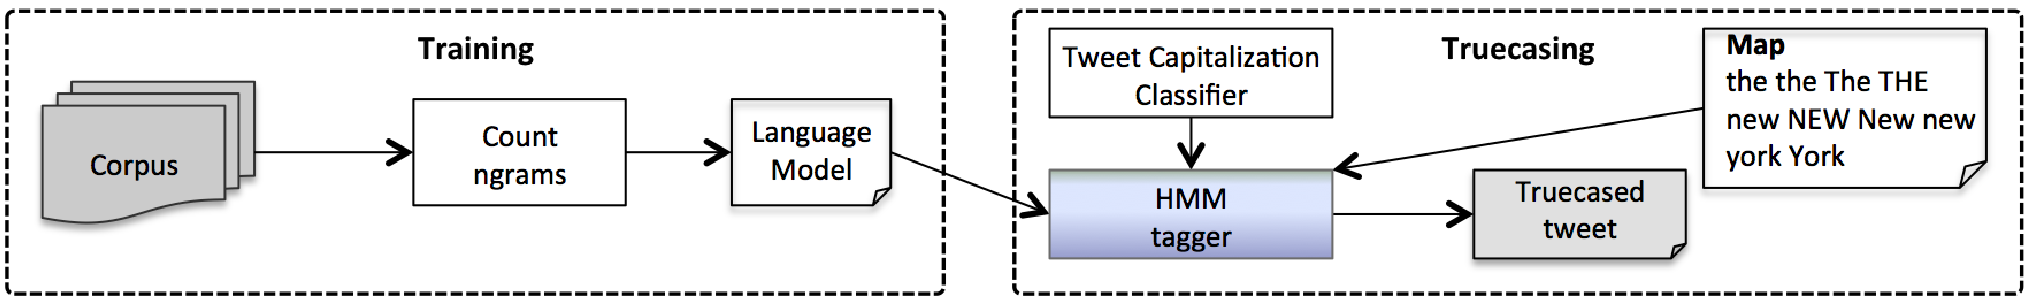
The authors' approach is not a "one-size-fits-all" filter. It involves a sophisticated three-step pipeline:
- Informative Casing Detection: An SVM classifier (achieving 94.91% accuracy) first decides if a tweet is already correctly capitalized. It uses features like the fraction of capitalized words and the presence of proper nouns.
- Lowercasing: If the casing is deemed "uninformative," the tweet is neutralized to lowercase.
- Statistical Restoration: An HMM-based tagger uses a 3-gram language model to predict the most likely original case.
The secret sauce lies in the training data: a massive 2-billion-word corpus combining the English Gigaword (newswire) with 200,000 tweets that were pre-identified as having "informative" capitalization.
Experiments & Results: Does it actually help?
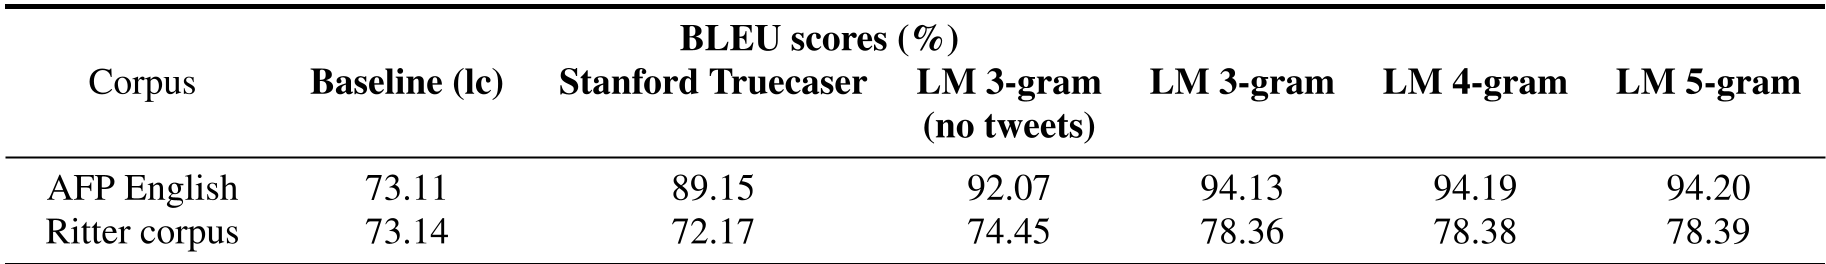
The authors evaluated their tool using the BLEU score (standard in Machine Translation) and downstream NLP performance.
1. Truecasing Accuracy
On the Ritter tweet dataset, the proposed 3-gram model achieved a 78.36% BLEU score, significantly higher than the Stanford Truecaser's 72.17%. Interestingly, increasing the model to a 4-gram or 5-gram only provided marginal gains, making the 3-gram the "sweet spot" for speed and accuracy.
2. Boosting NER and PoS Tagging
The real test is whether this improves "real" tasks.
- Stanford NER: The F1-score rose from 73.25% to 74.64% on the MSM dataset.
- PoS Tagging: Token accuracy reached 90.27%.
Crucially, the authors found that TwitIE (a microblog-specific tool) did not improve with truecasing. This reveals an important insight: truecasing is only beneficial if the secondary algorithm actually relies on case features.
Critical Analysis & Conclusion
Takeaway
The paper demonstrates that domain adaptation is key. Simply using a news-trained truecaser on Twitter can actually introduce more noise. By filtering for "good" tweets to include in the training set, the authors captured the specific context of social media (e.g., knowing that "auburn" is likely the University/Team "Auburn" in a sports context).
Limitations
The system is still purely statistical and 3-gram based. While efficient, it may struggle with very long-range dependencies or highly creative neologisms that haven't appeared in the 2-billion-word corpus. Furthermore, the reliance on a dictionary "Map" of 1.1 million entries suggests that OOV (Out-of-Vocabulary) words remain a challenge.
Final Thought
As we move toward LLM-based normalization, this paper serves as a foundational reminder of the importance of signal-to-noise ratio in social media. Effective truecasing isn't just about "fixing" text—it's about restoring the underlying semantic structure that "noisy" users have stripped away.