
Trustrace: Rescuing Traceability from Semantic Decay via Repository Mining
Trustrace: Mining Software Repositories to Improve the Accuracy of Requirement Traceability Links
This paper introduces Trustrace, a trust-based framework for recovering requirement traceability links between source code and free-text requirements. By combining traditional Information Retrieval (IR) techniques with insights from mining software repositories (CVS/SVN and bug-tracking systems), it achieves SOTA accuracy gains in software maintenance contexts.
TL;DR
Requirement traceability links—the maps connecting what a system should do to the code that does it—often rot as software evolves. Trustrace is a sophisticated framework that stops relying purely on code-to-text similarity. Instead, it "interrogates" software repositories (commits and bug reports) as trusted experts to validate and rerank traceability links, boosting precision by nearly 23%.
The Problem: The "Semantic Gap" and Obsolete Links
In a perfect world, code and requirements stay in sync. In reality, developers update the source but forget the documentation. Over time, the textual similarity between a requirement ("Process user login") and the actual class (AuthManager.java) weakens.
Current state-of-the-art Information Retrieval (IR) models like VSM or JSM are "blind" to the history of the project. They look at a snapshot of text, see low similarity, and discard valid links, or they see high similarity between unrelated terms and create false positives.
Methodology: The Trust-Based Architecture
The authors treat traceability recovery like an e-commerce platform. If multiple "reputable" sources (Experts) say a link is valid, our trust in that link increases.
1. Histrace: The Expert Miner
Instead of just looking at the final code, Trustrace mines:
- CVS/SVN Commits: "If a commit message mentions a requirement and touches these 5 classes, those classes are likely linked to that requirement."
- Bug Reports: Linking bug IDs to commits allows the model to trace requirements through the "bug-fix" lifecycle.
2. Trumo & DynWing: Smart Re-ranking
The Trumo engine takes the baseline links from an IR model and adjusts their similarity scores based on Histrace's findings. However, not all experts are equally reliable for every link.
The DynWing component is the "secret sauce"—it calculates weights per-link rather than globally. It formulates weight assignment as a maximization problem to ensure that for any specific class-requirement pair, the most "knowledgeable" expert has the most say.
 Figure 1: High-level architecture showing the flow from baseline IR to Expert mining and Trust-based reranking.
Experimental Validation
The authors tested Trustrace on four diverse systems (jEdit, Pooka, Rhino, SIP). The results were definitive:
- Precision Power: In Rhino, Trustrace boosted precision from ~72% to over 94%.
- Weighting Matters: Comparing DynWing to Principal Component Analysis (PCA) showed that per-link dynamic weighting is far more effective than static statistical weighting.
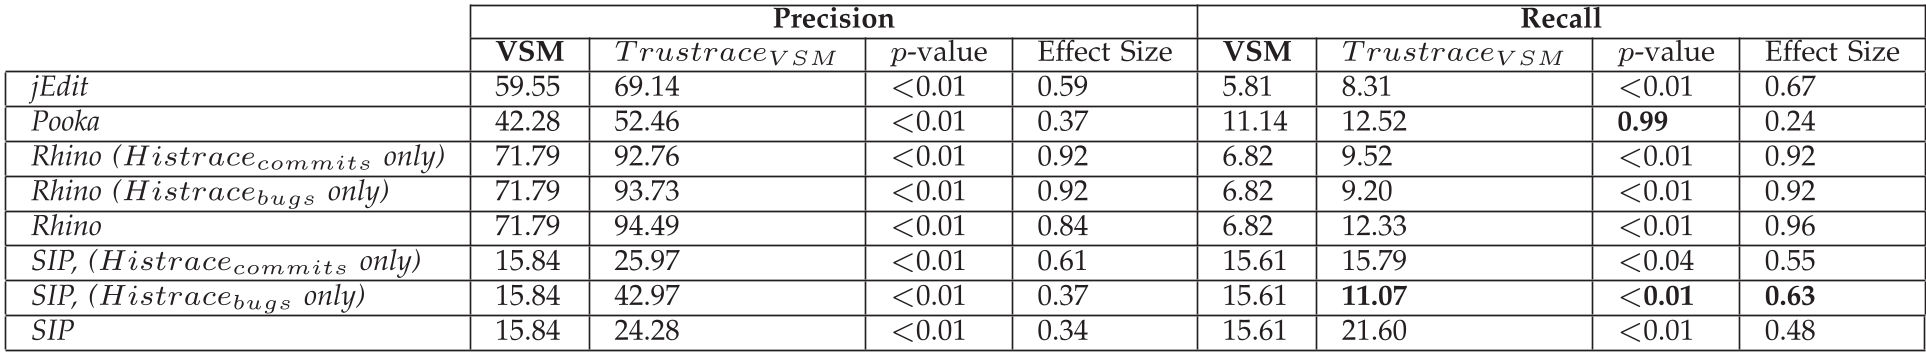 Figure 2: Performance gains showing Trustrace consistently outperforming VSM across multiple open-source projects.
Critical Insight: Why it Works
The core intuition is that while documentation might be stale, development history is a pulse. A commit message like "Fixed issue in drag-and-drop" is a high-fidelity signal that bridges the gap between the high-level concept ("drag-and-drop") and the low-level code, even if the code itself uses cryptic abbreviations like dnd.
Conclusion & Future Outlook
Trustrace proves that software repositories are not just graveyards of code history—they are rich knowledge bases. By shifting from a "static snapshot" view to a "reputation-based" view, we can recover traceability with significantly less human intervention.
Future Directions: The authors suggest expanding Histrace to include mailing lists and forum discussions, potentially using even more "human" signals to refine the map of software.