
Beyond the "Always-On" Translation: Empowering Authors in the Global Booth
User-Controlled Content Translation in Social Media
This paper introduces a user-centric framework for machine translation (MT) in social media, specifically focusing on providing authors with transparency and control. It proposes a prototype that allows bilingual authors to preview, edit, or manually override automated translations to prevent privacy leaks and cross-cultural misunderstandings.
TL;DR
While machine translation (MT) has turned social media into a global village, it has done so by stripping authors of their agency. This paper argues that authors—not just audiences—need control over how their words are translated. By introducing a prototype that allows for pre-translation editing and sensitivity detection, the research aims to prevent privacy breaches and "lost-in-translation" career risks.
The "Invisible" Translation Problem
On platforms like Facebook or Twitter, translation is a ghost process. An author posts in their native tongue, and the platform automatically serves a translated version to others. Historically, the author:
- Cannot see the translation being served.
- Cannot edit errors in the automated output.
- Cannot prevent sensitive information (intended for a specific culture) from being exposed globally.
This creates a "Context Collapse" where a post meant for close friends in one language is misinterpreted by a global audience due to the nuances of Neural Machine Translation (NMT) or simple synthetic noise.
Methodology: The Author-Control Prototype
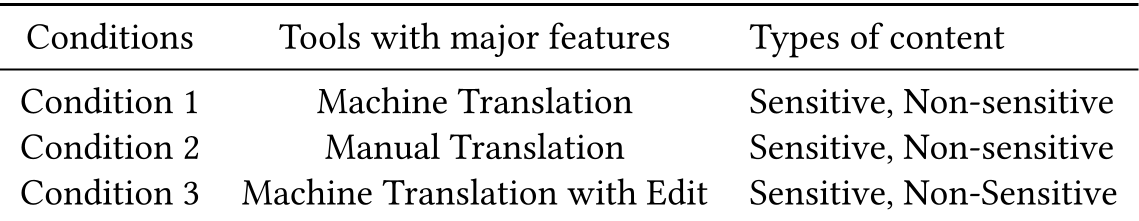
The researcher proposes a 3x2 experimental design to test how different levels of control affect posting behavior. The core of the study is a prototype system that moves translation from an afterthought to a pre-publication step.
The System Architecture
The proposed tool doesn't just translate text; it analyzes it. The pipeline includes:
- Google Cloud Translate API: For the baseline translation.
- IBM Watson NLU: To detect the sensitivity and sentiment of the post.
- TextRazor/Wikipedia APIs: For Keyword Analysis and Named Entity Recognition (NER) to ensure proper nouns aren't mangled.
Three Levels of Control
- Standard MT: View the translation and "Allow" or "Reject."
- Manual Translation: Write the translation from scratch (High effort, High privacy).
- MT-with-Edit: The "Golden Mean" where users fix minor MT errors before publishing.
Experimental Insights & Expected Results
The study categorizes posts into Sensitive (location, personal data) and Non-Sensitive.
The expected results indicate a significant preference for MT-with-Edit. This suggests that while users appreciate the speed of AI, they do not trust it with their digital identity. For sensitive posts, the "willingness to post" increases only when the author has a "veto" or "edit" power over the translation.
Critical Insight: Privacy as a Linguistic Variable
The most profound takeaway here is that Privacy is not universal; it is contextual and often linguistic. By translating a post without the author's consent, we are effectively "unlocking" a private room without a key. This research highlights the need for AI systems to respect Linguistic Inductive Bias—the idea that some things are meant to stay in the original language.
Conclusion & Future Outlook
This work sets the stage for "Human-in-the-loop" translation in social settings. Future extensions, such as Back-translation (showing the author what the translation looks like if it were translated back to their native tongue), could further bridge the gap for users who don't speak the target language comfortably. In the era of LLMs, giving authors the "Editor's Pen" is no longer a luxury—it is a privacy requirement.
Keep an eye on this space as the author moves from survey results to full prototype deployment.