
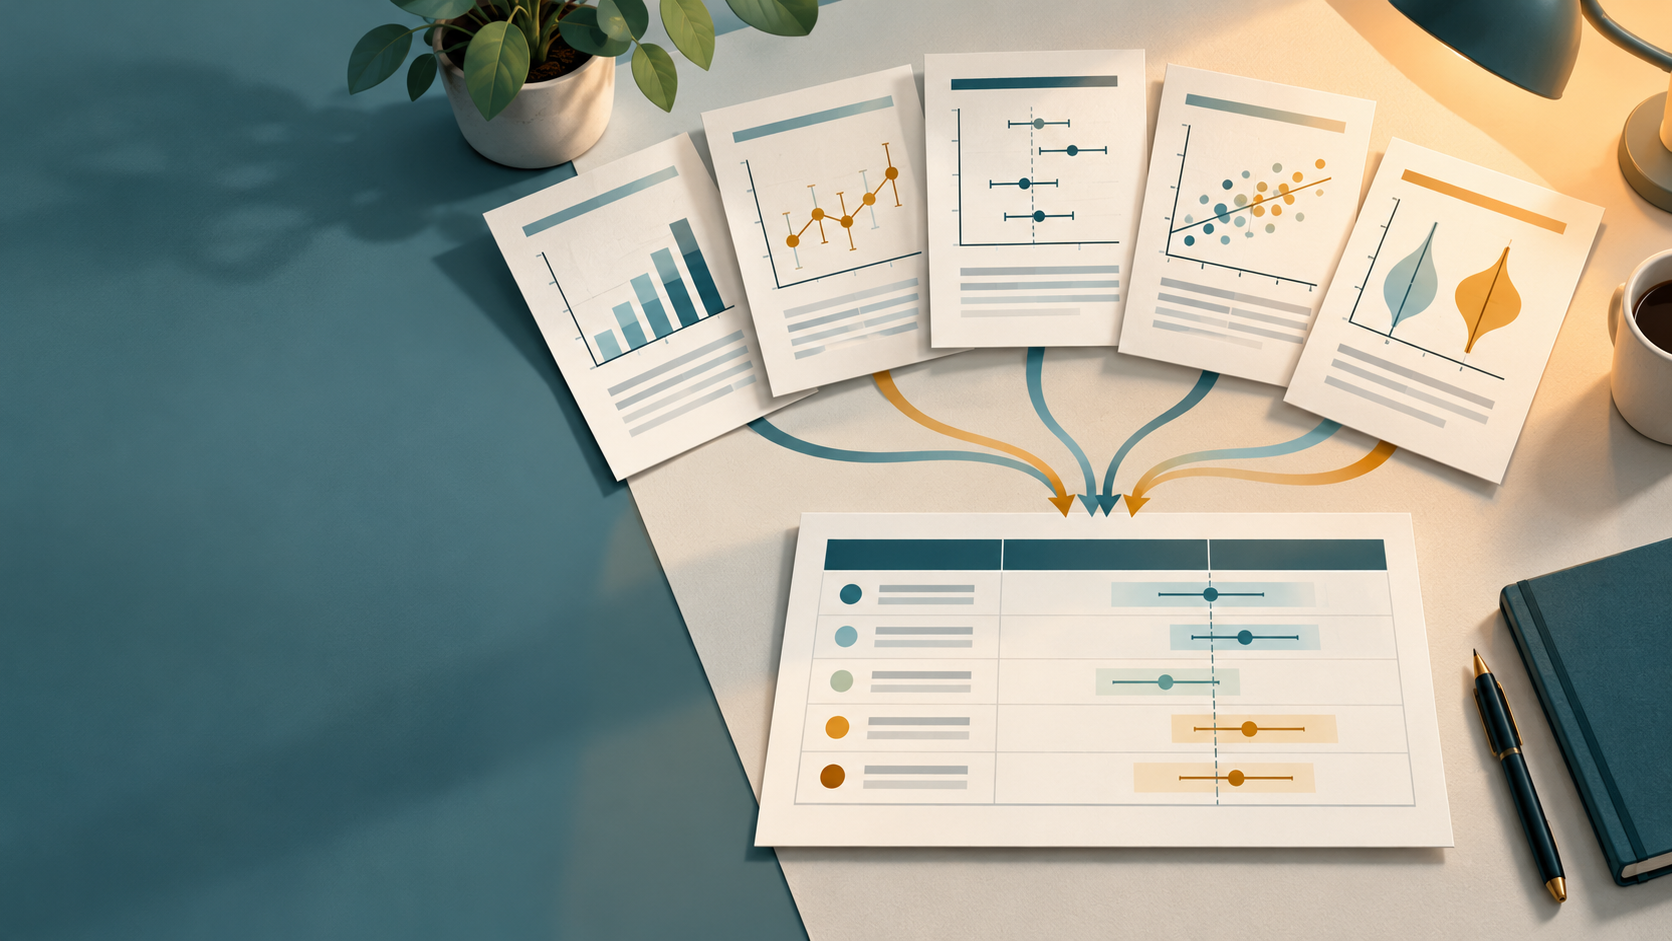
You have five studies that all claim to measure "the same outcome," yet the numbers do not line up. One reports a mean with a standard deviation, another a median with an interquartile range, a third a percentage change from baseline, and a fourth a composite score on a scale you have never seen. Before you write a single sentence of synthesis, you face a decision that will shape your entire manuscript: what can legitimately be compared, and what must be reported side by side without being pooled?
This guide walks through that decision as a research team would actually make it. It starts with the evidence problem, moves through a repair process that standardizes definitions and measures, preserves units and uncertainty, and ends with a corrected deliverable and lessons that transfer to your next review, revision, or grant summary.
Start With the Evidence Problem, Not the Table
The temptation is to open a spreadsheet and start transcribing numbers. Resist it. The first task is to describe, in plain language, why the five studies are not yet comparable. Common reasons include:
- Different construct definitions. "Treatment response" may mean a threshold on one scale in one paper and a percentage reduction in another.
- Different measurement instruments. Two validated scales can both claim to measure the same domain without being interchangeable.
- Different summary statistics. Means and medians describe different features of a distribution and cannot be swapped casually.
- Different units and time windows. A change over four weeks is not the same outcome as a change over twelve.
- Different populations or comparators. Even a perfectly harmonized measure may describe groups that should not be pooled.
Write these differences down before you touch the data. That written record becomes the backbone of your methods section and your audit trail.
Build an Auditable Method Trail From the Beginning
A synthesis that cannot be reconstructed is hard to defend in peer review. The Cochrane Handbook's guidance on searching and selecting studies is useful here even though it addresses search rather than outcome harmonization: it recommends planning from explicit eligibility criteria, documenting the process, deduplicating records, screening in stages, and linking multiple reports of one study. Those habits transfer directly.
For outcome standardization, an auditable trail typically includes:
- A protocol note stating which outcomes you will harmonize and which you will report narratively.
- A source log recording where each study was found and how it entered your set.
- A decision log capturing every harmonization choice, who made it, and why.
- A version history so a reviewer can see what changed between drafts.
If you are still assembling the study set, the WisPaper search interface is designed for finding academic papers, and the WisPaper Scholar Search page explains the entry point for finding papers. Keep the search itself documented: PubMed's search details, for example, reveal how terms were translated and combined, which is exactly the kind of record that makes a method trail reproducible.
Decide What "the Same Outcome" Actually Means
The single most valuable move is to separate three questions that are often blurred together:
- Same construct? Do the studies claim to measure the same underlying thing?
- Same instrument? Do they use the same scale or test?
- Same summary? Do they report the same statistic in the same units?
Only when all three align can you compare numbers directly. When the construct aligns but the instrument differs, you may be able to describe direction and magnitude cautiously. When the construct itself differs, the honest move is to report the studies side by side and explain the divergence.
A practical test: write a one-sentence definition of the outcome, then check each study against it. If a study fails the definition, it does not belong in the pooled comparison—no matter how similar its label looks.
Standardize Definitions Before You Standardize Numbers
Harmonizing numbers without harmonizing definitions produces false precision. Work in this order:
Step 1: Write operational definitions
For each outcome, specify the construct, the instrument, the time window, the population, and the direction of benefit. Keep these definitions in a shared document so every co-author works from the same text.
Step 2: Map each study to the definition
Create a table with one row per study and columns for construct, instrument, time window, summary statistic, and unit. Mark mismatches explicitly rather than smoothing them over.
Step 3: Classify comparability
Assign each study to one of three tiers: directly comparable, comparable with caveats, or not comparable. Record the reason for each assignment in your decision log.
Step 4: Decide the reporting format
Directly comparable studies can share a table or forest-style summary. Studies with caveats should carry a footnote explaining the difference. Non-comparable studies belong in a narrative section with their original numbers intact.
Preserve Units and Uncertainty at Every Step
Units and uncertainty are the first things lost when numbers move between documents. Protect them deliberately.
- Carry units in the column header, not the cell. A column labeled "change (mg/dL)" prevents the unit from being dropped when rows are copied.
- Record the summary statistic alongside the value. A median of 12 and a mean of 12 are not the same claim.
- Keep dispersion measures paired with their statistic. Standard deviations belong with means; interquartile ranges belong with medians. Do not attach one to the other.
- Preserve confidence intervals and sample sizes. These are part of the result, not optional decoration.
- Note transformations. If you convert a unit or rescale a score, record the conversion factor and the source of that factor in the decision log.
When you draft the manuscript, report each study's original statistic and unit first, then your harmonized presentation. That ordering lets a reader verify your work and keeps the audit trail visible in the published text.
Use Tools at the Step They Actually Support
Tooling helps most when it is attached to a specific step rather than sprinkled across the workflow.
- Finding and screening papers. Use a scholarly search interface to build the candidate set, then document how each record entered the review.
- Organizing the evidence. Once papers are identified, save or upload them and organize them in My Library. A single organized collection makes it far easier to keep definitions, units, and decision notes attached to the right study.
- Asking questions across your collected papers. When you need to check how a specific study defined an outcome, Library QA lets you ask questions based on papers uploaded to My Library or added from search results. Use it to locate the relevant passage, then verify the wording against the paper itself before you transcribe anything.
- Longer synthesis tasks. For extended literature work, the Scholar Agent area supports literature review, inspiration, and reproduction use cases. Check its draft against your decision log before moving a conclusion into the synthesis.
A general orientation to these capabilities is available on the WisPaper English homepage, which introduces WisPaper as an AI research assistant for finding, screening, organizing, and working with academic papers.
Work Through a Concrete Repair
Imagine a team preparing a review on a clinical outcome reported across five studies. The first draft table looks tidy but is quietly wrong: it lists five numbers in one column under a single heading.
The repair proceeds in four moves.
Move 1: Reopen the definitions. The team writes an operational definition specifying the construct, instrument, time window, and direction of benefit. Two studies fail the definition because their time windows differ substantially; they are moved to a narrative section.
Move 2: Rebuild the table. The remaining three studies get separate columns for summary statistic, dispersion measure, unit, and sample size. Footnotes explain any remaining instrument differences.
Move 3: Restore uncertainty. Confidence intervals and sample sizes are re-entered from the original papers. A conversion applied to one study is documented with its factor and source.
Move 4: Write the comparability statement. A short paragraph in the methods explains the three-tier classification and points readers to the decision log.
The corrected deliverable is not a single pooled number. It is a transparent table plus a narrative that tells the reader exactly which studies can be compared, which cannot, and why.
Draft the Comparability Statement Reviewers Will Look For
Reviewers rarely object to cautious synthesis; they object to unexplained synthesis. A strong comparability statement does four things:
- Names the outcome and its operational definition.
- States the classification rule used to sort studies into comparable, caveated, and non-comparable tiers.
- Explains any harmonization applied, including unit conversions and their sources.
- Points to the decision log or supplementary file where the full trail lives.
Keep this statement close to the results table so a reader can move between claim and evidence without hunting.
Deliver the Corrected Artifact
The final deliverable usually has four parts:
- A harmonized results table with units in headers, dispersion paired with its statistic, and footnotes for caveats.
- A narrative section for studies that could not be compared, preserving their original numbers.
- A methods paragraph containing the comparability statement.
- A supplementary decision log documenting every choice.
If the work spans multiple outputs—a manuscript, a revision response, and a grant summary—organizing them in Research Projects keeps the related materials together as the project develops.
Lessons That Transfer
The same discipline applies far beyond a single review:
- Define before you count. Operational definitions come first; numbers come second.
- Separate construct, instrument, and summary. Most false comparisons collapse one into another.
- Keep units and uncertainty attached to values. They are part of the result.
- Classify comparability explicitly. A three-tier scheme is easy to defend and easy to audit.
- Document every choice. The decision log is the difference between a reproducible synthesis and an unreproducible one.
- Let tools serve a step. Search finds papers, a library organizes them, and question-answering helps you locate passages—each at its own point in the workflow.
FAQs
Keep Reading
Full-Text Search vs. Title-and-Abstract Search: Choosing the Right Retrieval Layer for a Manuscript
When you are building the evidence base for a manuscript, a review, or a revision, the first real decision is not which database to open but which layer of each record you search. Title-and-abstract search reads the shor
Google Scholar Alerts vs. PubMed Saved Searches for Staying Current
Staying current on a clinical or biomedical question is a recurring maintenance task, not a one-time search. Two familiar options sit at opposite ends of the control spectrum: Google Scholar alerts, which watch a broad s
Google Scholar vs. Crossref for Checking a Suspicious Citation
A suspicious citation usually arrives in one of two forms: a reference in a manuscript you are reviewing that does not quite look right, or a line in your own draft that you cannot fully place. The fastest way to settle