
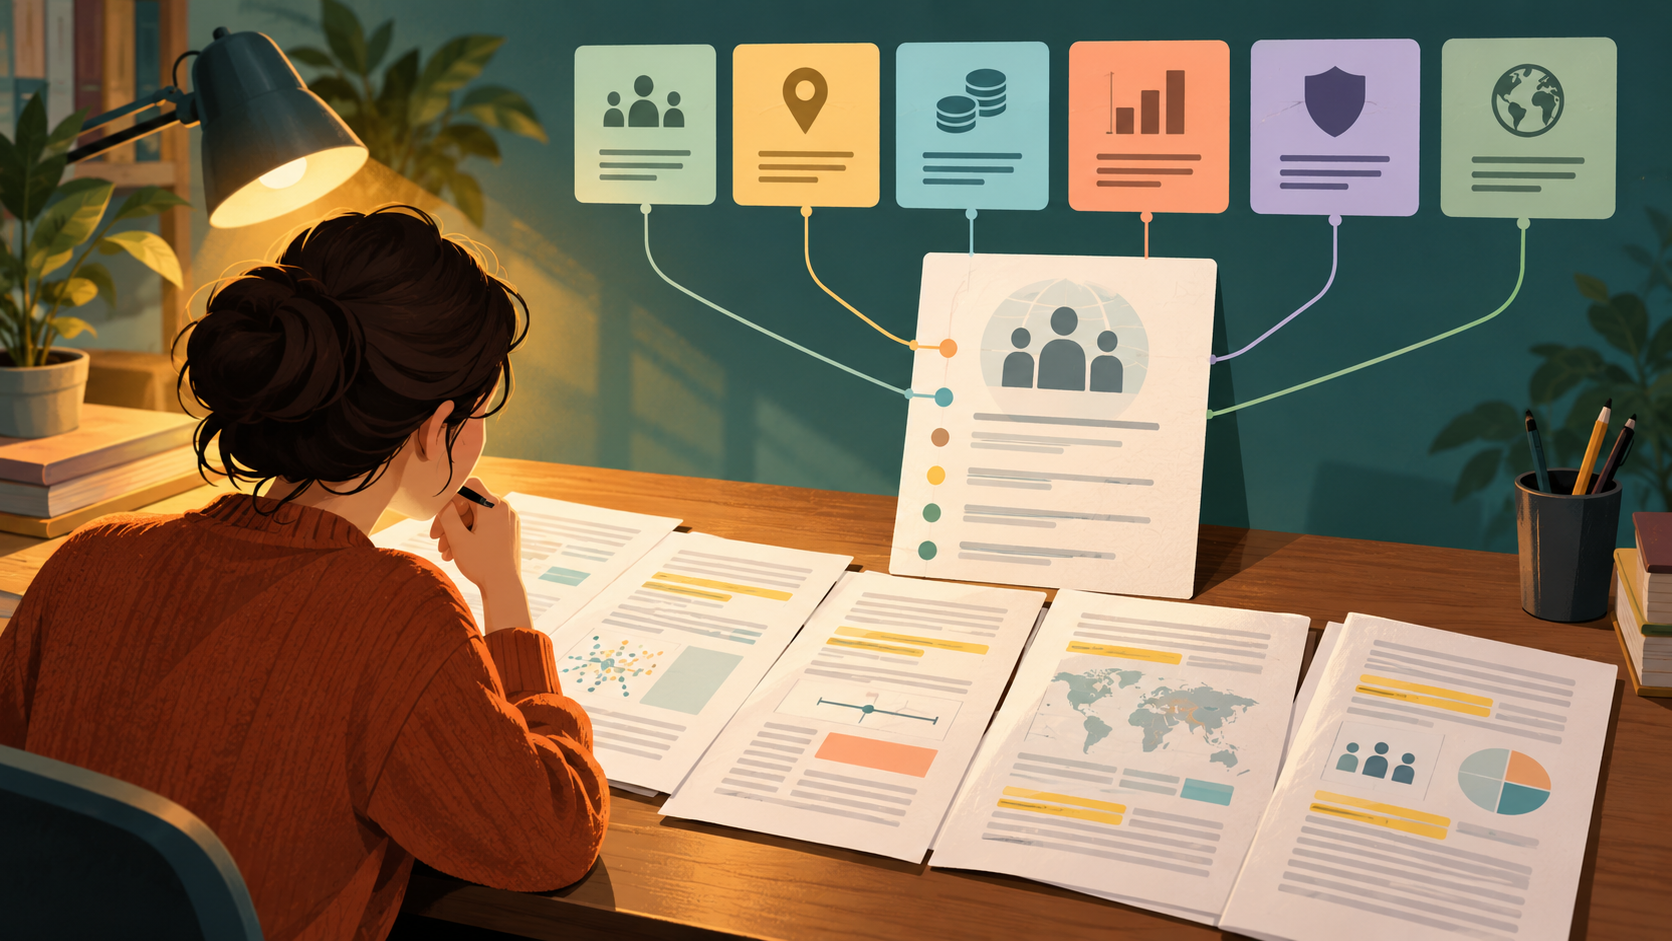
You have a promising paper in front of you, a deadline on the calendar, and one nagging question: do these results actually apply to the people, setting, or problem you are writing about? Applicability is a judgment you build step by step, not a feeling you get from an abstract. The practical answer is to compare the study against your own target on six dimensions — eligibility, baseline risk, setting, intervention delivery, outcomes, and follow-up — and to record a decision at each checkpoint.
This guide gives you that sequence, a worked example under deadline pressure, and a reusable checklist. It also shows where a research assistant such as WisPaper fits into the workflow: finding candidate papers, organizing them, and asking questions of the ones you have saved.
Start by writing down your own target
Before you judge any study, define what you are trying to apply results to. Write one or two sentences naming:
- The population you care about (age range, condition, care stage, or context).
- The comparison or decision the evidence is meant to inform.
- The outcome that matters for your paper or project.
- The constraints on your own setting, such as available resources or time frame.
This statement becomes your reference point. Without it, every study looks either perfectly relevant or hopelessly distant, and you will drift toward whichever conclusion is convenient near the deadline.
Build a candidate set before you judge applicability
Applicability checks only work on the right papers. Cochrane guidance on searching and selecting studies recommends planning searches from explicit eligibility criteria, using multiple sources, combining free-text terms with subject headings, documenting the process, deduplicating records, and screening in stages. That is a sound structure even for a course paper.
A practical sequence:
- State eligibility criteria in writing before you search.
- Search more than one source and combine keywords with subject headings.
- Record what you searched so you can describe it later.
- Remove duplicates, then screen titles and abstracts before full texts.
- Link multiple reports that describe the same study so you do not double-count it.
If you need to find academic papers through a scholarly search interface, WisPaper search is one place to run that step. For a public explanation of the same entry point, see WisPaper Scholar Search.
The six-dimension applicability check
Run every candidate study through the same six questions. Record a short answer for each, plus a verdict: include, include with caveat, or exclude.
1. Eligibility: who was actually studied?
Compare the study's inclusion and exclusion criteria with your target population. Note age, condition severity, prior treatment, and any groups deliberately left out. A study can match your topic while studying a narrower group than you need.
2. Baseline risk: how similar is the starting point?
Ask what the participants' risk or starting state was before the intervention. Results framed around a very different baseline may not transfer cleanly to your population. Record the baseline characteristics the study reports and compare them to your target.
3. Setting: where did the study take place?
Note the care setting, country or system, and resource level. A finding produced in one setting may depend on infrastructure your context lacks. State the difference plainly rather than assuming it away.
4. Intervention delivery: what exactly was done, and by whom?
Capture the dose, duration, provider, and delivery format. If your context cannot deliver the intervention the same way, mark that as a caveat and say what would change.
5. Outcomes: are they the ones you need?
Check whether the study measured the outcome your paper cares about, how it was defined, and when it was measured. A related but differently defined outcome is a caveat, not a match.
6. Follow-up: is the time frame long enough?
Record how long participants were followed. If your question concerns longer-term effects than the study observed, say so explicitly.
Diagnostic checkpoints that force a decision
Vague notes produce vague papers. Use three checkpoints to convert your reading into decisions.
Checkpoint A — after abstract screening. For each retained paper, write one line on population and one on outcome. If either is clearly outside your target, exclude it now and note why.
Checkpoint B — after full-text reading. Complete all six dimensions. Assign the include / include-with-caveat / exclude verdict. This is where most applicability judgments should be finalized.
Checkpoint C — before you write your synthesis. Re-read your verdicts together. If two included studies disagree, check whether the difference traces to setting, baseline risk, or delivery — that comparison is often the most useful paragraph in your paper.
A reusable applicability table
Copy this into your notes and fill one row per study.
| Dimension | What to record | Match to my target? | Verdict |
|---|---|---|---|
| Eligibility | Inclusion/exclusion criteria, key subgroups | Yes / Partial / No | |
| Baseline risk | Starting characteristics reported | Yes / Partial / No | |
| Setting | Care setting, system, resource level | Yes / Partial / No | |
| Intervention delivery | Dose, duration, provider, format | Yes / Partial / No | |
| Outcomes | Outcome definition and timing | Yes / Partial / No | |
| Follow-up | Length of observation | Yes / Partial / No |
Add a final column for a one-sentence justification. That sentence is what you will adapt into your manuscript.
Organize the papers you keep
Once screening settles, keep the retained set in one place so your applicability notes stay attached to the right paper. My Library lets you save or upload papers and organize them in the WisPaper library. Grouping by verdict — include, caveat, exclude — keeps your reasoning visible when you return to write.
If your project spans several related questions, Research Projects is the WisPaper area for creating and managing a project.
Worked example: a student paper on a deadline
Suppose a student is writing a course paper on a community-based program and has one week left. The rubric rewards a clear justification of evidence selection, not volume.
Day 1 — define the target. The student writes: adults in community settings, program delivered by trained staff, outcome measured at six months, resource-limited context.
Day 2 — search and screen. Using explicit criteria, the student searches, deduplicates, and screens titles and abstracts. Three papers survive.
Day 3 — full-text applicability check.
- Paper 1 matches population and outcome but was delivered in a high-resource hospital setting. Verdict: include with caveat on setting.
- Paper 2 matches setting and delivery but followed participants for only three months. Verdict: include with caveat on follow-up.
- Paper 3 studies a different age group entirely. Verdict: exclude, with a one-line reason.
Day 4 — ask questions of the saved papers. With the retained papers in the library, the student uses Library QA to ask questions based on papers uploaded to My Library or added from search results — for example, to re-check how each paper defined its outcome before writing the comparison.
Day 5 — draft the synthesis. The student writes a short applicability paragraph per paper, using the caveats already recorded. The rubric's justification criterion is met with evidence rather than assertion.
Day 6 — supervisor feedback. The supervisor flags that the setting caveat on Paper 1 needs one more sentence of explanation. The student revises only that paragraph.
Day 7 — submission decision. The student submits, because every included study has a recorded verdict, every caveat is stated in the text, and the excluded study has a documented reason. The paper does not claim more than the evidence supports.
Stop and escalation rules
Set these before you start so deadline pressure cannot quietly override them.
- Stop and exclude when a study fails eligibility on a dimension central to your question — for example, a completely different population or an outcome you cannot use.
- Stop and escalate to your supervisor when two included studies conflict on a dimension you cannot resolve from the full texts, or when your target population is not represented in any retained study.
- Stop and narrow your claim when every retained study carries the same caveat. Rewrite your conclusion to match what the evidence covers.
- Escalate before submission if a caveat appears in your notes but not in the draft. Notes that never reach the text are not part of your argument.
Reporting your selection transparently
PRISMA 2020 provides a reporting checklist, expanded explanations, an abstract checklist, and flow-diagram templates for systematic reviews, including transparent reporting of search, selection, and synthesis methods. Even a course paper benefits from describing how you searched, what you screened, and why you excluded what you did. NIH guidance likewise treats careful assessment of prior knowledge, strengths, weaknesses, and knowledge gaps, along with transparent methods, as core parts of rigorous research practice.
If your work grows into a longer review, Scholar Agent is the WisPaper area for longer research tasks, including literature review use cases. Before you finalize a reference list, TrueCite checks BibTeX against real academic databases to flag hallucinated references.
FAQs
Keep Reading
How to Check Whether Your Literature Review Missed Recent Studies
A literature review can be thorough on the day you run it and incomplete on the day you submit. The practical fix is not to redo the whole search from scratch. It is to define a cutoff, rerun date-bounded searches, track
How to Clean a Messy Reference Library Before Final Writing
A reference library that has grown across drafts, projects, and collaborators usually fails in predictable ways: the same paper appears three times, metadata is inconsistent, attachments point nowhere, and you cannot tel
How to Combine Keywords and Subject Headings in a Search Strategy
A search strategy is the part of a paper you can actually control when the deadline is close. Before you write a single sentence of your literature review, you decide which concepts matter, which words describe them, and