
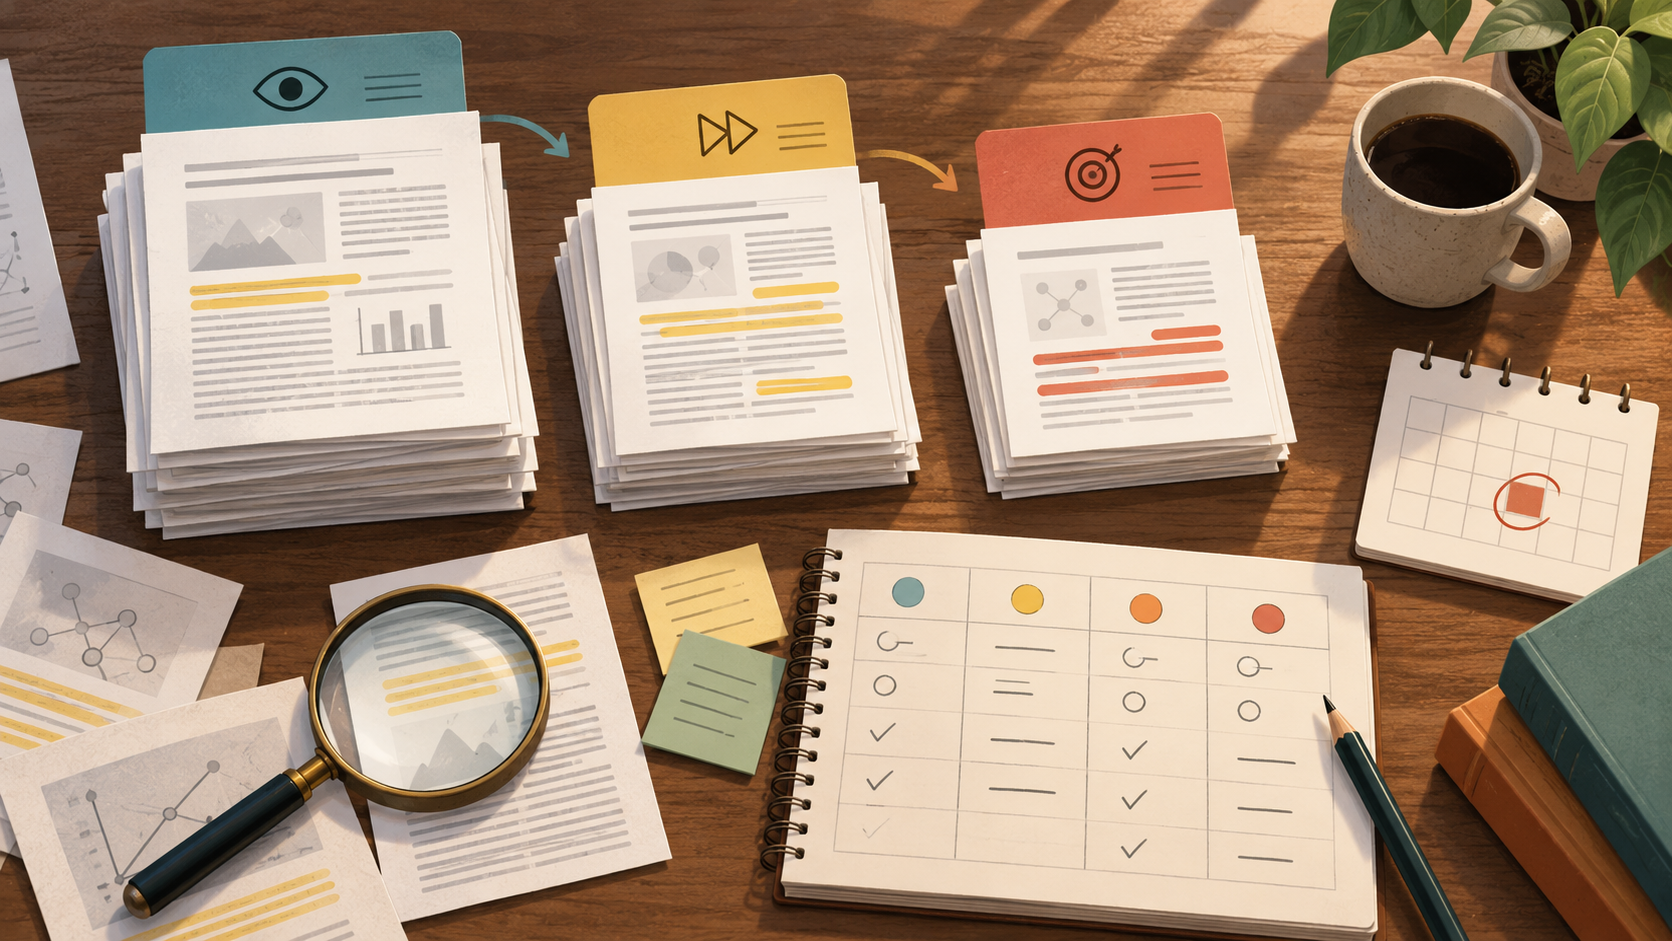
A literature search rarely fails because too few records exist. It fails because the reading queue has no structure. When every record gets the same attention, the papers that actually carry your argument get buried under papers that only share a keyword. The fix is a triage method: score each record on relevance, authority, novelty, and role in the argument, then assign one of three reading modes — abstract-only, targeted, or full reading — and record why.
This guide gives a complete sequence for that triage, with diagnostic checkpoints, a worked example from a manuscript revision, a reusable scoring table, and stop or escalation rules. It also shows where a scholarly search and library workflow fits so the method stays auditable from search string to citation.
Why a reading-mode decision needs a method, not a feeling
Systematic guidance treats study selection as a planned, documented process. The Cochrane Handbook, Chapter 4, recommends planning searches from eligibility criteria, using multiple sources, combining free-text terms with subject headings, documenting the process, deduplicating records, screening in stages, linking multiple reports of one study, and rerunning searches before publication. Those practices exist because selection decisions need to be reproducible and defensible.
A personal reading queue benefits from the same discipline at a smaller scale. If you can say why a paper received abstract-only treatment and another received full reading, you can defend the boundary of your evidence base in a methods section, a response to reviewers, or a grant narrative. If you cannot, you are relying on memory.
The triage method below borrows three ideas from that guidance: screen in stages, document decisions, and link multiple reports of the same study so one study does not inflate your count.
The four scores: relevance, authority, novelty, and role
Score each candidate on four dimensions before deciding how to read it. Keep the scale small — a three-point scale is enough — so scoring stays fast and consistent.
Relevance: does it answer your question?
Relevance asks whether the paper addresses the population, method, outcome, or mechanism your manuscript actually discusses. A paper on a neighboring topic can be highly relevant to a discussion section and irrelevant to a methods justification. Score relevance against a specific question, not against your field in general.
Authority: how much weight can this source carry?
Authority is about the standing of the evidence for your purpose: the venue, the study design, and how directly the reported results support the claim you would attach to them. A conference abstract and a full study may report the same finding, but they carry different weight. Record the version you actually read, because the same work can appear as a preprint, a conference paper, and a journal article.
Novelty: what does it add to what you already hold?
Novelty is relative to your existing library, not to the literature as a whole. A paper is novel for you if it introduces a method, dataset, counterargument, or result you do not already have. Once you hold three papers making the same point, a fourth adds little regardless of its quality.
Role in the argument: where would this appear?
Role is the most useful score and the one most often skipped. Ask which sentence or section of your manuscript this paper would support: background, gap statement, method justification, comparison, limitation, or future work. A paper with no identifiable role does not need deep reading, however interesting it is.
Assign the reading mode from the scores
Once the four scores exist, the mode follows from a simple rule rather than a fresh judgment call.
| Mode | When to assign it | What you extract | Time signal |
|---|---|---|---|
| Abstract-only | Low relevance, or no identifiable role in the argument | A one-line reason for exclusion and the record identifier | Minutes |
| Targeted | Moderate relevance with a clear role, or high relevance but uncertain authority | Specific sections: methods, a results table, a limitations paragraph | Focused pass |
| Full reading | High relevance, adequate authority, and a named role in the argument | Full argument, methods detail, and citation-ready notes | Deep pass |
Two adjustments matter. First, a paper can be high-relevance and still warrant targeted reading if you only need one number from it. Second, a paper with high authority but low novelty for your library may deserve targeted reading to confirm it says what you expect, not a full pass.
A complete triage sequence with diagnostic checkpoints
The sequence below moves from search to reading mode in stages, with a checkpoint after each stage. Each checkpoint is a decision you can record.
Step 1: Fix the question and eligibility criteria before searching
Write the specific question the reading queue must answer, plus the criteria a record must meet to enter the queue. Cochrane's guidance to plan searches from eligibility criteria applies directly here: the criteria come first, and the search is built to serve them.
Checkpoint 1: Can you state, in one sentence, what a paper must address to enter the queue? If not, stop and narrow the question.
Step 2: Run a documented search across more than one source
Use multiple sources and combine free-text terms with subject headings, as Cochrane recommends. Database interfaces support this in concrete ways: PubMed supports field tags, phrase searching, filters, Advanced Search, saved searches, Similar Articles, citation lookup, and links to full text when available, and its search details reveal how terms were translated and combined. Google Scholar documents searching by author and title, date sorting and date limits, Cited by and Related articles, citation export, library access links, email alerts, and ways to locate alternative versions of a work.
Save the exact strings, filters, and dates. That record is the start of your method trail.
Checkpoint 2: Could a colleague rerun your search from what you saved? If not, the trail is incomplete.
Step 3: Deduplicate and link multiple reports of one study
Before scoring, remove duplicate records and group reports that describe the same study. Cochrane recommends deduplicating records and linking multiple reports of one study. This prevents a single study from appearing as several independent sources and inflating its apparent authority.
Checkpoint 3: Does each row in your queue represent a distinct study, or a distinct report? Label it.
Step 4: Screen in stages, scoring only what survives
Screen titles and abstracts first, then score the survivors on the four dimensions. Staged screening keeps scoring effort proportional to promise. This is also where a scholarly search interface helps: you can run the search, then move promising records into a working library rather than scoring from a browser tab list.
Checkpoint 4: Has every record that passed title screening received all four scores? Gaps here become gaps in your evidence boundary.
Step 5: Assign modes and write the reason
Apply the mode table. For every abstract-only decision, write one line explaining why. For every full-reading decision, name the section of your manuscript the paper will support.
Checkpoint 5: Can you sort your queue by mode and see a plausible distribution? A queue where everything is full reading usually means the criteria were too loose.
Step 6: Rerun before you submit
Cochrane recommends rerunning searches before publication. A reading queue built months earlier may miss newer work, and a rerun is cheap once the strings are saved.
Checkpoint 6: Is the rerun date recorded alongside the original search date?
Worked example: triaging a revision's reading queue
Consider a research team revising a manuscript after peer review. A reviewer asks the authors to justify a modeling choice and to address an alternative explanation for their main result. The team needs two things from the literature: methodological support for the choice, and evidence bearing on the alternative explanation.
The team writes two eligibility statements, one per need, and runs searches in two databases, saving strings and dates. After deduplication, 60 records remain. Title screening removes 25 that address neither need. The remaining 35 receive four scores.
- Twelve records score low on relevance to either need. They receive abstract-only mode, each with a one-line exclusion reason.
- Fifteen records are relevant to the modeling choice but only for a single methodological detail. They receive targeted mode, with the specific section to extract noted.
- Six records are highly relevant to the alternative explanation and come from full studies. They receive full reading, each tagged to the discussion section.
- Two records are highly relevant but appear only as conference abstracts. They receive targeted mode until a full report is located, and the team notes the version read.
The team links two reports that describe the same study so it counts once. Before resubmission, they rerun both searches and record the new date. The response letter can now state how many records were screened, how many were read in full, and why — a method trail that answers the reviewer without overstating the evidence.
A reusable scoring and mode checklist
Keep this checklist with the queue so every record is handled the same way.
- Record identifier and source database saved
- Duplicate status confirmed; linked reports grouped
- Relevance scored against a named question
- Authority scored, with version read noted
- Novelty scored against the existing library
- Role in the argument named, or marked as none
- Mode assigned from the table, not from impulse
- One-line reason written for abstract-only decisions
- Target section named for targeted and full-reading decisions
- Search strings, filters, and dates archived
- Rerun scheduled and dated before submission
A queue that passes this checklist is auditable. A reader can trace any citation in your manuscript back to a search, a score, and a mode.
Where a search-and-library workflow fits
Triage works best when search and storage are connected. You can find academic papers through WisPaper's scholarly search interface, then save or upload the records you keep and organize them in My Library. Keeping the queue in one library makes deduplication, linking, and mode assignment easier to review as a set.
When you need to ask questions grounded in the papers you have already collected, Library QA supports asking questions based on papers uploaded to My Library or added from search results. That fits the targeted-reading stage, where you need a specific detail rather than a full pass. For longer literature-review tasks, Scholar Agent covers literature review, inspiration, and reproduction use cases.
If your queue feeds a citation list, TrueCite checks BibTeX against real academic databases to flag hallucinated references — a useful final gate before the reference list is locked. Teams managing the manuscript alongside the reading queue can keep the work in Research Projects.
Stop and escalation rules
Clear rules prevent both under-reading and endless reading.
Stop rules — assign abstract-only and move on when:
- The record addresses neither of your stated needs.
- No section of the manuscript could cite it.
- It duplicates a study already in the queue and adds no new report.
Escalate to targeted reading when:
- Relevance is high but you need only one method, number, or limitation.
- Authority is uncertain and you need to check the study design before relying on it.
- Only an abstract is available; note the version and revisit if a full report appears.
Escalate to full reading when:
- The paper would support a central claim, not a peripheral one.
- It offers a counterargument you must address directly.
- It is the primary report of a study your argument depends on.
Escalate out of the queue entirely when:
- A rerun surfaces a newer report of the same study; replace rather than add.
- A reviewer identifies a gap your criteria missed; revise the criteria, then rerun.
Keeping the method trail auditable
An auditable trail has four parts: the search record, the screening record, the scoring record, and the mode record. Cochrane's emphasis on documenting the process and screening in stages maps onto these parts directly. Store them together, date every change, and keep exclusion reasons even for papers you never read.
The payoff appears at submission. You can describe your evidence base precisely, answer reviewer questions about coverage, and rerun searches without rebuilding the queue. The method also protects against a common failure: treating a large reading list as thoroughness when it is only volume.
FAQs
Keep Reading
How to Document a Literature Search So Someone Else Can Repeat It
A reproducible literature search is one that a colleague—or a reviewer, or you six months from now—can rerun and land on the same record set. The way to get there is a compact reproducibility log: a single file that reco
How to Extract Population, Intervention, Comparison, and Outcomes Reliably
When you are coding a stack of papers against a PICO framework under a deadline, the hard part is rarely remembering what the four letters stand for. It is deciding, for each study, which sentence actually defines the po
How to Fill Evidence Gaps Before a Research Deadline
A deadline does not change what your sources actually say. What it changes is how you spend the remaining hours. The practical move is to stop writing forward for a moment, list every claim that still lacks a source, ran