
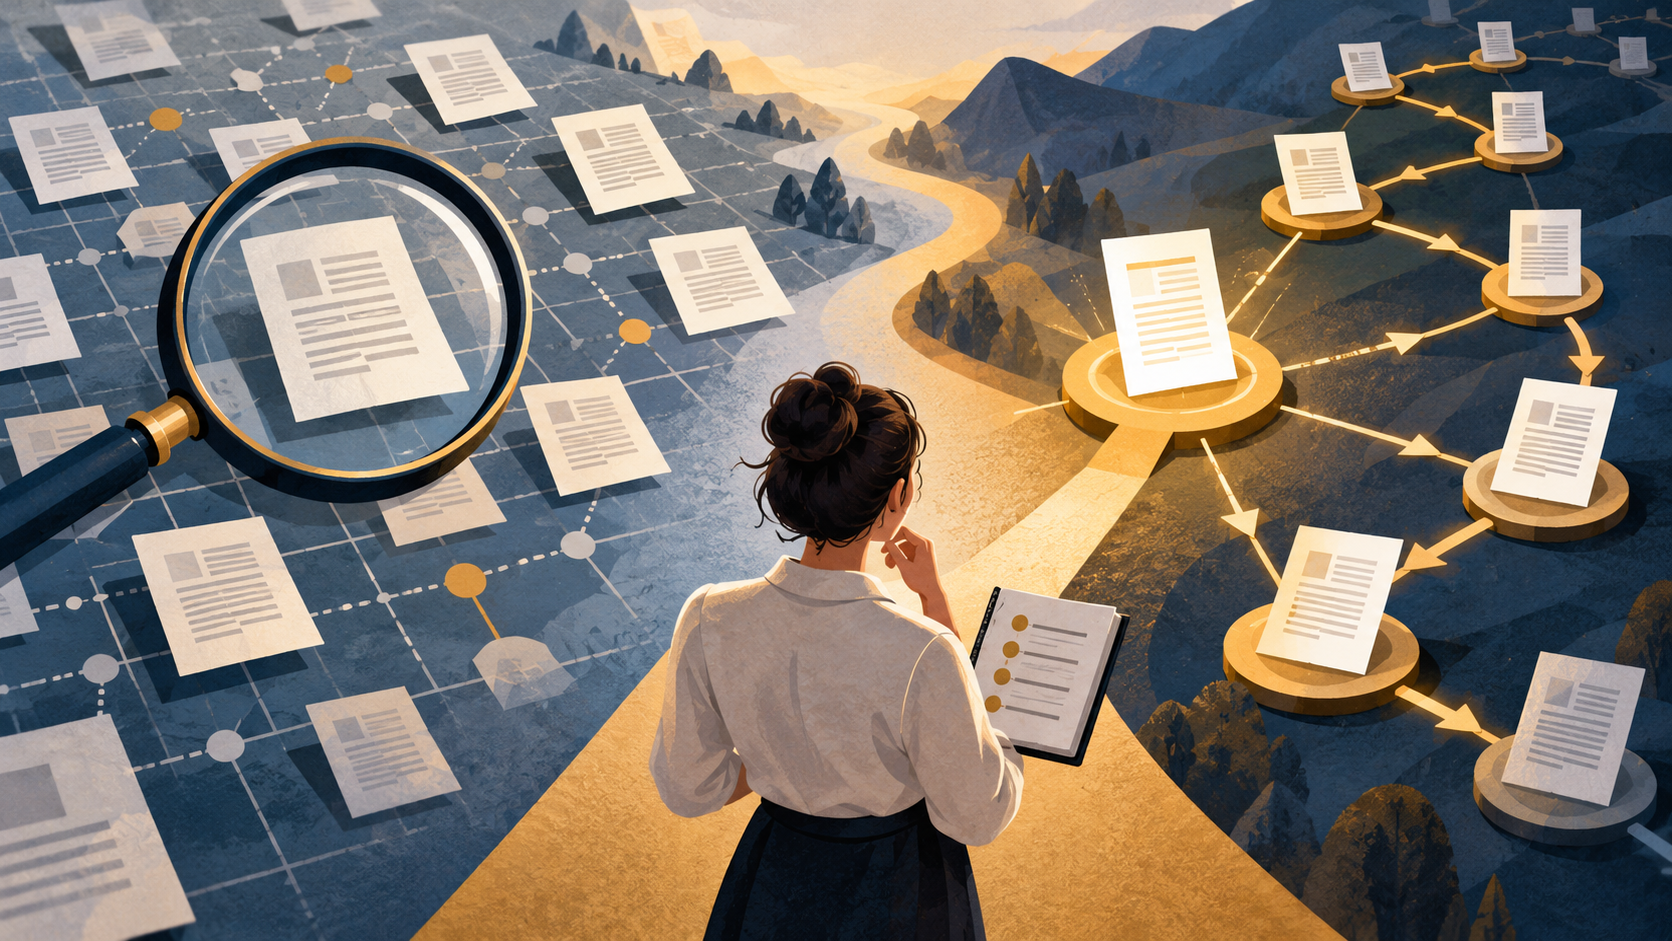
When a manuscript's related-work section has a hole, or a reviewer names a body of literature you have not cited, you face a choice: run more keyword queries, or walk the citation graph outward from a paper you already trust. The two methods fail in different ways, and knowing which failure you are looking at tells you which method to switch to. Keyword search is strongest when you can name the concept but not the paper; citation chaining is strongest when you have one good paper and need its intellectual neighbors. This article compares them on the same task, shows where each breaks down, and gives a decision table plus a combined workflow that leaves an auditable trail.
The same task, two methods
Take a concrete case. You are revising a manuscript and a reviewer writes that you have missed work on a specific mechanism. You have one anchor paper the reviewer implied, plus a rough sense of the concept. Both methods can be pointed at this task, but they answer different questions.
Keyword search asks: which records in an index match these terms? It depends on how well your query vocabulary matches the vocabulary in titles, abstracts, and metadata. Citation chaining asks: what does this known paper cite, and what cites it? It depends on the quality of your anchor and the completeness of the citation links around it.
Because the two rest on different foundations, a failure in one is often a signal to try the other rather than to refine the same query again.
How keyword and concept discovery works, and where it fails
Keyword and concept discovery starts from vocabulary. You translate your research question into terms, then match those terms against indexed metadata. Crossref, for example, exposes publisher-deposited scholarly metadata through its REST API, including titles, authors, venues, dates, identifiers, licenses, funding, ORCID and ROR identifiers, abstracts when deposited, and post-publication updates from trusted sources. That is a rich surface for term matching, but it is only as good as what publishers deposit.
Google Scholar documents searching by author and title, date sorting and date limits, Cited by and Related articles, citation export, library access links, email alerts, and ways to locate alternative versions of a work. Those features show that a general search engine blends term matching with citation signals, which is useful but also means your results depend on how the engine weights those signals.
Where concept discovery fails:
- Vocabulary mismatch. If the field renamed the concept, or the key paper uses different terminology than your query, term matching will not surface it. This is the classic reason a reviewer's missing citation stays missing after several query rewrites.
- Metadata gaps. Abstracts are included in Crossref only when deposited, so a record without an abstract gives term matching less to work with.
- Recall without precision. Broadening terms to catch renamed concepts pulls in adjacent literatures that share words but not claims, and you spend the next hour screening.
When you see these failures, the productive move is usually to stop rewriting the query and find an anchor paper to chain from.
How citation chaining works, and where it fails
Citation chaining starts from a paper you trust and moves along its links: backward to what it cites, forward to what cites it. Google Scholar's Cited by and Related articles features are documented entry points for this kind of movement, and its support for locating alternative versions helps when the version you have is incomplete.
Where citation chaining fails:
- A weak or atypical anchor. If your anchor is a narrow methods paper, its citation neighborhood may be narrow too, and you will miss the broader literature that never cites it.
- Link incompleteness. Chaining can only traverse links that exist in the index you are using. A paper that is poorly linked, or a venue whose citations are not captured, will not appear no matter how good your anchor is.
- Drift. Forward chaining from a highly cited paper can return hundreds of citing works with little relevance to your specific claim, and you need a screening rule before you start.
- Identity confusion. A DOI resolves through doi.org to the current destination registered for that identifier, which helps you locate a work, but bibliographic fields and the source text still need to be checked for identity and claim support. Chaining multiplies the number of records you touch, so identity checks matter more, not less.
When chaining stalls, the signal is usually that you need vocabulary again: a term to search, or a concept to name so you can find a better anchor.
Comparing the two on shared criteria
| Criterion | Keyword / concept discovery | Citation chaining |
|---|---|---|
| Starting point | A concept you can name | A paper you trust |
| Depends on | Query vocabulary matching indexed metadata | Quality of anchor and completeness of citation links |
| Typical failure | Vocabulary mismatch, metadata gaps | Weak anchor, incomplete links, drift |
| Best for | Entering an unfamiliar area; finding renamed concepts once you have the new term | Expanding from a known core paper; finding predecessors and successors |
| Screening load | High when queries are broad | High when the anchor is highly cited |
| Identity checks | Per record | Per record, multiplied by link count |
Neither column is universally better. The table is a routing tool: match your current situation to the row that describes it, and switch when the failure mode in your column appears.
A decision table for switching methods
Use this to decide your next action rather than to rank the methods.
| What you observe | Likely cause | Switch to |
|---|---|---|
| Several query rewrites return the same papers | Vocabulary mismatch | Citation chaining from your best current paper |
| A record has no abstract and weak metadata | Metadata gap | Chaining, or a targeted author/title search |
| Forward chaining returns too many citing works | Drift from a highly cited anchor | Keyword search to name the sub-concept, then chain from a narrower anchor |
| Chaining from your anchor misses an obvious neighbor | Weak or atypical anchor | Keyword search to find a better anchor |
| You cannot tell whether two records are the same work | Identity ambiguity | Resolve the DOI and check bibliographic fields |
| You have a concept but no paper | Cold start | Keyword search first |
Two rules keep this practical. First, treat a repeated failure as information about the method, not about your diligence. Second, record which method produced each candidate paper, because that record is what makes the search auditable later.
A combined workflow for a revision
Here is a workflow that uses both methods in sequence and preserves a trail. It assumes the reviewer-missing-citation scenario from the opening.
- Name the concept and run a first keyword pass. Use author and title searching plus date limits where you need recency, as documented in Google Scholar's search help. Record your exact queries and the date you ran them.
- Pick an anchor from the results. Choose the paper that most directly addresses the reviewer's point, not the most cited one.
- Chain backward and forward from the anchor. Use Cited by and Related articles to move outward. Record the anchor and the direction of each hop.
- Screen with a written rule. Before chaining, decide what counts as relevant to the specific claim. This controls drift.
- Resolve and verify identities. For each candidate you keep, resolve the DOI and check the bibliographic fields and the source text for identity and claim support.
- Switch when a failure appears. If chaining stalls, return to keyword search with vocabulary you learned from the anchor's neighborhood. If keyword search stalls, find a new anchor.
- Log the trail. For each included paper, note the method, the query or anchor, and the date. This is the auditable method trail a co-author or reviewer can follow.
For the search steps themselves, you can run queries in WisPaper search and keep the papers you decide to retain in My Library, so the candidates from both methods sit in one place while you screen. If your revision grows into a longer literature review, Scholar Agent is the area for longer research tasks that fit literature review, inspiration, or reproduction use cases.
Keeping the method trail auditable
An auditable trail has three properties: it names the method, it names the input, and it is dated. For keyword search, the input is the query string. For chaining, the input is the anchor paper and the direction. For both, the output is the candidate list with a keep/drop decision.
A simple log table works:
| Date | Method | Input | Candidates kept | Decision note |
|---|---|---|---|---|
| Day 1 | Keyword | "query string" | 3 | Two relevant, one adjacent |
| Day 1 | Chaining (backward) | Anchor DOI | 5 | Three relevant |
| Day 2 | Chaining (forward) | Anchor DOI | 12 | Screened to 2 by rule |
This table does two things. It lets a co-author reproduce your search, and it shows a reviewer that the missing citation was searched for systematically rather than guessed at. When you are ready to check that your reference list itself is sound, TrueCite checks BibTeX against real academic databases to flag hallucinated references, which complements the trail by catching entries that never should have been in the list.
If your team is coordinating the revision across several people, Research Projects is the area for creating and running a shared project, which keeps the trail with the work rather than in one person's notes.
When to switch, in one paragraph
Switch from keyword search to chaining when repeated query rewrites return the same set, when metadata is too thin to match on, or when you have found one paper you trust and want its neighbors. Switch from chaining to keyword search when your anchor is atypical, when forward chaining drifts into irrelevant citing works, or when you need to name a sub-concept before you can find a narrower anchor. In both directions, the trigger is a specific observed failure, not a general preference.
FAQs
Keep Reading
Literature Review Evidence Management: From Search Results to Synthesis
A literature review is not a pile of PDFs. It is a chain of decisions: what to search, what to keep, what to read first, what to extract, how to compare studies, and how to turn those comparisons into an argument. When t
Manual Screening vs. AI Prioritization: How Should You Divide the Work?
Divide the work by what each side can actually be held to. Judgment, eligibility decisions, and the final record belong to the reviewer; speed, first-pass ordering, and recall support are where AI prioritization earns it
Medical Evidence Search: From PICO to Applicable Studies
A focused clinical question rarely fails because there are no papers. It fails because the search, the study designs, and the patient in front of you drift apart. This guide connects those pieces: turning a question into