
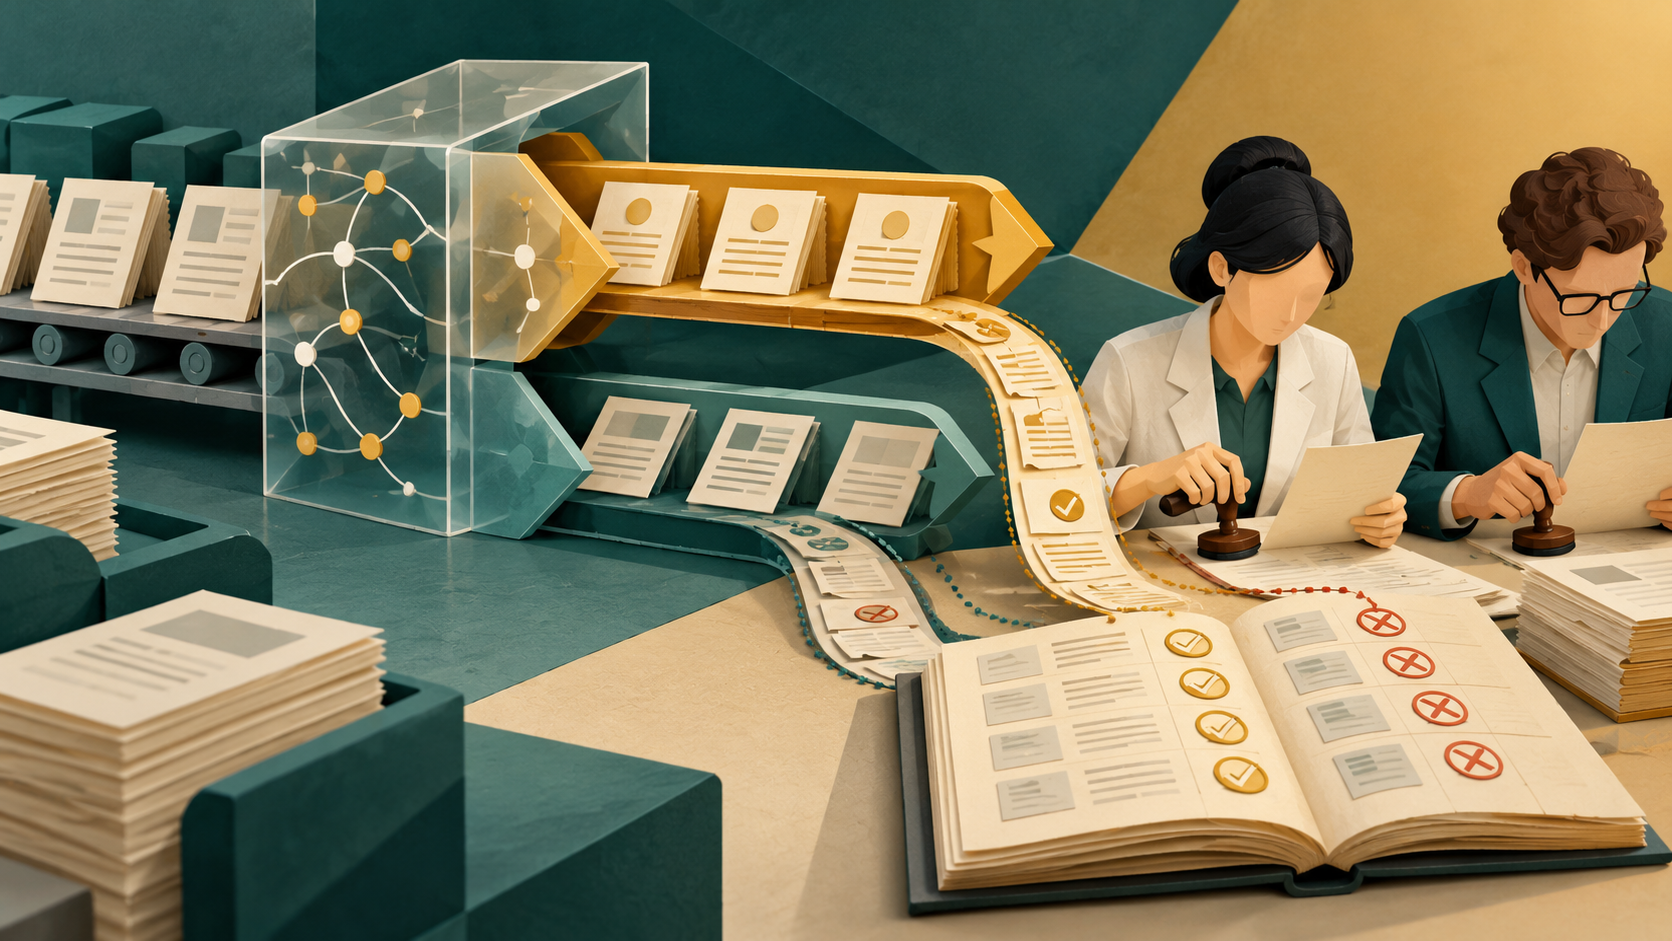
Divide the work by what each side can actually be held to. Judgment, eligibility decisions, and the final record belong to the reviewer; speed, first-pass ordering, and recall support are where AI prioritization earns its place. The practical answer is not "manual or AI" but a staged workflow: define criteria, let AI help order and surface records, then have humans make and document every inclusion decision. This article compares the two approaches on the same task — screening a literature set for a manuscript, review, or grant evidence summary — using judgment, speed, calibration, recall risk, and audit trails as the criteria, then gives a decision table and a combined workflow.
Why the comparison only works on a shared task
To compare fairly, fix the task. Take a concrete example: a research team is preparing a systematic review and must screen a deduplicated set of records against pre-specified eligibility criteria, then document how the final set was reached. Cochrane's guidance for searching and selecting studies recommends planning searches from eligibility criteria, using multiple sources, combining free-text terms with subject headings, documenting the process, deduplicating records, screening in stages, linking multiple reports of one study, and rerunning searches before publication. PRISMA 2020 supplies a reporting checklist, expanded explanations, an abstract checklist, and flow-diagram templates for original and updated systematic reviews, including transparent reporting of search, selection, and synthesis methods.
That shared task has two very different sub-tasks. One is ordering and surfacing — deciding which records a human should look at first. The other is deciding and recording — judging whether a record meets the criteria and writing that decision into an auditable trail. Manual screening and AI prioritization perform differently on each, and most bad workflows come from letting one approach do the other's job.
Criterion 1: Judgment and eligibility decisions
Eligibility judgment is where manual review is strongest and where AI prioritization is weakest as a decision-maker. Eligibility criteria are interpretive: a record may report one study across multiple reports, or a study may sit at the edge of a population definition. Cochrane explicitly recommends linking multiple reports of one study, which is a judgment about identity, not a keyword match. PRISMA's selection reporting assumes a documented decision process behind the flow diagram.
AI prioritization is better framed as a ranking aid: it helps decide what to read first, not what to include. When you write your methods, the sentence you need to be able to defend is "reviewers assessed each record against the criteria," not "the tool decided." Keep the decision with the reviewer and let the tool change the order of the queue.
Criterion 2: Speed and throughput
Manual screening is slow in a predictable way: every record costs reading time, and the cost scales with the size of the deduplicated set. AI prioritization changes the shape of that cost. Instead of reading everything at equal depth, reviewers read the highest-priority records first and can reach saturation on clear exclusions sooner.
The speed gain is real but conditional. It depends on the quality of your criteria and on whether the ranking is aligned with them. If your eligibility criteria are vague, a faster queue just moves you faster toward inconsistent decisions. Cochrane's advice to plan searches from eligibility criteria applies with equal force to prioritization: the criteria are the input that makes any ordering meaningful.
Criterion 3: Calibration and consistency
Calibration is the degree to which your screening decisions match your stated criteria across reviewers and across time. Manual screening calibrates through explicit criteria, pilot rounds, and discussion of disagreements. That is a human process, and it is the part you should protect.
AI prioritization calibrates differently: it reflects whatever signal it was given, so its ordering is only as good as the criteria and examples behind it. The practical move is to calibrate the human decision rule first — run a small pilot, resolve disagreements, and write down the rule — and only then apply prioritization to the full set. That way the ranking serves a stable rule rather than substituting for one.
Criterion 4: Recall risk
Recall risk is the chance that a relevant record never reaches a reviewer's eyes. This is the criterion where the two approaches diverge most sharply, and where the workflow design matters most.
Manual screening has a different recall problem: it is thorough per record but vulnerable to reviewer fatigue and inconsistent application late in a long queue. AI prioritization has the opposite profile: it can surface relevant material quickly, but anything ranked low may be read late or not at all. Neither approach eliminates recall risk on its own.
The mitigation is structural. Cochrane recommends screening in stages and rerunning searches before publication; both practices create checkpoints where missed records can re-enter the process. Pair prioritization with a documented lower-priority pass so that low-ranked records are still reviewed, and record that pass in your methods. PRISMA's transparent reporting of selection methods gives you the place to describe it.
Criterion 5: Audit trails and reproducibility
An audit trail is what lets a reader reconstruct how you got from a search to a final set. Cochrane's documentation and deduplication steps and PRISMA's flow-diagram templates both assume that the trail exists. NIH's rigor and reproducibility guidance treats careful assessment of prior knowledge, strengths, weaknesses, knowledge gaps, transparent methods, validation, and reproducibility as core parts of rigorous research practice — which is the standard your screening record should meet.
Manual screening produces an audit trail naturally if you write decisions down as you go: criteria, dates, reviewer, decision, reason. AI prioritization adds a step to the trail — you must record that prioritization was used, on what basis, and how lower-ranked records were handled. If that step is missing, the trail has a gap that a reviewer or grant panel can legitimately ask about. Build the trail first, then add prioritization inside it.
Where each approach fails
Manual screening fails when the set is large and the criteria are underspecified: reviewers drift, late-queue records get shallow treatment, and the decision log becomes inconsistent. It also fails when documentation is treated as an afterthought, leaving a flow diagram that cannot be reconstructed.
AI prioritization fails when it is asked to make eligibility decisions, when criteria are vague, and when low-ranked records are never reviewed. It also fails as an audit trail if the prioritization step is not recorded. In both cases the failure is a workflow failure, not a tool failure: the fix is to assign each sub-task to the side that can be held to it.
Decision table
| Criterion | Manual screening | AI prioritization | Best division of work |
|---|---|---|---|
| Judgment / eligibility | Strong: reviewer interprets criteria and links multiple reports of one study | Weak as decision-maker; better as ordering aid | Reviewer decides; tool orders the queue |
| Speed | Slow, scales with set size | Faster first pass on high-priority records | Prioritize, then review in ranked order |
| Calibration | Via criteria, pilot rounds, disagreement resolution | Reflects the criteria and examples it is given | Calibrate the human rule first, then apply ranking |
| Recall risk | Thorough per record; fatigue risk late in queue | Low-ranked records may be read late or not at all | Add a documented lower-priority pass and rerun searches |
| Audit trail | Natural if decisions are written as you go | Adds a step that must be recorded | Record criteria, ranking basis, and lower-priority pass |
A combined workflow for a manuscript or review
The workflow below keeps the auditable method trail intact and uses AI only where it genuinely helps.
- Write eligibility criteria and a search plan. Follow Cochrane's advice to plan searches from eligibility criteria, use multiple sources, and combine free-text terms with subject headings. Record the plan before searching.
- Run and document the search. Use a scholarly search interface to find candidate papers, and keep the query, sources, and date in your methods file. WisPaper's scholarly search interface is one place to run that search; the public Scholar Search entry point explains the same capability for readers new to the tool.
- Deduplicate and stage. Cochrane recommends deduplicating records and screening in stages. Save the deduplicated set as your working corpus.
- Prioritize, then review. Use AI to order the queue, then have reviewers assess each record against the criteria. Record the ranking basis and the reviewer's decision separately.
- Run a documented lower-priority pass. Review low-ranked records so recall risk is addressed in the record, not just in intent.
- Link multiple reports of one study. Apply Cochrane's linking step before synthesis so the final count reflects studies, not reports.
- Rerun searches before publication. Cochrane recommends rerunning searches before publication; log the rerun and any new records.
- Report with PRISMA. Use PRISMA 2020's checklist and flow-diagram templates to report search, selection, and synthesis methods transparently.
Where WisPaper fits at specific steps
WisPaper is an AI research assistant for finding, screening, organizing, and working with academic papers, as described on its English homepage. Within the workflow above, use it at specific steps and write each resulting inclusion decision into the decision record.
- Organizing the working corpus. Save or upload papers and organize them in My Library so the deduplicated set and the included set stay distinct.
- Asking questions of the included set. Once papers are in My Library or added from search results, Library QA lets you ask questions based on those papers — useful when drafting the synthesis section, with the answers checked against the source papers.
- Longer literature-review tasks. For extended review work, Scholar Agent covers literature review, inspiration, and reproduction use cases.
- Citation screening. Before submission, TrueCite checks BibTeX against real academic databases to flag hallucinated references — a concrete audit step for the reference list.
Each of these supports a step in the trail; none of them writes the eligibility decision for you.
FAQs
Keep Reading
Medical Evidence Search: From PICO to Applicable Studies
A focused clinical question rarely fails because there are no papers. It fails because the search, the study designs, and the patient in front of you drift apart. This guide connects those pieces: turning a question into
One Database vs. Multiple Databases for a Literature Review
If you are choosing between one database and several for a literature review, the practical answer is: start with one database to build your search vocabulary and eligibility criteria, then add sources until new searches
Preprint vs. Published Article: Which Version Should You Cite?
Cite the version you actually read, and cite the published version of record when it exists and you have access to it. If you relied on a preprint and a peer-reviewed version has since appeared, cite the published versio