
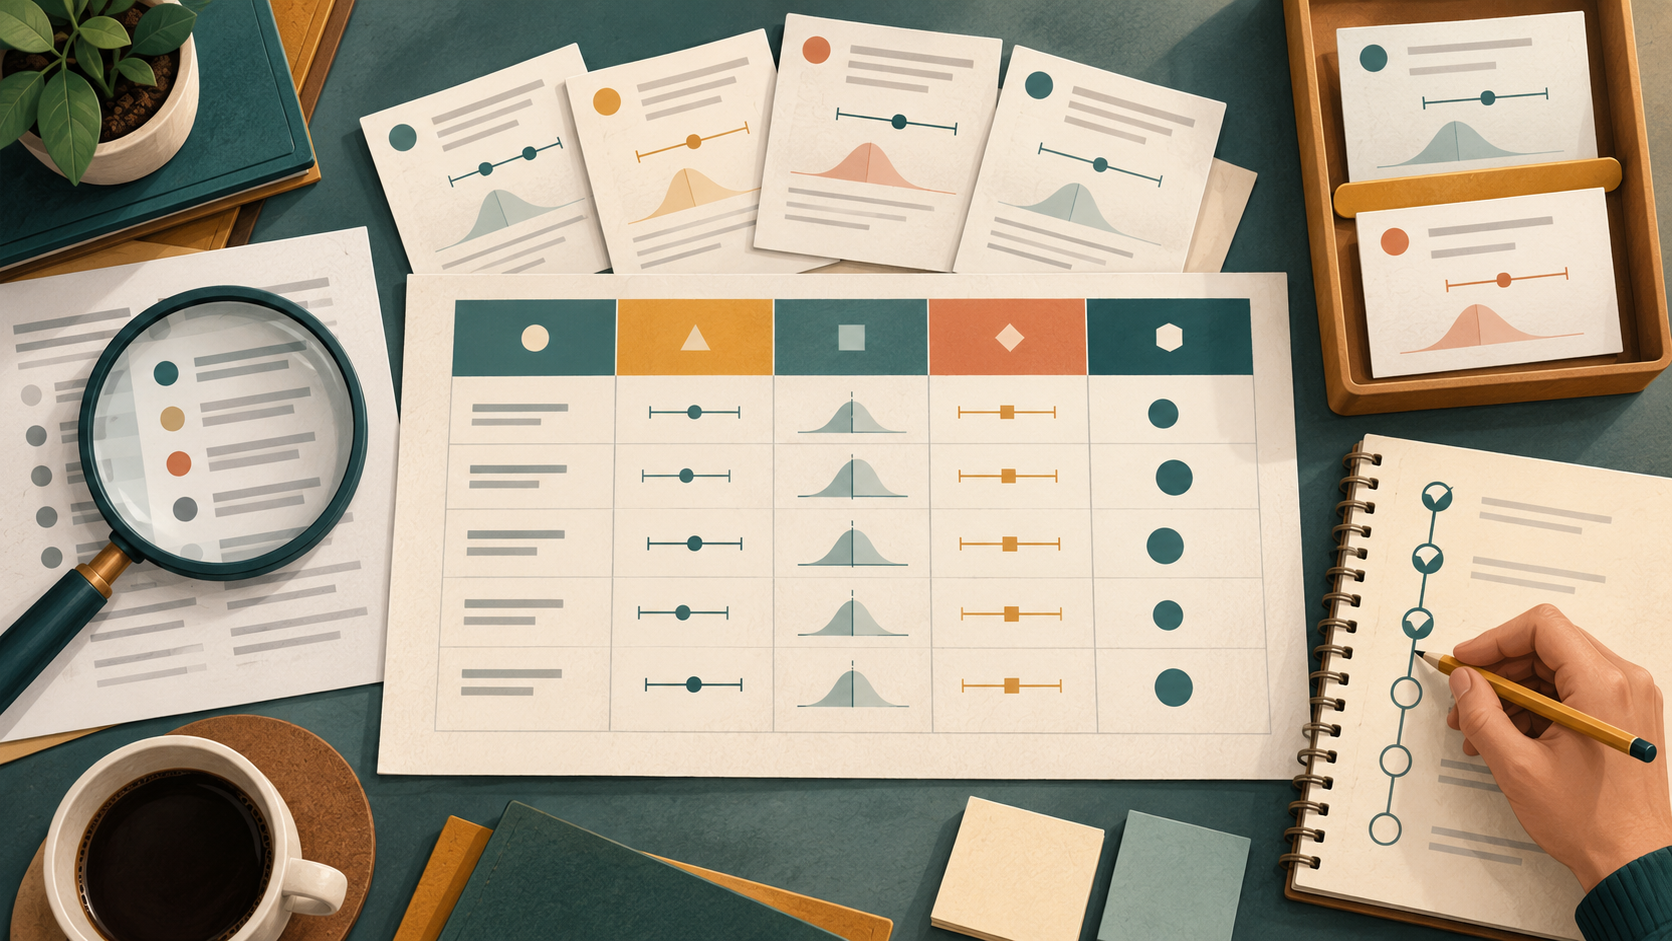
Comparing effect sizes is not a sorting exercise. Two studies can report the same standardized number while measuring different constructs, pointing in different directions, following participants for different lengths of time, and resting on very different levels of uncertainty. Flattening those differences produces a tidy table and a misleading conclusion.
The practical answer is to capture five attributes for every result before you compare anything: measure type, direction, uncertainty, follow-up, and scale. Then compare only the results that remain sufficiently compatible on those attributes, and record why each excluded result was set aside. This article gives a complete sequence with diagnostic checkpoints, a worked example, a reusable checklist, and stop rules for when a comparison should not proceed.
Why the same number can mean different things
An effect size is a claim embedded in a design. The number alone does not tell you what was measured, whether higher values are better or worse, how precise the estimate is, when it was measured, or what range the instrument can express. When you pool or rank results without those attributes, you are comparing labels rather than findings.
This matters most in manuscript writing, peer review, and evidence summaries for grants, where a single sentence such as "effects were consistently positive across studies" can travel far beyond the evidence behind it. The discipline is to keep the attributes attached to each result all the way from screening to the sentence you write.
Step 1: Fix eligibility before you search
Start from explicit eligibility criteria and plan the search from them. Cochrane's guidance on searching and selecting studies recommends planning searches from eligibility criteria, using multiple sources, combining free-text terms with subject headings, documenting the process, deduplicating records, screening in stages, linking multiple reports of one study, and rerunning searches before publication.
For an effect-size comparison, eligibility criteria should already name the outcome construct, the population, the comparison, and the time window you will accept. If you leave the time window open, you will later be forced to compare a six-week result with a two-year result as if they were the same finding.
Checkpoint: Can you state, in one sentence, which outcome and which follow-up window you will accept? If not, the comparison is not yet defined.
Step 2: Run a documented, reproducible search
A reproducible search is part of the method trail, not an afterthought. PubMed supports field tags, phrase searching, filters, Advanced Search, saved searches, Similar Articles, citation lookup, and links to full text when available, and its search details reveal how terms were translated and combined. That translation view is useful when you need to show a co-author or reviewer exactly how a query was built.
Google Scholar documents searching by author and title, date sorting and date limits, Cited by and Related articles, citation export, library access links, email alerts, and ways to locate alternative versions of a work. Those features help you extend a seed set and find versions, but the query itself still needs to be recorded.
When you need to find academic papers through a scholarly search interface, WisPaper search is the place to run that step. Keep a dated log of each query, the source, the filters applied, and the number of records returned.
Checkpoint: Could a colleague rerun your search from your log and reach the same record set? If not, fix the log before screening.
Step 3: Link reports to studies before extracting numbers
Multiple reports can describe one study. Cochrane's guidance explicitly includes linking multiple reports of one study, and screening in stages. Do this before extraction, because two reports of the same trial are not two independent effect sizes.
Build a study-level identifier and attach every report to it. Note which report supplies the effect size, which supplies the follow-up timing, and which supplies the scale description.
Checkpoint: Does every extracted effect size trace to exactly one study identifier and one report? If a number appears in two reports, decide which is primary and record the decision.
Step 4: Capture the five attributes for every result
This is the core of the method. For each result, record the following before you look at any cross-study comparison.
Measure type
Record what the effect size expresses: a standardized mean difference, a correlation, a risk or odds ratio, a proportion, or another metric. Also record the construct measured and the instrument used. Two standardized mean differences on different instruments are not automatically interchangeable.
Direction
Record whether higher values indicate benefit, harm, or neither, and which group is the comparator. Direction errors are the most common source of a reversed conclusion, and they are invisible once results are reduced to a column of numbers.
Uncertainty
Record the confidence interval or equivalent interval alongside the point estimate, and the sample size behind it. A point estimate without its interval invites overconfident ranking.
Follow-up
Record the time point at which the outcome was measured and the total observation period. Note whether the time point was prespecified or selected after the fact.
Scale
Record the range, units, and meaningful anchors of the instrument, including whether a higher score is better. Scale information is what lets a reader interpret magnitude rather than merely order results.
Checkpoint: Are all five attributes populated for every result? Any blank cell is a reason to return to the source, not to guess.
Step 5: Define compatibility rules before comparing
Write down, in advance, what counts as sufficiently compatible. A defensible rule set addresses the construct, the direction convention, the metric family, the follow-up window, and the scale interpretation. Results that fail a rule are not deleted; they are moved to a separate table with the reason recorded.
This is where most flattening happens: a reviewer or co-author asks for one summary table, and incompatible results get merged to satisfy the format. Keep two tables instead — one for comparable results and one for results excluded from comparison with reasons.
Checkpoint: Can you name the specific rule that excluded each result? If the reason is "it looked different," the rule set is not yet explicit.
Step 6: Compare only within compatible groups
Within a compatible group, compare point estimates alongside their uncertainty and follow-up. Describe the pattern in terms of overlap and range rather than a single pooled number, unless your method and data justify pooling. Where directions conflict within a group, report the conflict rather than averaging it away.
When you need to ask questions based on papers uploaded to My Library or added from search results, Library QA supports that step, which is useful for checking how a specific paper describes its instrument or time point before you finalize an attribute.
Checkpoint: Does every comparative sentence in your draft point to a compatible group and to the attributes that define it?
Worked example: a manuscript revision
Suppose your team is revising a manuscript on a behavioral intervention and a reviewer asks you to "compare effect sizes across the included studies." Your extraction table has nine results from seven studies.
You apply the five attributes. Four results share a construct, a direction convention, a metric family, a six-month follow-up window, and a scale with the same anchors. Three results use the same metric but measure at twelve weeks, outside your stated window. One result uses a different instrument with a different range. One result reports direction opposite to the others because the comparator was reversed.
Your revision does three things. First, it compares the four compatible results, reporting each point estimate with its interval and noting the shared follow-up. Second, it presents the three short-follow-up results separately with the window stated. Third, it corrects the reversed result and explains the comparator in a footnote. The response letter states the compatibility rules and points to the two tables.
To keep the papers and the extraction trail together, My Library lets you save or upload papers and organize them in the WisPaper library, so the study-level grouping stays attached to the sources.
A reusable extraction and comparison checklist
| Field | What to record | Why it blocks flattening |
|---|---|---|
| Study ID | One identifier per study, with linked reports | Prevents double-counting one study |
| Measure type | Metric, construct, instrument | Stops unlike metrics being merged |
| Direction | Sign convention and comparator | Catches reversed conclusions |
| Uncertainty | Interval and sample size | Keeps ranking honest |
| Follow-up | Time point and observation period | Separates short- and long-term findings |
| Scale | Range, units, anchors | Preserves magnitude interpretation |
| Compatibility rule | Rule applied and pass/fail | Makes exclusion auditable |
| Exclusion reason | Specific rule that failed | Keeps the method trail intact |
Use the same table for extraction and for the comparison stage so that no attribute is lost in transfer.
Stop and escalation rules
Stop the comparison and escalate to the team when any of the following occurs.
- Direction is unresolved. If you cannot determine the sign convention or the comparator for a result, do not place it in a comparative table.
- The construct differs. If two results measure different constructs, they belong in separate groups regardless of metric similarity.
- Follow-up windows do not overlap. If your stated window excludes a result, report it separately rather than stretching the window after seeing the data.
- Uncertainty is missing. If no interval or sample size can be recovered, describe the result as reported and keep it out of ranking statements.
- A rule was changed mid-analysis. If compatibility rules change after extraction, document the change, the reason, and which results were reclassified.
Escalate to a co-author or methodologist when a result sits on a boundary — for example, a follow-up one week outside the window, or an instrument with a similar but not identical range. Boundary decisions should be made once, recorded, and applied consistently.
Keeping the method trail auditable
An auditable trail has four parts: the dated search log, the study-level linking record, the extraction table with all five attributes, and the compatibility rule set with exclusion reasons. Each part should be versioned and stored with the manuscript materials.
For longer research tasks that fit WisPaper's Scholar Agent area and its literature review, inspiration, or reproduction use cases, Scholar Agent is the relevant workspace. If your comparison feeds a larger manuscript effort, Research Projects is where the WisPaper Research Projects area lives and where a new project can be created.
Before submission, rerun the searches as Cochrane's guidance recommends, and check whether any new report changes a study-level grouping or an extracted attribute. If it does, update the tables and note the change in the response or methods section.
FAQs
Keep Reading
How to Decide Whether a Source Is Strong Enough for a Specific Claim
A source is strong enough for a claim when three things line up: the source type and study design can support the kind of statement you are making, the source addresses the same population, intervention, and outcome as y
How to Decide Which Papers to Skim and Which to Read Deeply
A literature search rarely fails because too few records exist. It fails because the reading queue has no structure. When every record gets the same attention, the papers that actually carry your argument get buried unde
How to Document a Literature Search So Someone Else Can Repeat It
A reproducible literature search is one that a colleague—or a reviewer, or you six months from now—can rerun and land on the same record set. The way to get there is a compact reproducibility log: a single file that reco