
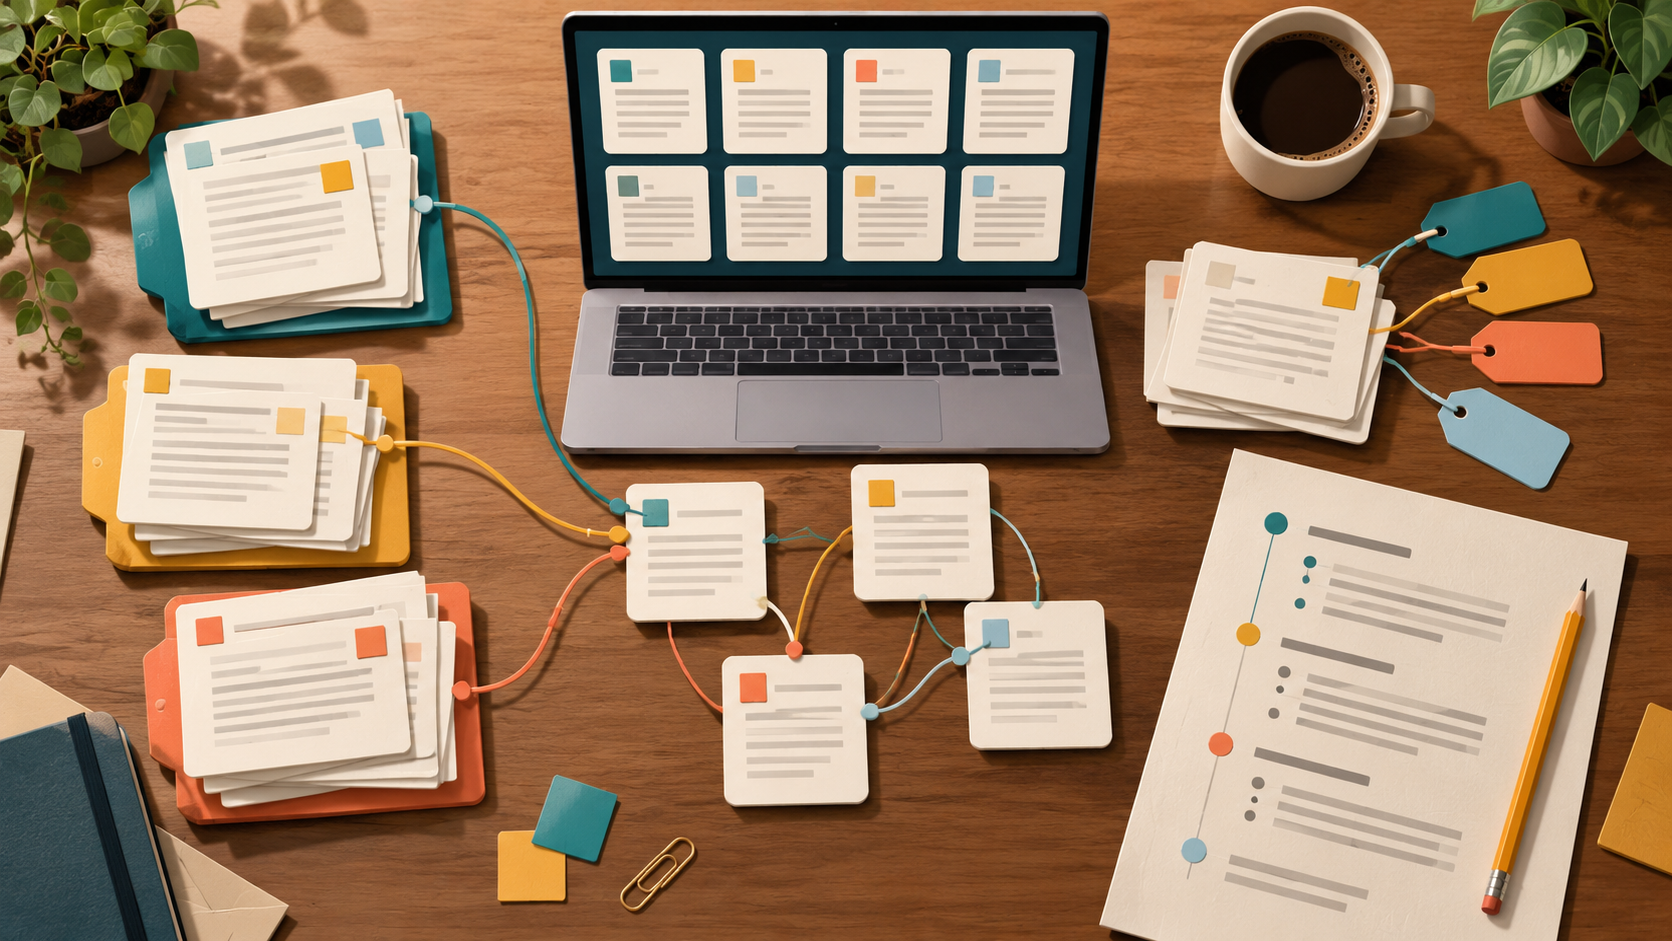
A literature review under a deadline fails in a predictable way: not because you cannot find papers, but because you cannot tell, at a glance, which papers belong to which argument, which ones you have actually read, and which ones your supervisor asked you to add. Zotero gives you several ways to answer those questions — collections, tags, saved searches, and a hybrid of all three — and they are not interchangeable. This article compares them on the same task, shows where each one breaks down, and ends with a concrete decision for a student finishing a course paper or first manuscript.
The shared task: one review, several jobs
To compare fairly, fix the task. Imagine a student writing a 6,000-word review with a rubric that rewards a clear thematic structure, critical synthesis, and correct citation. The library has to do five jobs at once:
- Group papers by argument so each section of the draft has a matching set of sources.
- Mark cross-cutting attributes — method, population, or study type — that cut across sections.
- Track reading and writing status so unread papers do not silently end up in the draft.
- Surface subsets on demand — for example, everything still unread in one theme.
- Absorb supervisor feedback without rebuilding the whole library.
Every option below is judged against those five jobs. The point is not that one is "best"; it is that each one is strong on some jobs and weak on others.
Option 1: Collections as project groupings
Zotero collections are the closest thing to folders, with one important difference: a single item can sit in multiple collections without being duplicated. That matters for a literature review, because the same paper often supports two arguments. A study on remote work and burnout can live in both a "Wellbeing" collection and a "Policy implications" collection, and it remains one record with one set of notes and one citation entry.
Where collections win: they map cleanly onto the sections of your draft. If your outline has four themes, four collections give you a visible, stable structure that a supervisor can follow. Because items are not duplicated, reorganizing a theme does not create orphaned copies.
Where collections fail: they are a single hierarchy. The moment you need to ask "show me every qualitative study, regardless of theme," collections cannot answer without you creating a parallel set of collections that duplicates the logic. They also say nothing about whether you have read a paper. A collection is a location, not a status.
Option 2: Tags as cross-cutting labels
Tags are free-form labels attached to items, and Zotero's own documentation notes they can describe topic, method, status, or workflow. That flexibility is the strength: one paper can carry qualitative, unread, and supervisor-suggested at the same time, and each label is independent of where the paper is filed.
Where tags win: they handle the cross-cutting job that collections cannot. Method, study type, and workflow status are naturally multi-valued, and tags express that without forcing a hierarchy. Filtering by a tag across the whole library is fast.
Where tags fail: they drift. Without a naming convention, qualitative, Qualitative, and qual become three tags, and the filter you relied on last week quietly stops working. Tags also have no inherent order, so they cannot represent "section 2 comes before section 3." And a tag like unread is only useful if you actually remove it when you finish reading — a discipline problem that tags expose rather than solve.
Option 3: Workflow status as its own signal
Status is the job most often neglected. A paper can be found, saved, skimmed, read, and cited, and those are different states. Zotero's tag system can carry status labels, which is the simplest approach: a small controlled set such as to-read, read, and cited.
The failure mode is over-tagging. If you invent ten status labels, you will spend more time maintaining them than writing. Keep status to a short, fixed vocabulary and treat it as a separate namespace from topic tags — for example, prefix status tags so they sort together and are easy to scan.
Option 4: Saved searches as live views
Saved searches are the feature that turns a static library into a working dashboard. Zotero saved searches update automatically, so a search defined once keeps returning current results as you add and tag items. That is exactly what a deadline workflow needs: a view that answers "what is still unread in this theme?" without you rebuilding a filter each morning.
Where saved searches win: they combine conditions. A saved search can match a collection and a tag together, which is the hybrid logic described below. They also cost nothing to maintain once defined.
Where saved searches fail: they are only as good as the metadata underneath them. If tags are inconsistent, the saved search inherits the inconsistency. And a saved search is a view, not a place — you cannot drag a paper "into" it, so it should never be your only organizing structure.
Where each option breaks under deadline pressure
The comparison is clearest when you imagine the week before submission.
- Collections alone leave you unable to answer cross-cutting questions, so you re-scan the whole library to find unread methods papers.
- Tags alone leave you without a stable outline, so the draft's structure and the library's structure drift apart.
- Status labels alone tell you what is read but not what it is for.
- Saved searches alone give you views but no home for new items, so every import needs a manual decision.
None of these is a reason to abandon the feature. Each is a reason to assign it the job it does well.
A practical hybrid structure
A workable structure for a deadline review uses all four layers, each with a narrow job:
- Collections = draft sections. Create one collection per theme in your outline, plus a
Inboxcollection for new imports. File each paper into the theme it supports; allow it in two collections when it genuinely supports two arguments. - Tags = cross-cutting attributes. Use a small controlled vocabulary for method and study type, and a separate prefixed set for status. Write the vocabulary down before you import anything.
- Saved searches = live views. Build one saved search per question you ask repeatedly — for example, unread items within a theme, or supervisor-suggested items not yet read.
- Duplicates = a review step. Zotero's Duplicate Items collection supports reviewing and merging duplicate records, which matters when the same paper arrives from two databases.
This division of labor means each feature is doing the job it is actually good at, and no single feature is overloaded.
Building the library: search, screen, and file
Before any of this structure matters, you need papers. Start with a search plan derived from your eligibility criteria rather than from whatever the first search box returns. The Cochrane Handbook recommends planning searches from eligibility criteria, using multiple sources, combining free-text terms with subject headings, documenting the process, deduplicating records, and screening in stages. For a student review, the practical translation is: write your inclusion criteria first, search more than one source, keep a record of what you searched, and remove duplicates before screening.
If you want a scholarly search interface to run those queries, WisPaper search is one entry point for finding academic papers. As you screen, save the keepers into a library so the structure above has something to organize — My Library is where you save or upload papers and organize them. For longer literature-review tasks, Scholar Agent fits the literature review use case.
When you need to ask questions across the papers you have already collected, Library QA lets you ask questions based on papers uploaded to My Library or added from search results. That is useful for checking what a set of saved papers says about a sub-question before you commit a theme to your outline.
A deadline example: rubric, limited access, supervisor feedback
Suppose the rubric weights synthesis heavily, your library access is limited to a handful of databases, and your supervisor returns comments one week before the deadline. Here is how the hybrid structure absorbs each constraint.
Rubric. Because the rubric rewards thematic synthesis, collections should mirror themes, not databases. If your collections are named after where you found papers, the draft will read like a list of sources rather than an argument.
Limited access. With fewer databases, each search matters more. Document the sources you did search and the terms you used, following the Cochrane emphasis on documenting the process, so the methods section can state exactly what was covered.
Supervisor feedback. When your supervisor asks for more on one theme, create or rename a collection for it and tag incoming papers supervisor-suggested. A saved search for that tag, filtered to unread status, becomes your to-do list for the final week.
Reporting. If your review follows systematic conventions, PRISMA 2020 provides a reporting checklist, expanded explanations, an abstract checklist, and flow-diagram templates for original and updated systematic reviews, covering transparent reporting of search, selection, and synthesis methods. Even a course paper benefits from knowing which of those reporting elements your rubric expects.
Decision table
| Job | Collections | Tags | Status labels | Saved searches |
|---|---|---|---|---|
| Group by argument | Strong — one item in multiple collections | Weak — no order | Weak | Weak — a view, not a home |
| Cross-cutting attributes | Weak — single hierarchy | Strong — multi-valued | Narrow | Strong when built on tags |
| Track reading status | Weak | Workable with a fixed vocabulary | Strong | Strong as a filtered view |
| Surface subsets on demand | Weak | Workable | Weak | Strong — updates automatically |
| Absorb supervisor feedback | Strong — add or rename a collection | Strong — add a tag | Weak | Strong — saved search for the tag |
Read the table by row, not by column. The best structure is the one where every row has a strong answer, which is why the hybrid wins.
Making the submission decision
Here is the concrete decision for a deadline review. Use collections as your primary structure, tags for cross-cutting attributes and status, and saved searches as your working views. Do not choose a single feature and stretch it to cover every job.
In practice, that means three actions before you write another paragraph:
- Freeze your outline into collections and move every saved paper into exactly one theme, or two where it genuinely serves two arguments.
- Write down your tag vocabulary — method, study type, and a short status set — and apply it during screening, not afterward.
- Build two saved searches: unread items per theme, and supervisor-suggested items not yet read.
Then check your citations before submission. TrueCite checks BibTeX against real academic databases to flag hallucinated references, which is a sensible final pass when your reference list has grown quickly. If your work is organized as a larger project rather than a single paper, Research Projects is the area for creating and managing a project.
The submission decision itself is simple: submit when every collection maps to a section of the draft, every paper in those collections carries a status tag, and both saved searches return nothing unread that the rubric requires. That is a checkable condition, not a feeling.
FAQs
Keep Reading
Zotero vs. a Spreadsheet for Tracking Evidence: Choosing the Right Tool for an Auditable Review
When you are preparing a manuscript, a revision, or a grant-related evidence summary, the question is rarely "which tool is better?" It is "which tool keeps my method trail auditable?" Zotero and a spreadsheet solve diff
A Citation Moved but the Claim Did Not: Repairing a Drifted Reference in Your Manuscript
A citation has "moved" when the identifier in your manuscript no longer points to the work that actually supports the sentence. The DOI resolves, the link opens, the reference looks plausible — but the destination has ch
A Clinical Team Needs an Evidence Brief by Tomorrow: A Practical Workflow
A request for an evidence brief "by tomorrow" is really a request for a defensible decision aid: a short document that states a focused question, shows how the evidence was found and selected, separates what the studies